← All IntelIntel / article
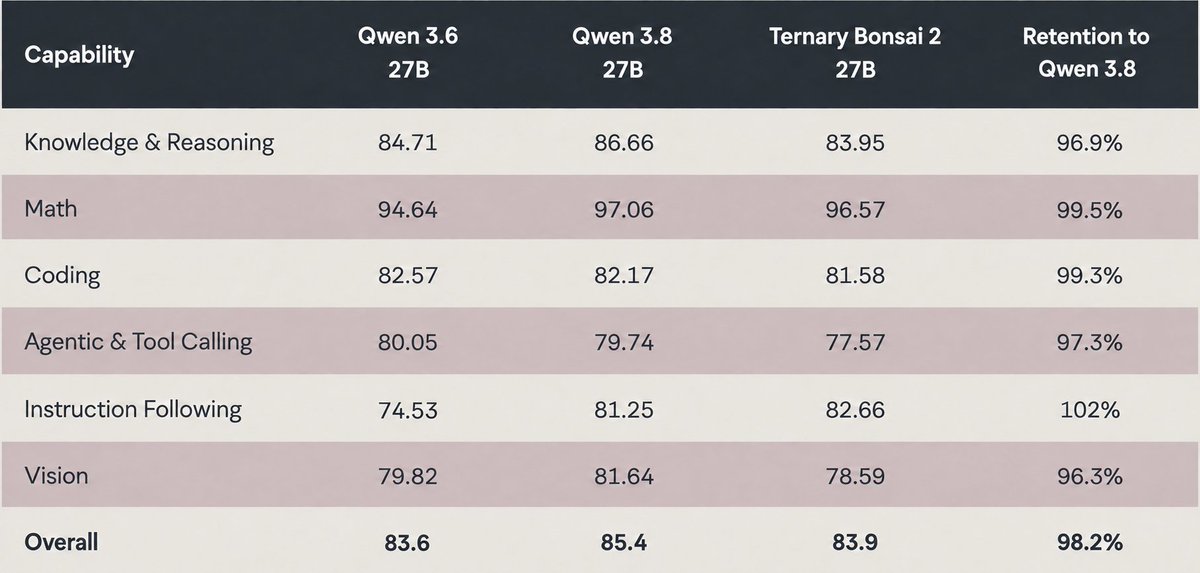
Bonsai 2 27B: Near-Lossless Compression in a 9x Smaller Footprint
- Source
- simonwillison.net
- Date
Key takeaways · AI-distilled
- The Ternary-Bonsai-2-27B GGUFs do not load in stock llama.cpp. Willison used a prebuilt macOS arm64 runtime from Prism ML's llama.cpp fork (release prism-b10685) with the roughly 5.95 GB PTQ1_0 GGUF from Hugging Face.
- His llama-server command sets GPU layer offload to 99 (-ngl 99), enables flash (-fa on) and a 32,768-token , which serves both llama-server's built-in web UI and an OpenAI-compatible /v1 endpoint.
- He queried the local server from the CLI with 'llm openai endpoint' pointed at http://127.0.0.1:8331/v1, so the compressed model can be called like any OpenAI-style API.
- Willison treats his speed numbers as suspect: throughput moved from about 20 to 44 tokens per second after a restart, and startup logged that the Metal tensor API was unsupported and disabled, so he suspects something was not working right.
Terms in this piece · Glossary
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Why it matters
Provides a tested, copy-pasteable path to running a heavily compressed 27B model locally, useful for anyone evaluating extreme schemes without wading through undocumented fork setup themselves.
Read the source simonwillison.net
Recommended reads
Comments
Checking sign-in…
Loading comments…