Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.
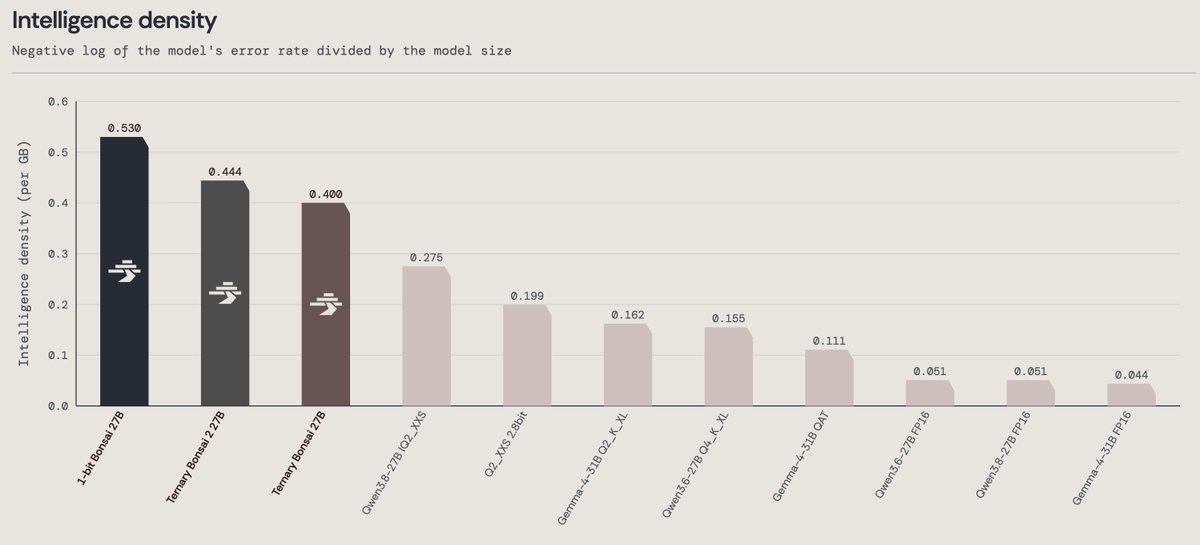
On an intelligence-density basis, Bonsai 2 27B is a clear outlier relative to both full-precision models and other low-bit alternatives.
Many low-bit models become deployable only with a meaningful quality tradeoff. Bonsai 2 pushes the frontier toward significantly higher capability at the same memory footprint.
This is where higher retention matters most: fewer derailments across multi-step tasks, fewer silent failures as the state evolves, and better consistency from one decision to the next.
Here is Ternary Bonsai 2 27B running an agentic coding workflow with Cline on an NVIDIA GeForce RTX 5090 GPU.
Computer use is another strong test.
The model has to repeatedly interpret state, choose the next action, and stay coherent across a long sequence of steps, exactly where small capability gaps become visible.
Here is Bonsai 2 27B running a computer-use workflow locally on the NVIDIA GeForce RTX 5090 GPU.
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
Why it matters
A meaningfully smaller model that keeps most full-precision capability lets agentic coding and computer-use workloads run locally on consumer GPUs without the usual quality tradeoff of aggressive quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition →.

 Read the full thread on X ↗