Which tokens does a hybrid model predict better?
- Source
- allenai.org
- Date
Context
Olmo Hybrid's advantage depends on what it is predicting. In Ai2's comparison with a closely matched , it predicted meaning-bearing words particularly well, but its lead nearly vanished when the next text simply repeated an earlier passage. Both models received the same preceding text, and researchers compared the probability each assigned to the actual next token. The analysis reports these patterns.
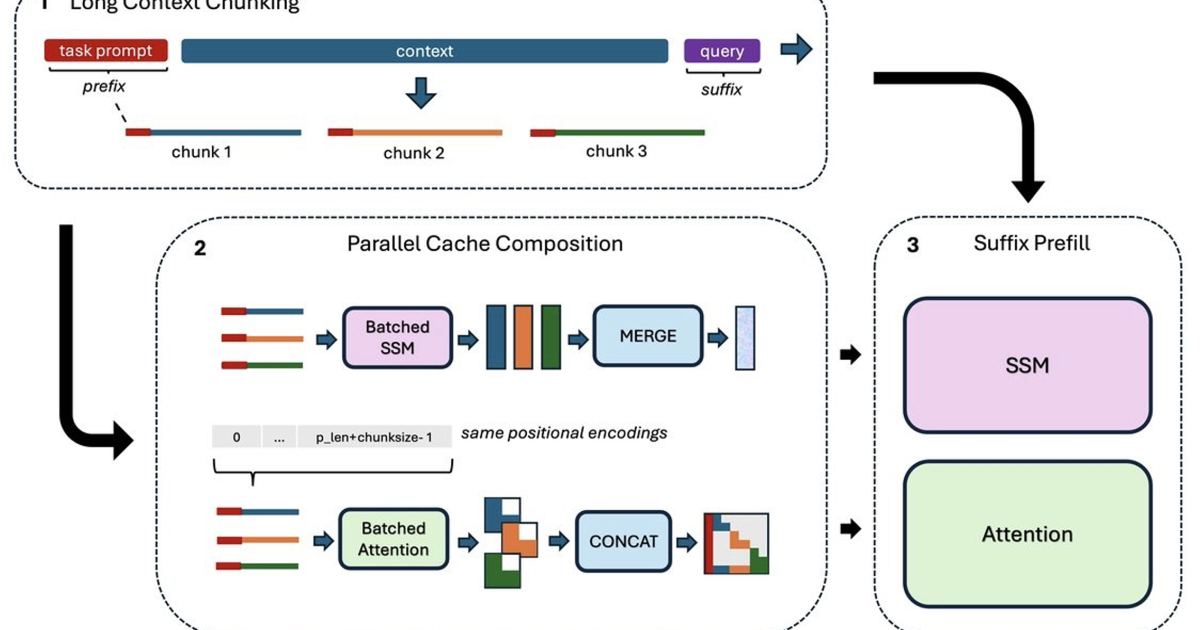
The hybrid combines , which can consult earlier text directly, with recurrent layers that update a compact running memory. The findings suggest evaluating these architectures separately on copying and other predictions: an average across all text can conceal their different strengths. The proposed connection between recurrent memory and better state tracking remains an interpretation.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…