GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints
Source
arxiv.org
Author
Joshua Ainslie et al.
Date
Context
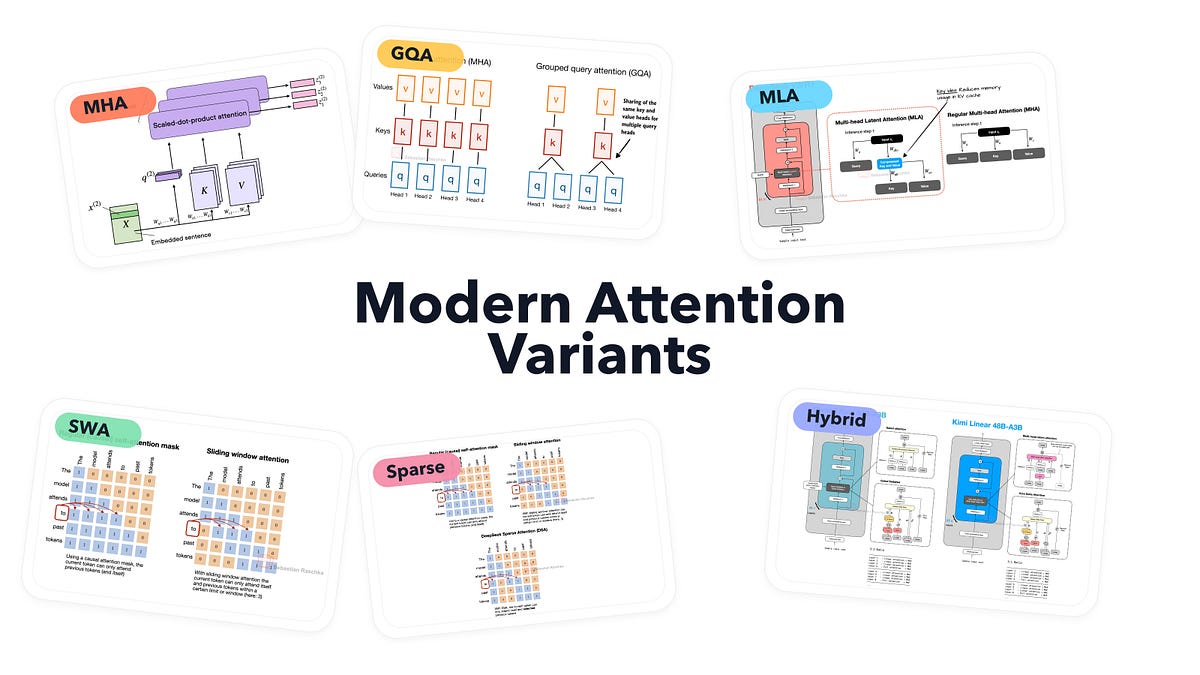
Grouped-query attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → offers a compromise between generation speed and model quality. Attention heads consult stored representations called keys and values. Conventional multi-head attention gives each head its own set; multi-query attention shares one set across all heads. GQA instead divides the query heads into groups, with each group sharing keys and values. The 2023 paper reports quality close to multi-head attention and speed comparable to multi-query attention after additional training. It also studies converting existing checkpoints, so adopting this tradeoff need not require training a new model from the beginning.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.