A Visual Guide to Attention Variants in Modern LLMs
- Source
- magazine.sebastianraschka.com
- Author
- Sebastian Raschka, PhD
- Date
Context
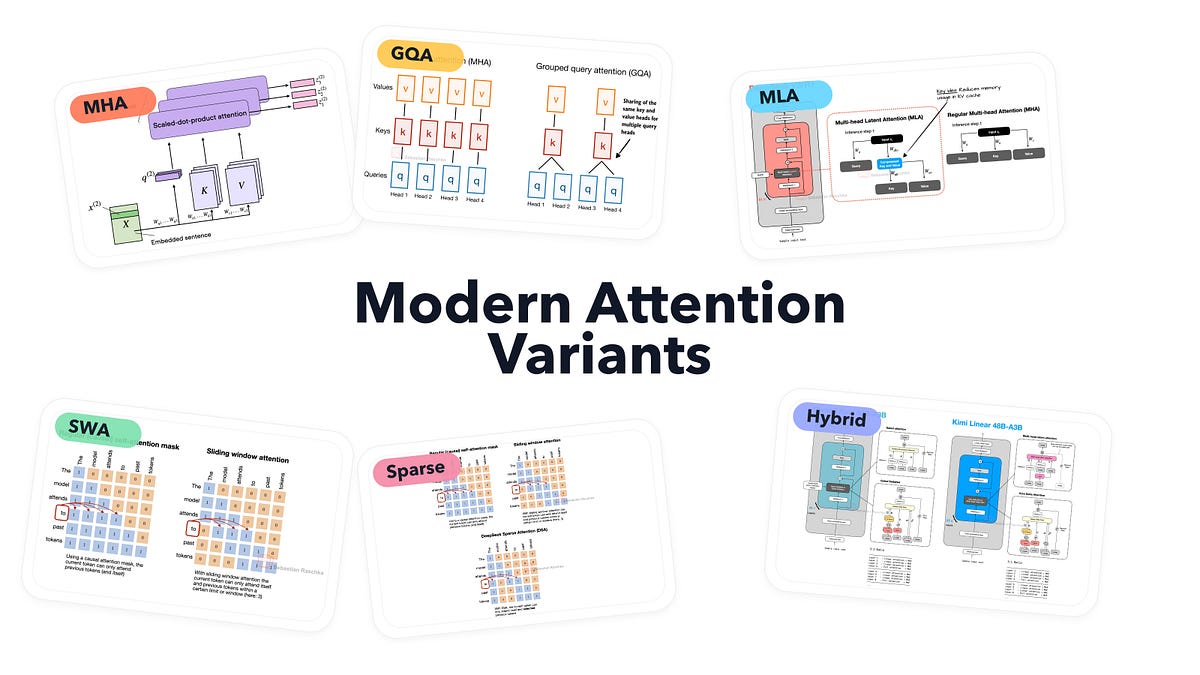
Grouped-query reduces the amount of earlier-text information a model must store by letting several attention heads share it. An attention head is one parallel way of matching the current text to relevant . In Sebastian Raschka's visual guide, standard multi-head attention gives each head its own keys and values; grouped-query attention shares those representations while keeping separate queries.
The result is fewer key-value representations to retain and retrieve as the context grows. It builds on the KV-cache mechanism: caching avoids recomputation, while sharing reduces how much must be cached. These are complementary ways to make text generation less expensive.
- Attention was invented to fix an RNN bottleneck. An encoder squeezed a whole sentence into one hidden state, so the decoder could not reach back to the specific source words it needed; attention lets each output position read the full input directly.
- Q, K, and V have distinct jobs: the query is what a is looking for, the key is what each token advertises for matching, and the value is the information mixed in once the weights are set.
- The attention matrix is not a stored object. It falls out of QK^T passed through softmax, one row per token, with future positions masked off in a decoder-only model.
- GQA, or grouped-query attention, keeps every query head but has several of them share one set of key/value projections. Fewer KV heads means a smaller , so it is a memory win that leaves the rest of the decoder recipe alone.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
“In my opinion, hybrid architectures are still a novelty, and the main selling point is mainly (long-context) efficiency versus just modeling performance.”
Sebastian Raschka
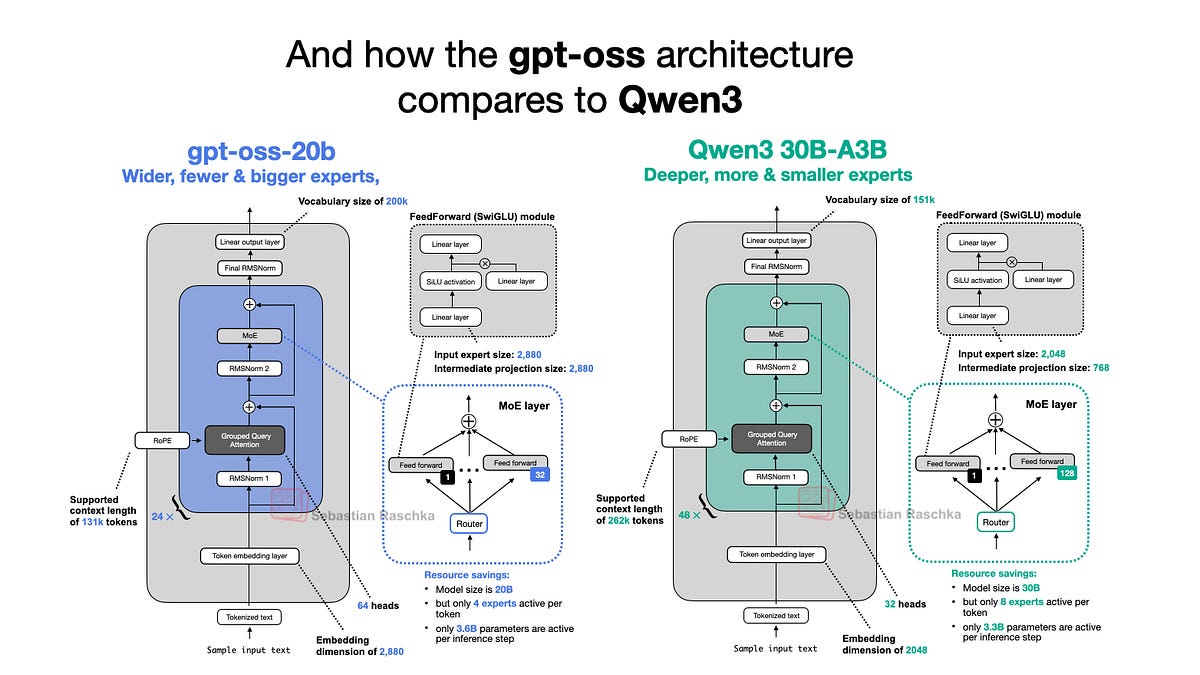
“I find that I get better tok/sec throughput when running LLMs locally using more classic setups like GPT-OSS with grouped-query attention.”
Sebastian Raschka
Checking sign-in…
Loading comments…