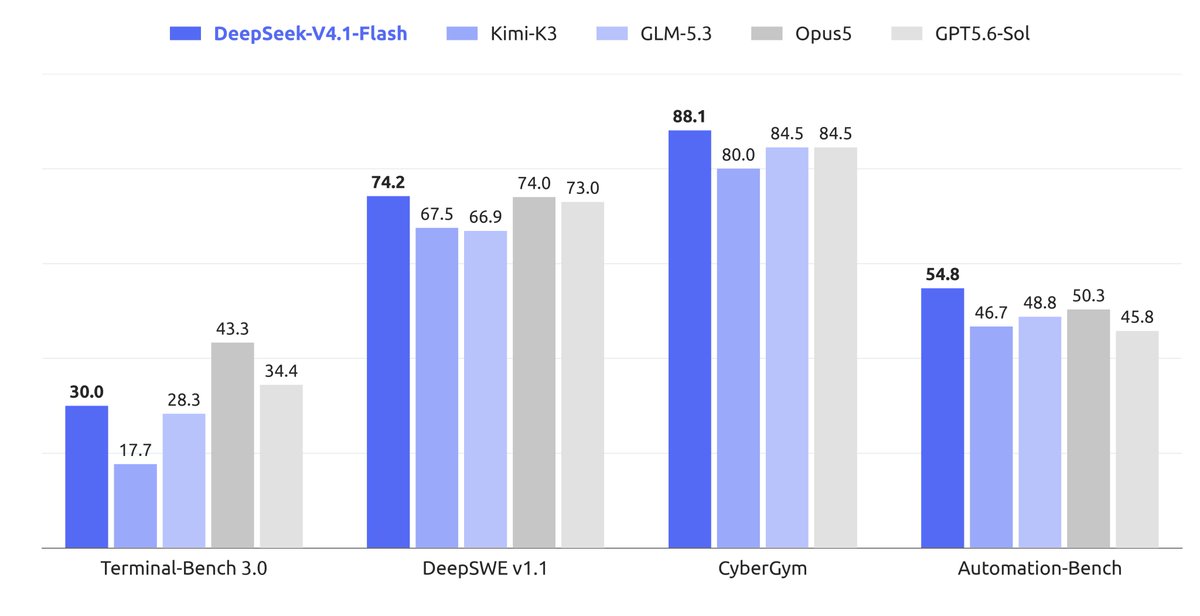
A new MIT-licensed DeepSeek V4.1 Flash checkpoint with fp8 weights and a multimodalA model that works with more than text — reading images, audio, or video, and sometimes generating them too.Full definition → pipeline tag can be served directly with vLLM or SGLang. Engineers building on DeepSeek models can evaluate it as a swap-in.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.