Minimax M31f
- Source
- minimax.io
- Author
- MiniMax editorial sitemap
- Date
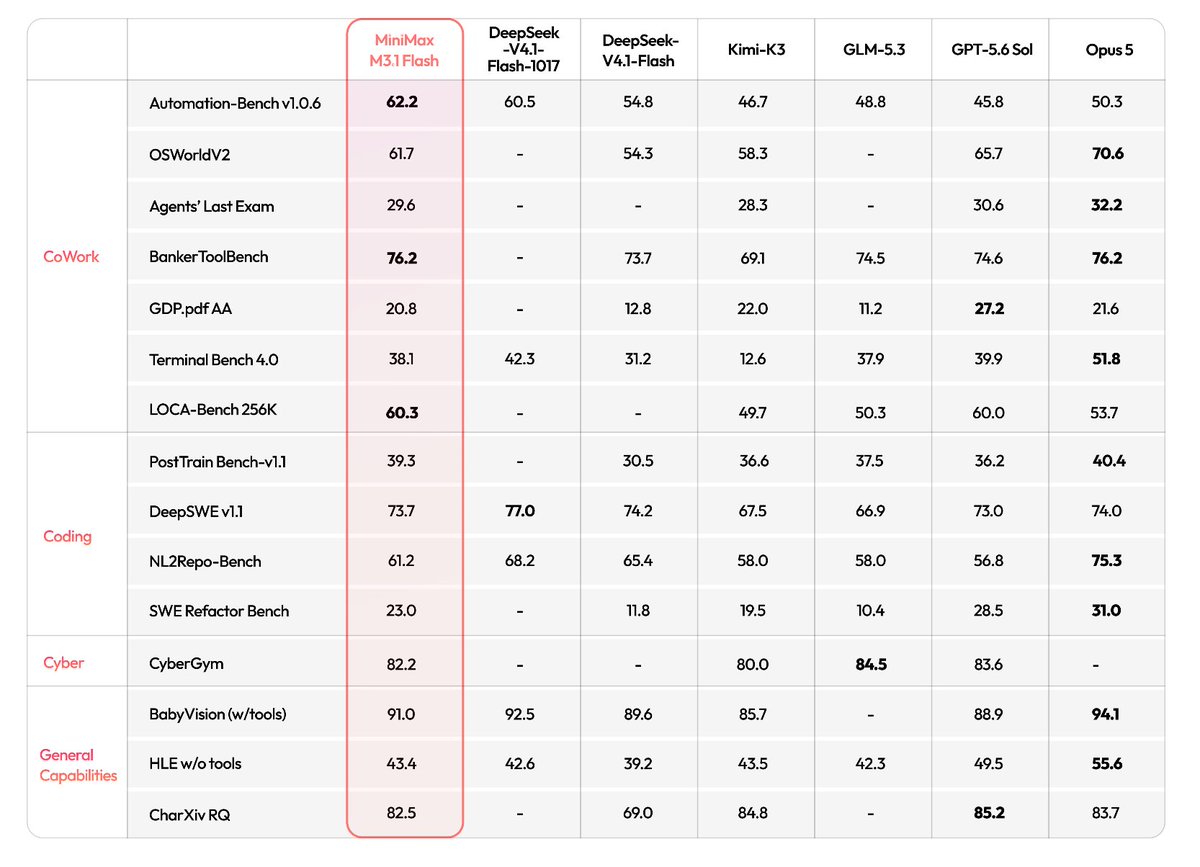
MiniMax released M3.1 Flash, a multimodal model aimed at agentic coding, computer use and security work. The company reports 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2 and 82% on CyberGym, and says the model runs roughly three times faster than M3 at about 70% lower usage cost. Pricing is $0.15 per million input tokens and $0.60 per million output tokens, with a 1M-token context window and tunable thinking depth. Every benchmark figure comes from MiniMax itself, so the scores are claims until outside evaluators reproduce them. The weights are due on Oct 23, which matters for that check: once they are public, teams can run the model on their own coding tasks instead of relying on vendor tables. Vercel AI Gateway is also serving M3.1 Flash free until Oct 22, but the free rate applies only when MiniMax serves the request, so callers have to pin MiniMax as the provider to avoid standard billing. For agent pipelines that make many model calls per task, a Flash tier at these prices changes the cost of each loop more than any single benchmark point does.
- MiniMax says Space Bunny, an anonymous model that processed more than 200 trillion , was an early version of M3.1 Flash.
- MiniMax attributes the speedup to more aggressive sparsity, reporting output speeds above 200 tokens per second in everyday use and a median (P50) above 170.
- Pricing is flat at $0.15 input, $0.60 output and $0.015 cached input per million tokens; MiniMax says overall usage cost on agentic tasks is 70% below its predecessor.
- Beyond the headline scores, MiniMax reports 76.2 on BankerToolBench and 29.6 on Agents' Last Exam, and says the model ranks first among Chinese models on both OSWorld V2 and ALE. These are vendor-reported.
- Weights are not out yet: M3.1 Flash ships through the MiniMax API, M Plan and MiniMax Code, with weights and a larger Pro model promised later.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…