MiniMax opens M3.1 Flash weights for coding and agents
- Source
- x.com
- Date

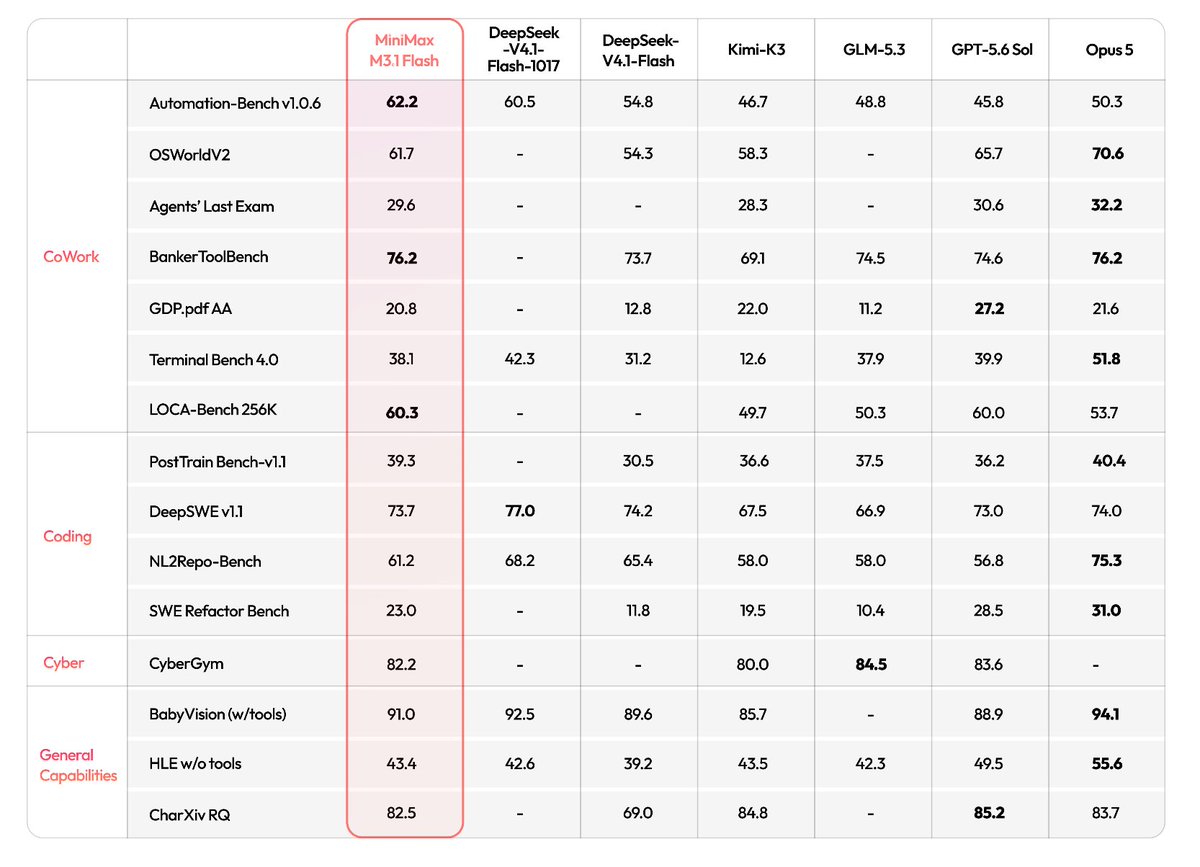
MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: https://t.co/JDYA1zZh54 ModelScope: https://t.co/DQcmOjTwhO API: https://t.co/fHRdSV7BwZ M Plan: https://t.co/LYnYZcsesu MCode for desktop: https://t.co/SGmLTI3fFU
A 428B with 23B active parameters, 1M and tunable thinking depth can now be self-hosted, with day-0 serving in two common inference stacks. Scores are MiniMax's own and unverified.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Checking sign-in…
Loading comments…