Building Vibe Draw Combining Elevenlabs Convai With Flux Kontext For Voice Powered Image Creation
- Source
- elevenlabs.io
- Author
- ElevenLabs editorial sitemap
- Date
Context
Vibe Draw is a weekend prototype that turns spoken descriptions into images by chaining three services inside the browser, described by Ryan Morrison of ElevenLabs in a blog post first published in June 2025, so its model choices reflect that time. The browser's built-in Web Speech API turns speech into text. A small set of rules decides whether that text asks for a new picture or a change to the current one. Black Forest Labs' FLUX Kontext, called through fal.ai, then draws or edits the image, while ElevenLabs text-to-speech, using the eleven_turbo_v2 model, speaks a short reply. The wording of those replies is not generated: each is picked at random from a few prewritten lines such as "Got it! Let me tweak that for you...", and they go through a queue so one finishes playing before the next starts.
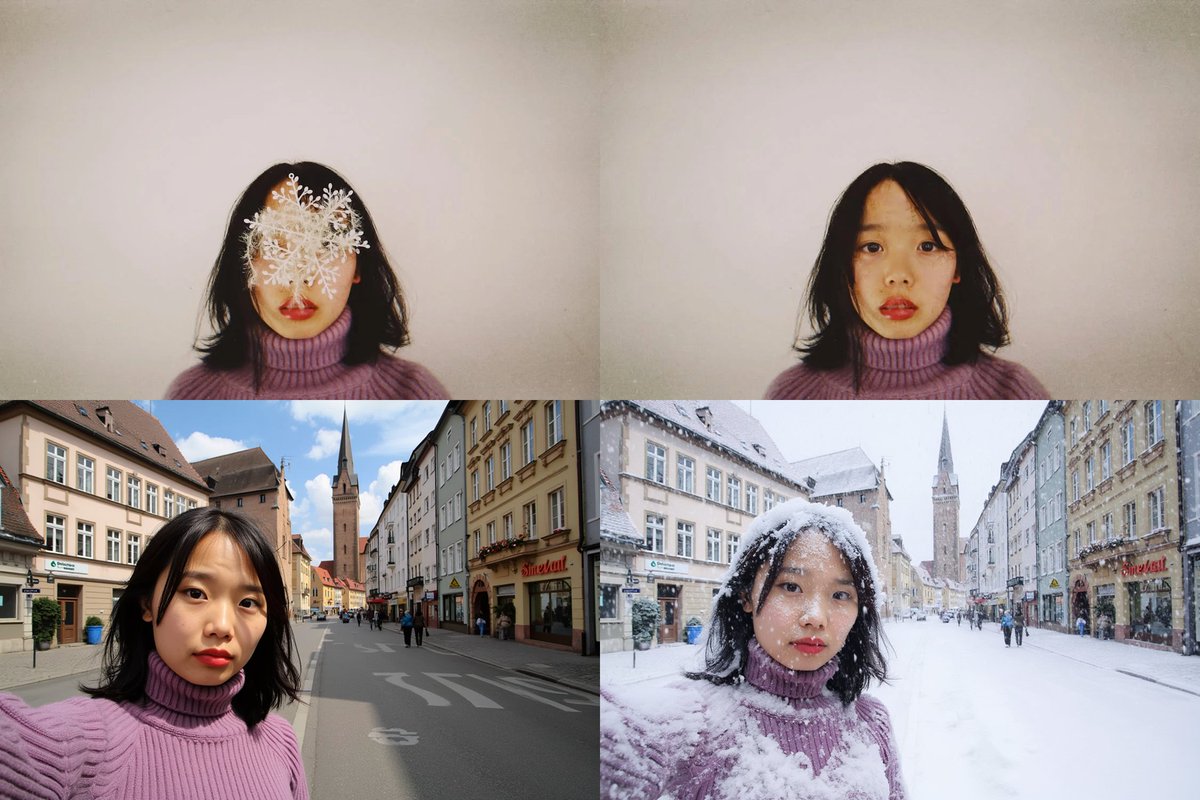
The generate-or-edit decision is plain keyword matching. The code checks the transcript against a list of edit keywords and contextual phrases, and it routes to editing only when an image already exists and one of those cues appears; anything else becomes a new image. That split works because Kontext covers both jobs. Vibe Draw sends new requests to a text-to-image endpoint and edits to a second endpoint that takes the current image plus the spoken instruction, the in- generation and step-by-step editing that Black Forest Labs described in its Kontext launch post. When a request seems too large for the editing API, the app appends "maintain composition but apply requested changes" to the instruction and, if the edit still fails, offers out loud to create a fresh image instead.
Two details matter for anyone reading the post as a blueprint. Although the post's URL mentions "Convai", apparently shorthand for ElevenLabs' Conversational AI product, the build described uses only the text-to-speech API; speech through Conversational AI appears only in the "What's next" list. And because everything runs client-side, the API calls go out from the browser, which the article says production deployments should instead proxy through a server for security. The post points to the full source code on GitHub but reports no measured latency, accuracy or user results.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
Checking sign-in…
Loading comments…