Unify routed around OpenAI's 15 request per second cache ceiling
- Source
- x.com
- Date

OpenAI's prompt cache makes a request 90% cheaper, but the cache key tops out around 15 requests per second. @HeggieConnor on how @unifygtm built its own routing around that limit, landing them close to a 95% cache hit rate.

@HeggieConnor @unifygtm Watch or listen to the latest Max Agency on your favorite podcasting platform. 🎧 Apple: https://t.co/VfE5h4auAT 🎧 Spotify: https://t.co/UhEMNqwxzf ⏯️ YouTube: https://t.co/Ldy6KnVu1O

Context
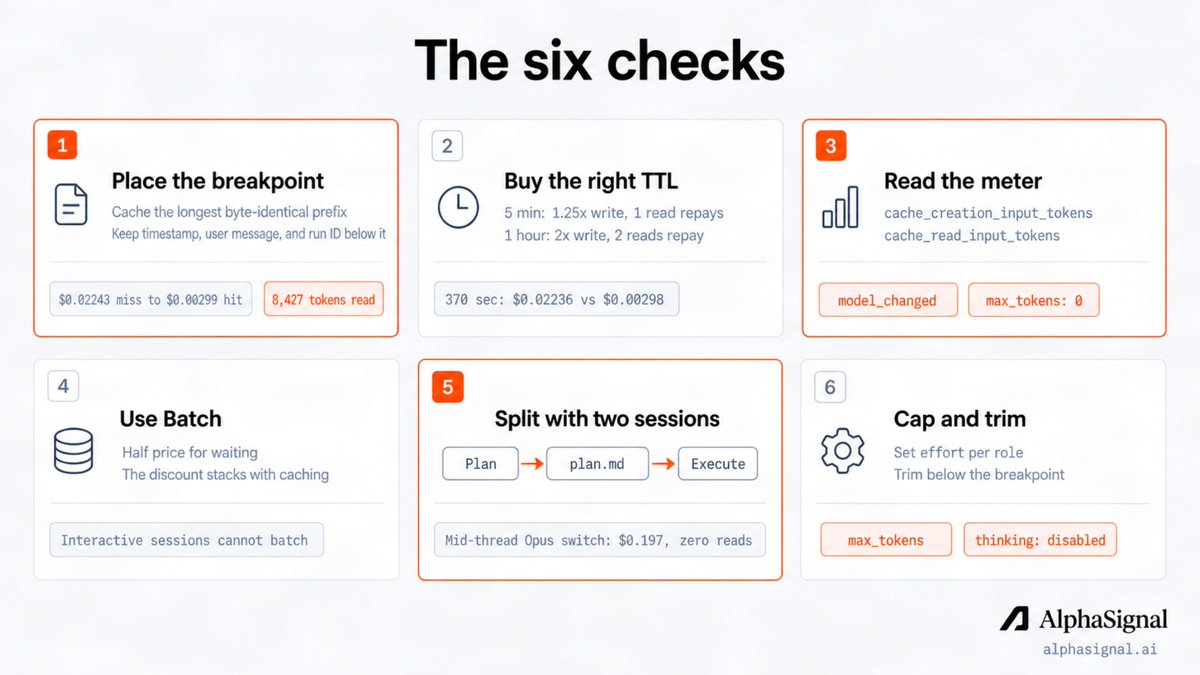
Unify, a company building AI tools for sales, describes spreading requests across cache keys so its agents can reuse shared instructions. avoids repeating computation on an unchanged prompt prefix, but a request must reach a machine holding the cached material, as OpenAI's documentation explains.
In LangChain's interview, the guest describes hashing user IDs into 16 groups and appending a random number from 1 to 30. The grouping lets users share cached system instructions and tool descriptions; the suffix distributes traffic across more keys. The intended balance is reuse without concentrating every request on one cache.
The numerical limit remains unresolved: the post and guest say 15 requests per second, while the documentation currently says traffic above 15 per minute can overflow to other machines. It also says GPT-5.6 and later handle cache routing automatically. Unify's account is a workload-specific design, not a universal recipe for current models.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.

Checking sign-in…
Loading comments…