LFM2.5-Encoders for Fast Long-Context Inference on CPU
- Source
- huggingface.co
- Author
- Liquid AI
- Date

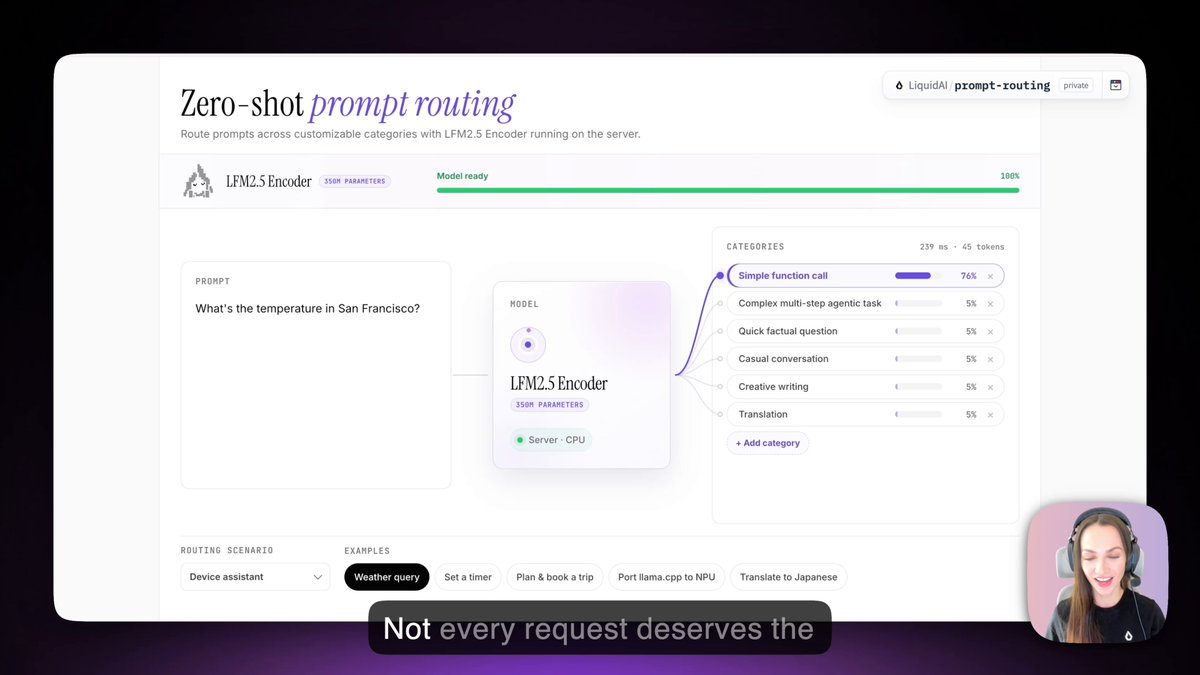
If you need classifiers, PII/intent detectors, rerankers or running on CPU, these 230M/350M encoders give 8K- and match or beat ModernBERT-base while running ~3.7x faster at long context — a practical way to drop GPU dependency from your text-processing pipeline.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
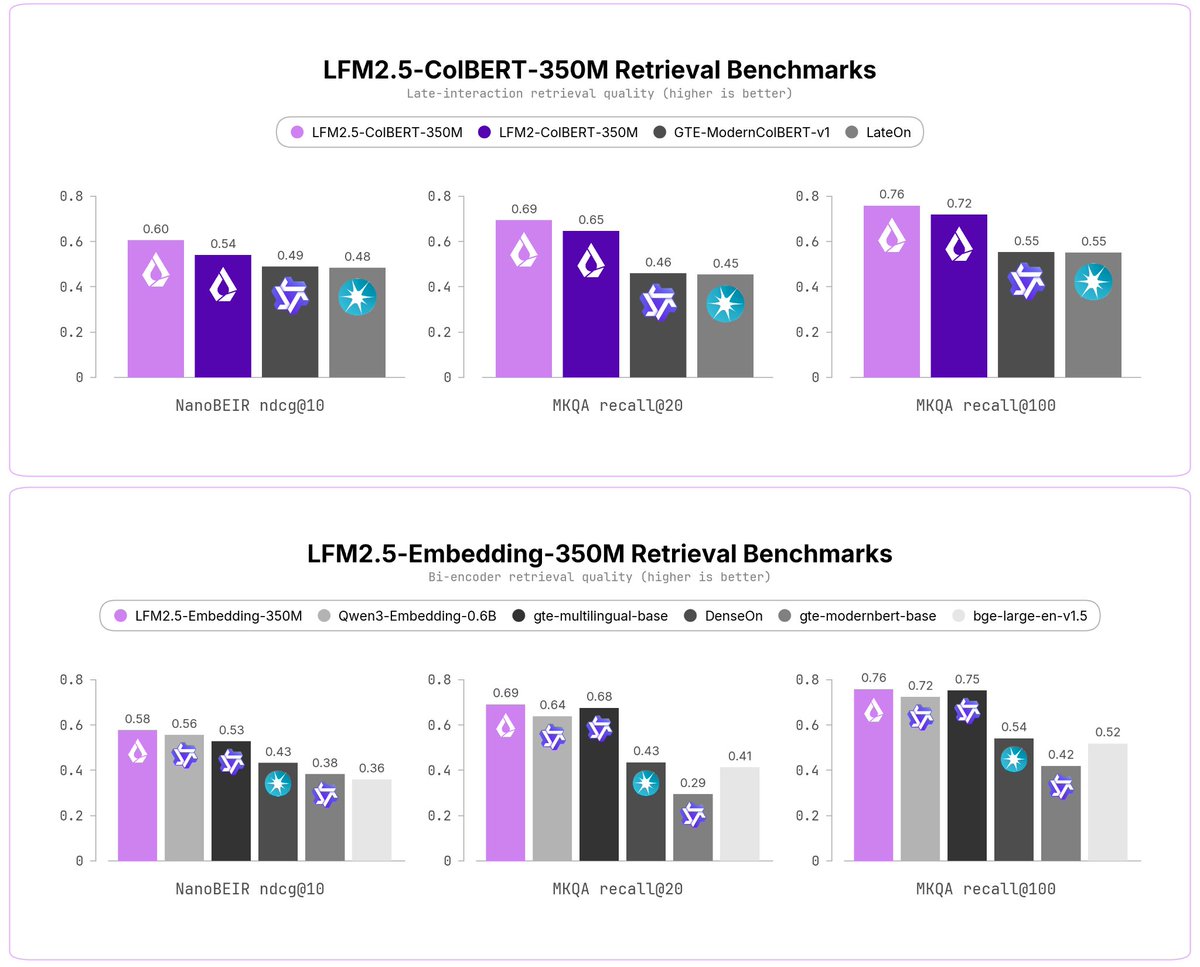
“They match the quality of larger models but stay fast as inputs get longer. This means you can run document-scale jobs on the hardware you already have, even on CPU.”
“LFM2.5-Encoder-350M ranks fourth of the 14 models. The three ahead of it are all larger, including a 3.5B model nearly 10 times its size.”
“At 8,192 tokens, ModernBERT-base takes over a minute and a half per forward pass versus about 28s for LFM2.5-Encoder-230M. This is about 3.7x faster.”
“For developers, that means you can scan or classify a full contract, transcript, or long support thread in under 30 seconds on a laptop CPU.”
Checking sign-in…
Loading comments…