Fish Audio's Drama 3 lets you direct TTS performances with inline tags
- Source
- fish.audio
- Author
- Fish Audio
- Date
Context
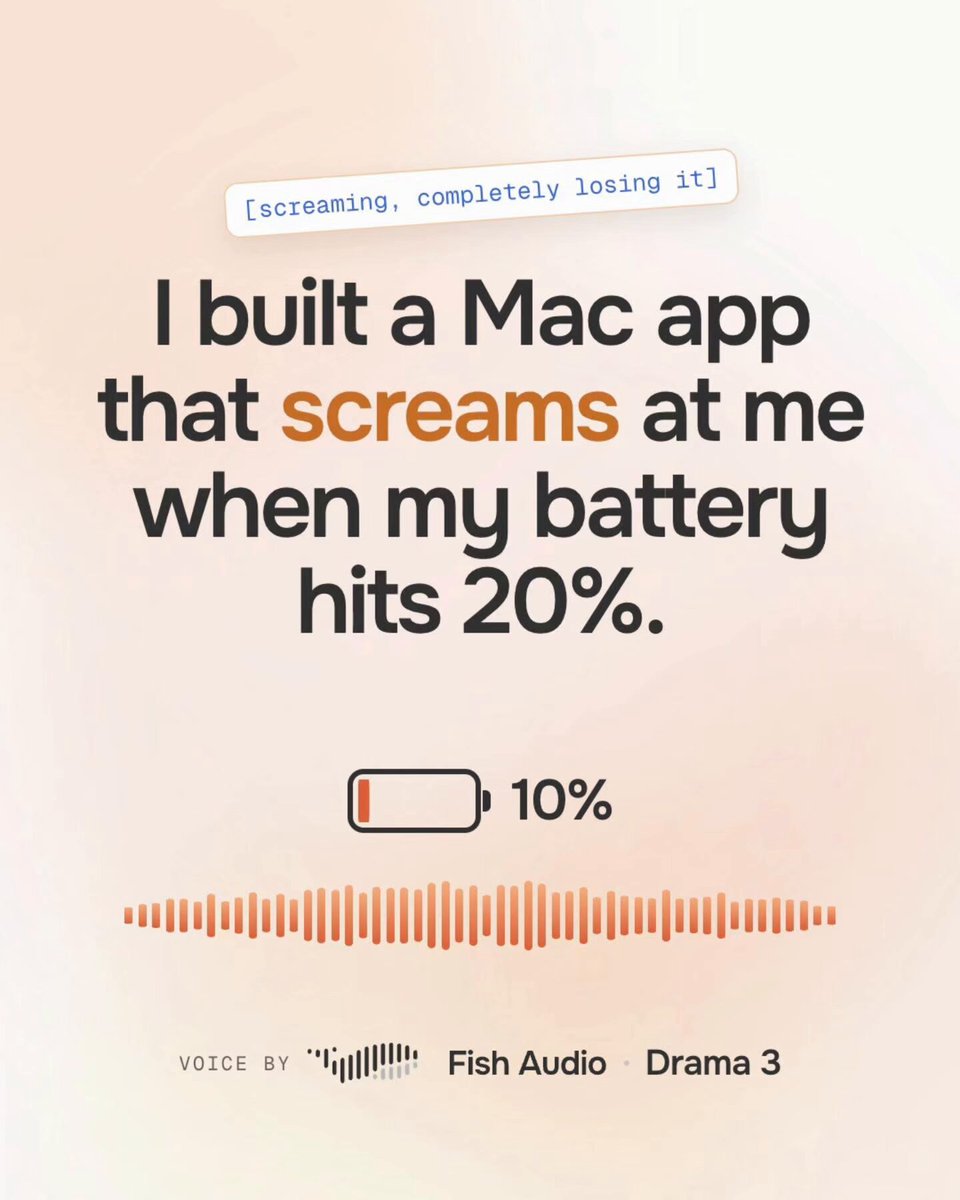
Drama 3 is a text-to-speech model from Fish Audio in which the instructions for how a line should sound live inside the script as ordinary text (fish.audio). Put a description in square brackets before a line, such as being warm and relaxed or barely holding it together, and the model performs the line that way. The same brackets hold short cues, such as a sigh, a laugh, a breath or a pause, at the exact spot they should occur. For finer control, paired tags for effects like whispering, slowing down or stressing a word wrap only the selected words, so the rest of the sentence is unaffected.
Fish Audio says directions can be written in English or in the writer's own language and the performance follows them either way, and that multi-speaker scenes are generated together in one pass once each speaker has a voice. For people who do not want to write directions from scratch, an Auto Tag feature adds them to a plain script as a starting draft to keep or rewrite. Because the directions are text, they travel unchanged through the API: requests set the model to drama-3 and send the tagged script as is.
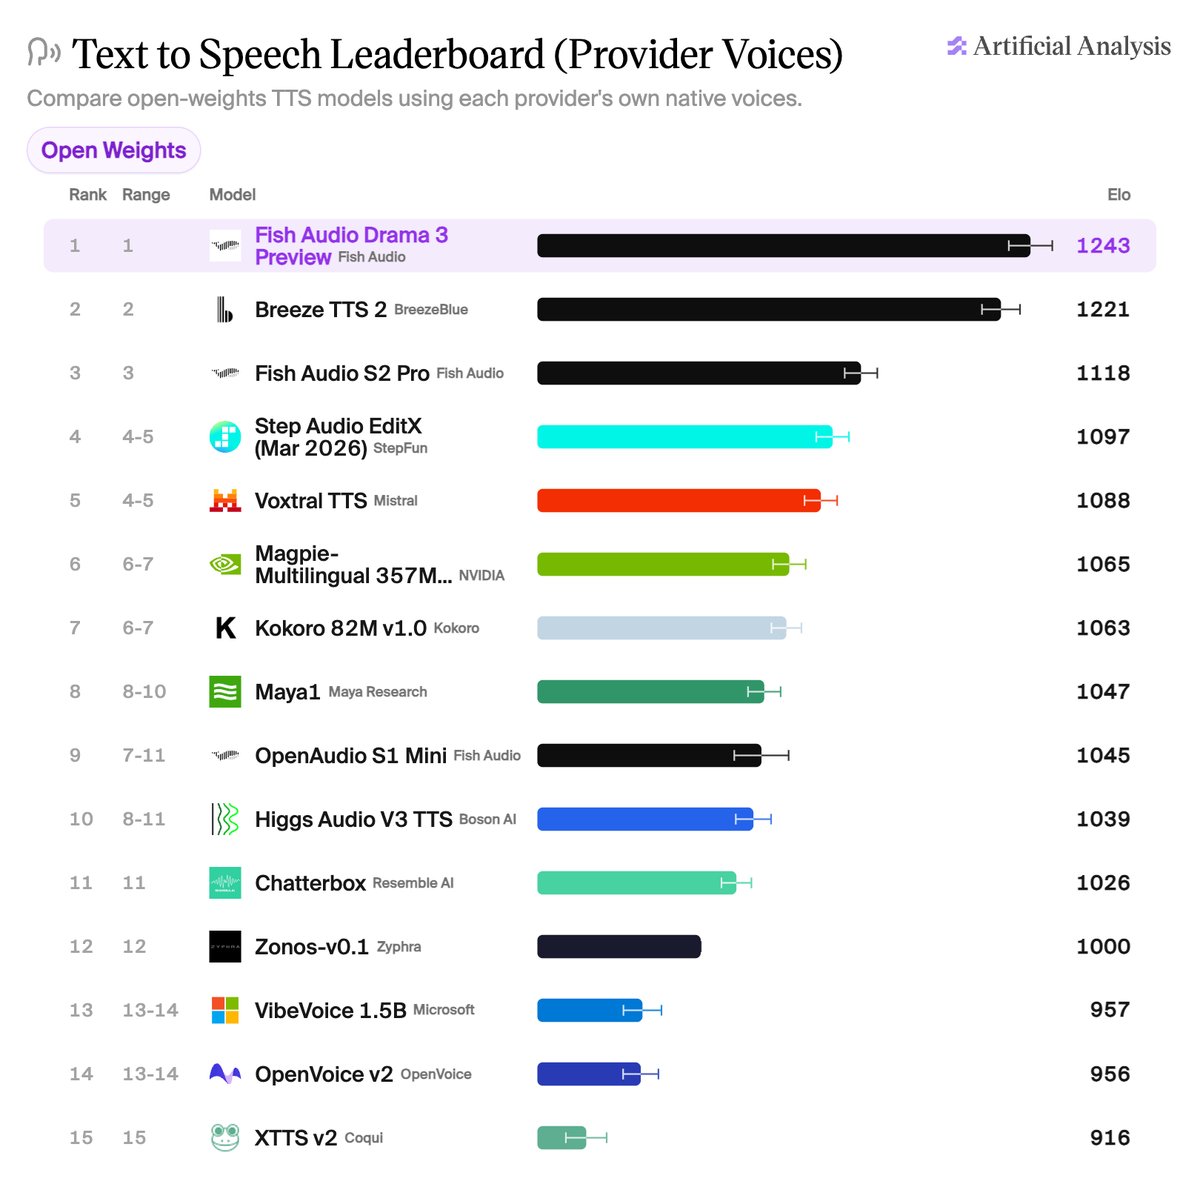
The page labels this a Preview. Fish Audio's FAQ says results vary between takes, suggests generating several and picking the best, and says the model will keep changing during the preview. The company's earlier launch post covers the release itself; this page is the practical guide to how direction is written.
- Fish Audio's Drama 3 Preview takes natural-language performance directions in square brackets, such as [sigh] or [barely holding it together], placed exactly where the effect should happen in the script.
- Paired scoped tags like <whisper> or <slow> apply an effect only to the words they wrap, so delivery can change mid-sentence without affecting the rest of the line.
- Directions can be written in languages other than English, multi-speaker scenes are generated together in one pass, and an Auto Tag feature drafts directions for a plain script.
- Fish Audio says results vary between takes while the model is in preview and suggests generating several; the same tags work through its TTS API with the model header set to drama-3.
Checking sign-in…
Loading comments…