Fish Audio Drama 3 trades transcript rewards for human-preference rewards
- Source
- x.com
- Date

https://t.co/Yd1GwpdCTm
Context
Fish Audio says the main change in Drama 3, its new text-to-speech model, is what the model was rewarded for during training, not how it was told to perform. According to the launch post, the rewards for its previous S2 models favored clear transcription and similarity to the reference voice being cloned. A laugh, a shaky breath or a whisper can make a line better, yet those same sounds could lower both scores, even when the script asked for them. For Drama 3, Fish replaced them with one learned reward model trained on which takes people prefer. It hears the script and the reference voice, so accuracy, likeness and the requested performance all count together.
Directions are written into the script the way you would give them to an actor, as bracketed instructions such as choked up or through gritted teeth. They can change partway through a sentence, and paired tags can apply a direction to just a few words. The post says the direction can be written in a different language from the dialogue, across the model's 83 languages. Fish's evidence for the extra feeling is a set of side-by-side audio clips against S2.1 Pro, which could not be heard for this summary, so that part is Fish's own claim.
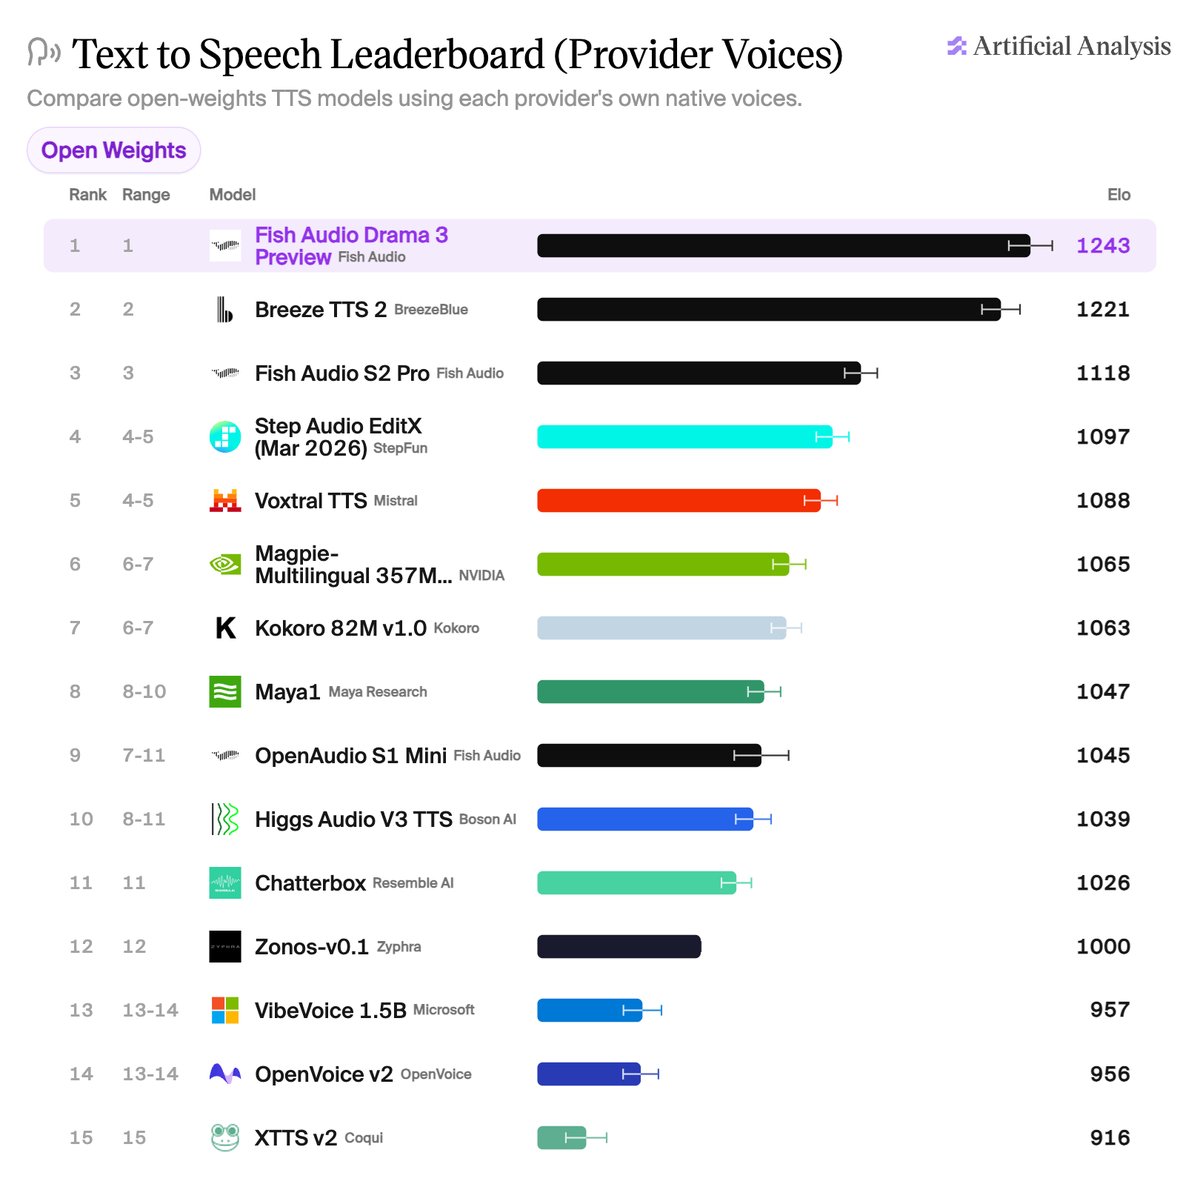
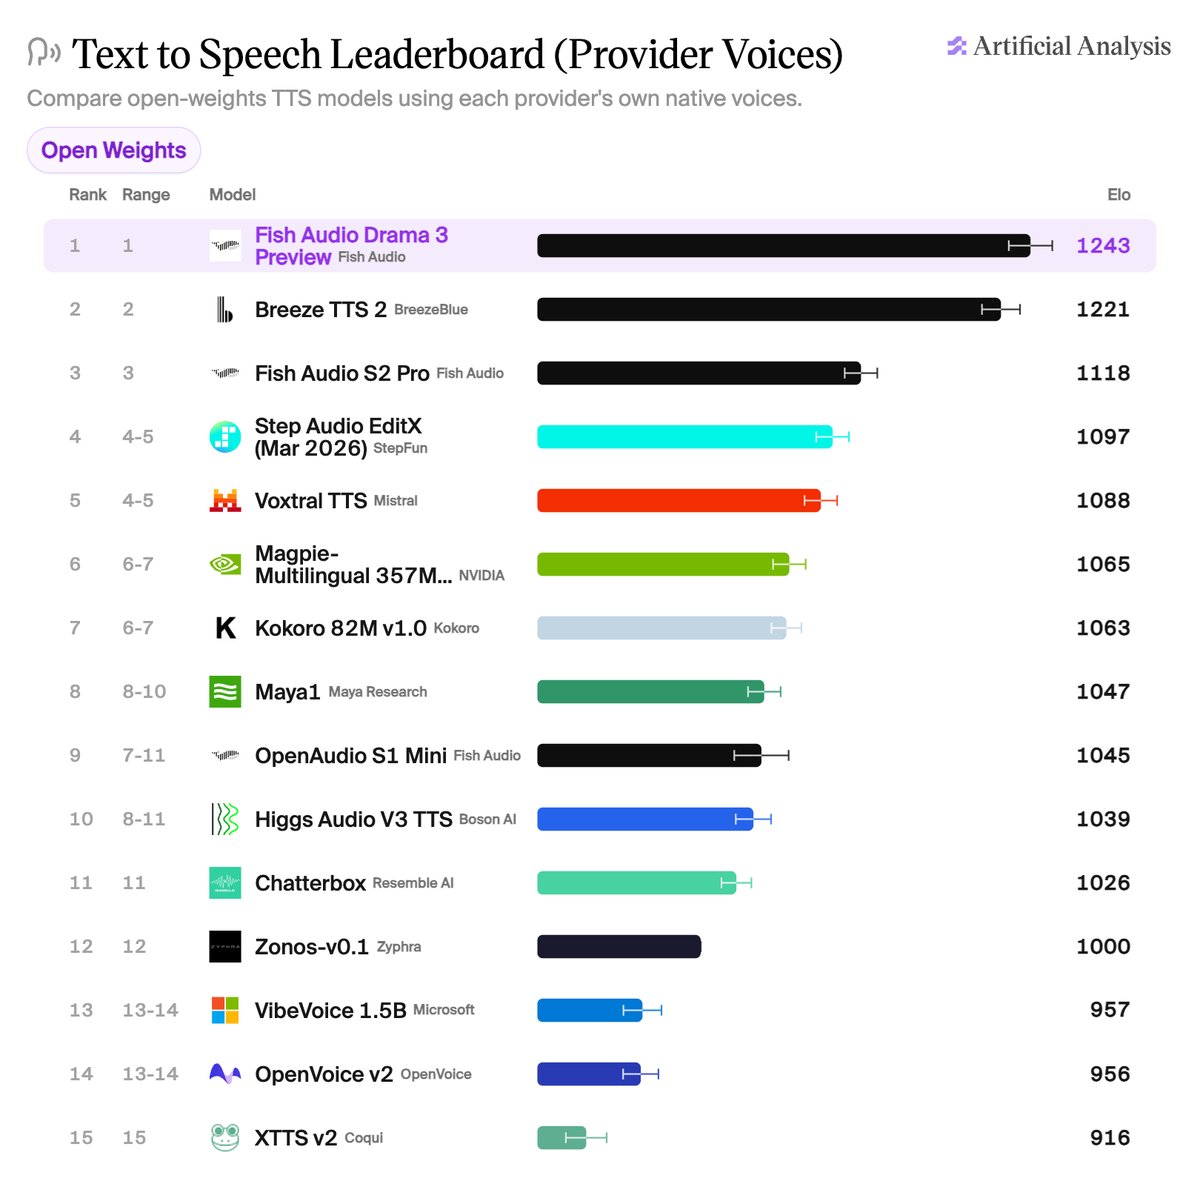
To show that clarity didn't suffer, Fish cites Artificial Analysis's Pronunciation Robustness , where human reviewers judge whether hard spans such as names, numbers, codes and -dependent words were said correctly. Drama 3 scored 93.2%, against 88.1% for S2.1 Pro, and exact sequences like file paths and email addresses rose from 79.4% to 86.3%. Fish calls it the top score at launch. Artificial Analysis's own post had Drama 3 Preview first, and a week later it reported Ant Group's Ming-3.0-tts tied with it. Fish also notes the benchmark measures pronunciation, not performance.
The model itself is a 35-billion-parameter , using about 3 billion parameters per token. Fish reports that its engine decodes one stream at 271 audio frames per second on a single H200, against 177 for S2, while cautioning that this is not end-to-end latency through the public API. Weights and code are released under the Fish Audio Community License v1.0. It allows free research and non-commercial use, and eligible commercial use while you and your affiliates earn under US$500,000 a year combined; hosted speech-generation services have separate requirements in the full license. On the API, existing users switch by setting the model header to drama-3, at a launch price of $10 per million characters, 80% off the $50 list price, through November 12.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…