AState Cuts Trillion-Parameter RL Weight Sync to Six Seconds
- Source
- x.com
- Date

Introducing AState, the 3rd #OpenSource component to ASystem! AState is a general state data management system for #reinforcementlearning tasks. It is currently deployed in Ling-1T RL training tasks, achieving a ⚡️breakthrough in cutting trillion-parameter weight synchronization time from minutes to ~6 seconds🚀 More features addressing critical issues like RL IO inefficiency and multi-session state recovery will be continuously open-sourced in subsequent releases. 👀Stay tuned!
Welcome to the ASystem's community! 📦 GitHub Repository: https://t.co/Qn9jd6on1v For the awesome Ling/Ring models trained by ASystem: 🤗 Hugging Face: https://t.co/wJfOOugBGE 🤖 ModelScope Community: https://t.co/H1XGr5PkRW
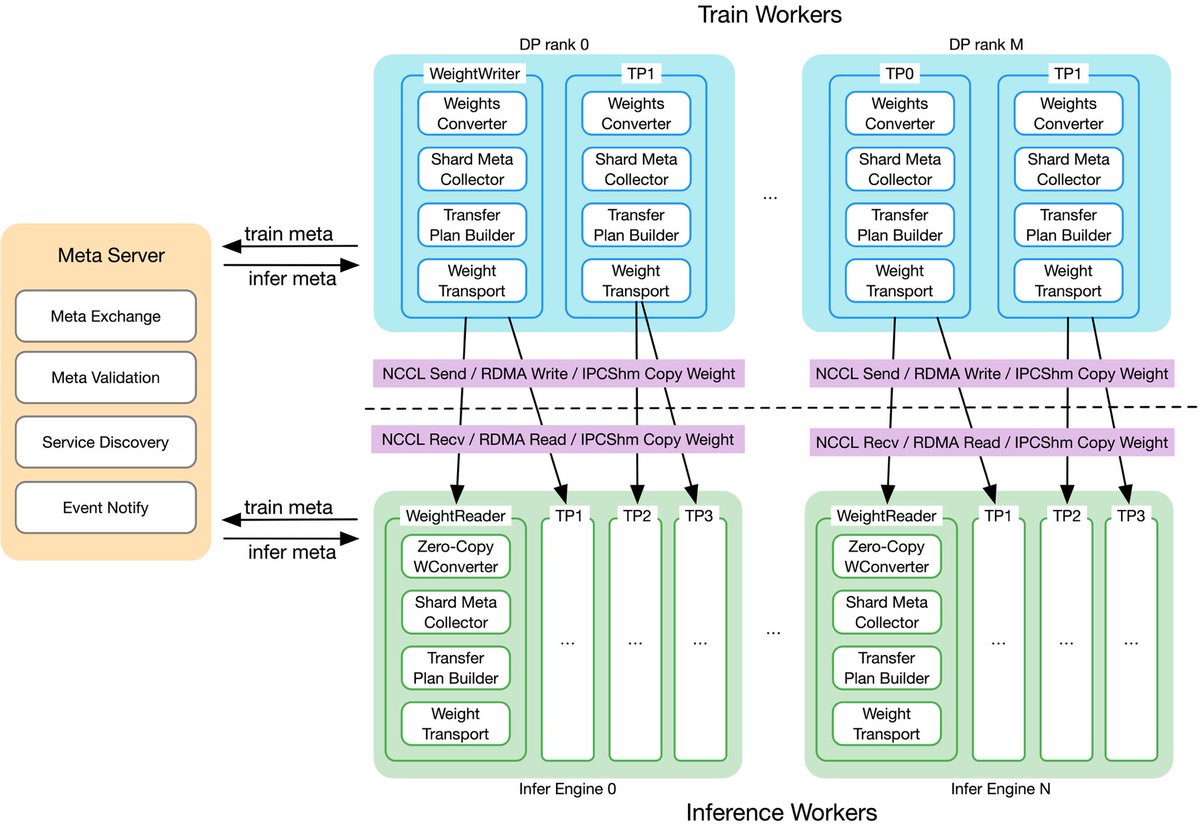
Core Features 1/3 🔁Efficient Transfer: AState supports automatic weight mapping (resharding) between nodes(train and rollout actors), utilizing zero-redundancy and in-place updates. This core mechanism significantly boosts trillion-parameter weight transfer efficiency, serving as the foundation for seconds-level synchronization.
Core Features 2/3 ⚖️Architectural Stability: AState fully leverages NUMA topology and hardware affinity to reduce cross-device latency. Through global execution planning, it achieves more balanced load distribution, effectively mitigating traffic hot spots and long-tail latency in thousand-card RL tasks.
Context
Moving updated weights from a training cluster to the GPUs serving rollouts is one of the slower steps in large reinforcement-learning loops. Ant Open Source introduces AState, the third open-source piece of its ASystem effort for InclusionAI's Ling and Ring models, as a state-management system built to handle that transfer. The company reports it automatically remaps, or reshards, weights between training and rollout nodes using zero-redundancy, in-place updates rather than copying a full new parameter set, and says this cut trillion-parameter weight synchronization on its Ling-1T RL training runs from minutes to about six seconds.
AState also leans on the physical layout of the machine: the team describes using NUMA topology and hardware affinity awareness to spread load evenly across a thousand-card cluster and reduce the long-tail latency that comes from a few slow stragglers. Its interfaces are described as tensor-native and not tied to a specific GPU memory budget, which the company says makes it adaptable across different RL deployment setups. Those broader compatibility claims, along with the detailed architecture, are laid out in a linked technical report that was not independently reviewed here.
Checking sign-in…
Loading comments…