← All IntelIntel / article
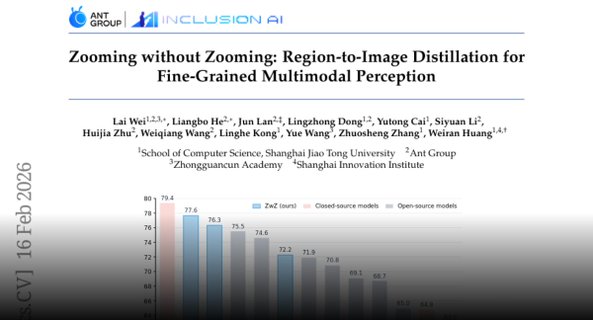
ZwZ2 trains vision models to connect evidence across image regions
- Source
- arxiv.org
- Author
- Ant Open Source
- Date
Why it matters
EvidenceConnect shows that verified single-image, multi-region questions used for RL training can improve spatial reasoning, long- and GUI- benchmarks without multi-image data. The code, data and 4B/9B/27B models are released, so the recipe can be reproduced.
Terms in this piece · Glossary
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Read the source arxiv.org
More from Ant Open Source
Recommended reads
Comments
Checking sign-in…
Loading comments…