Ollama served my 40k-context model at 4k, silently
- Source
- github.com
- Author
- satoshiakiyama
- Date
Context
A model's advertised capacity can differ from the amount its running server actually uses. In a report using Ollama 0.32.9 on Windows, the author found a Qwen model declaring 40,960 running with a 4,096-token window. A long test prompt received a successful response even though the server reported evaluating only 2,050 prompt tokens.
Setting the request's context window explicitly to 16,384 increased the evaluated input to 7,855 tokens and recovered a value placed at the beginning of the prompt. This makes the server's active window and evaluated-input count consequential when diagnosing apparent forgetting: the model may never have received the missing information. The finding is specific to the reported setup.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 articleBroken on Arrival: Silently Defective LLM Artifacts in Public Model Registries and How to Catch ThemAditi Patodiya
 articleQwen 3.8 27B is excellent, but it defaults to wildly overthinking thingssimonwillison.net
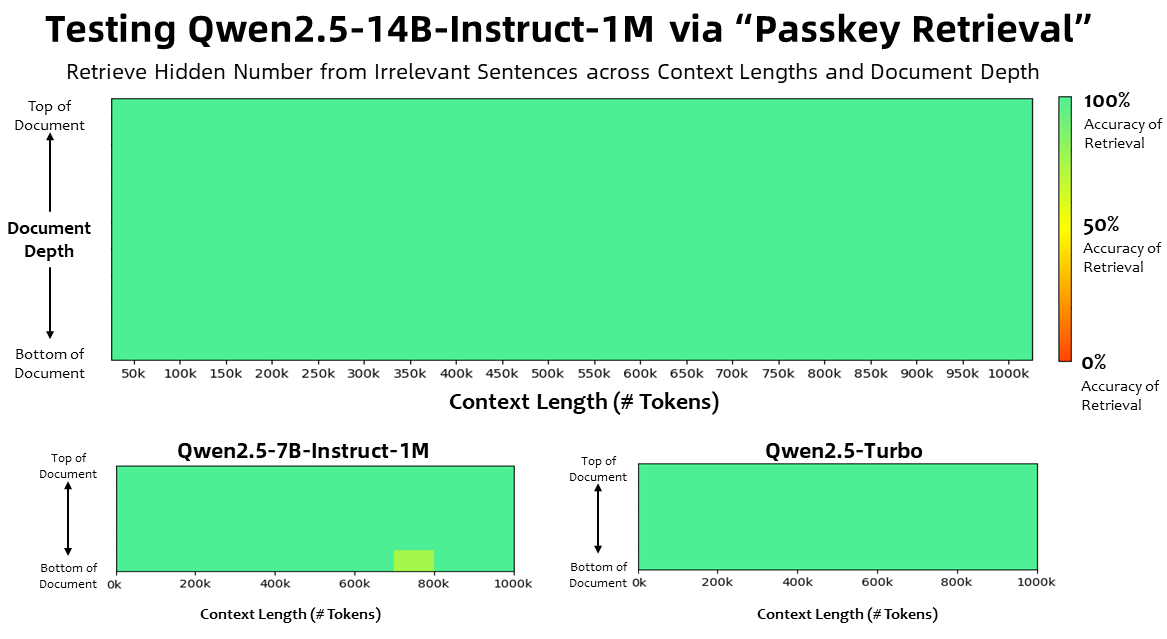 articleQwen2.5-1M: Deploy Your Own Qwen with Context Length up to 1M TokensQwen Team
Checking sign-in…
Loading comments…