Qwen2.5-1M: Deploy Your Own Qwen with Context Length up to 1M Tokens
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
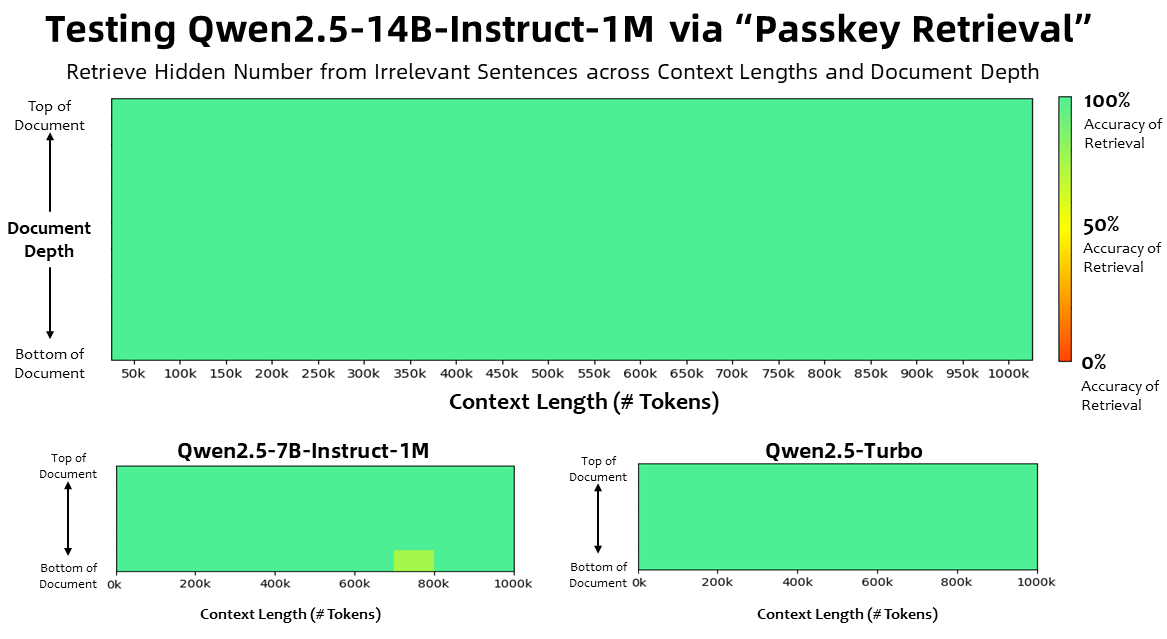
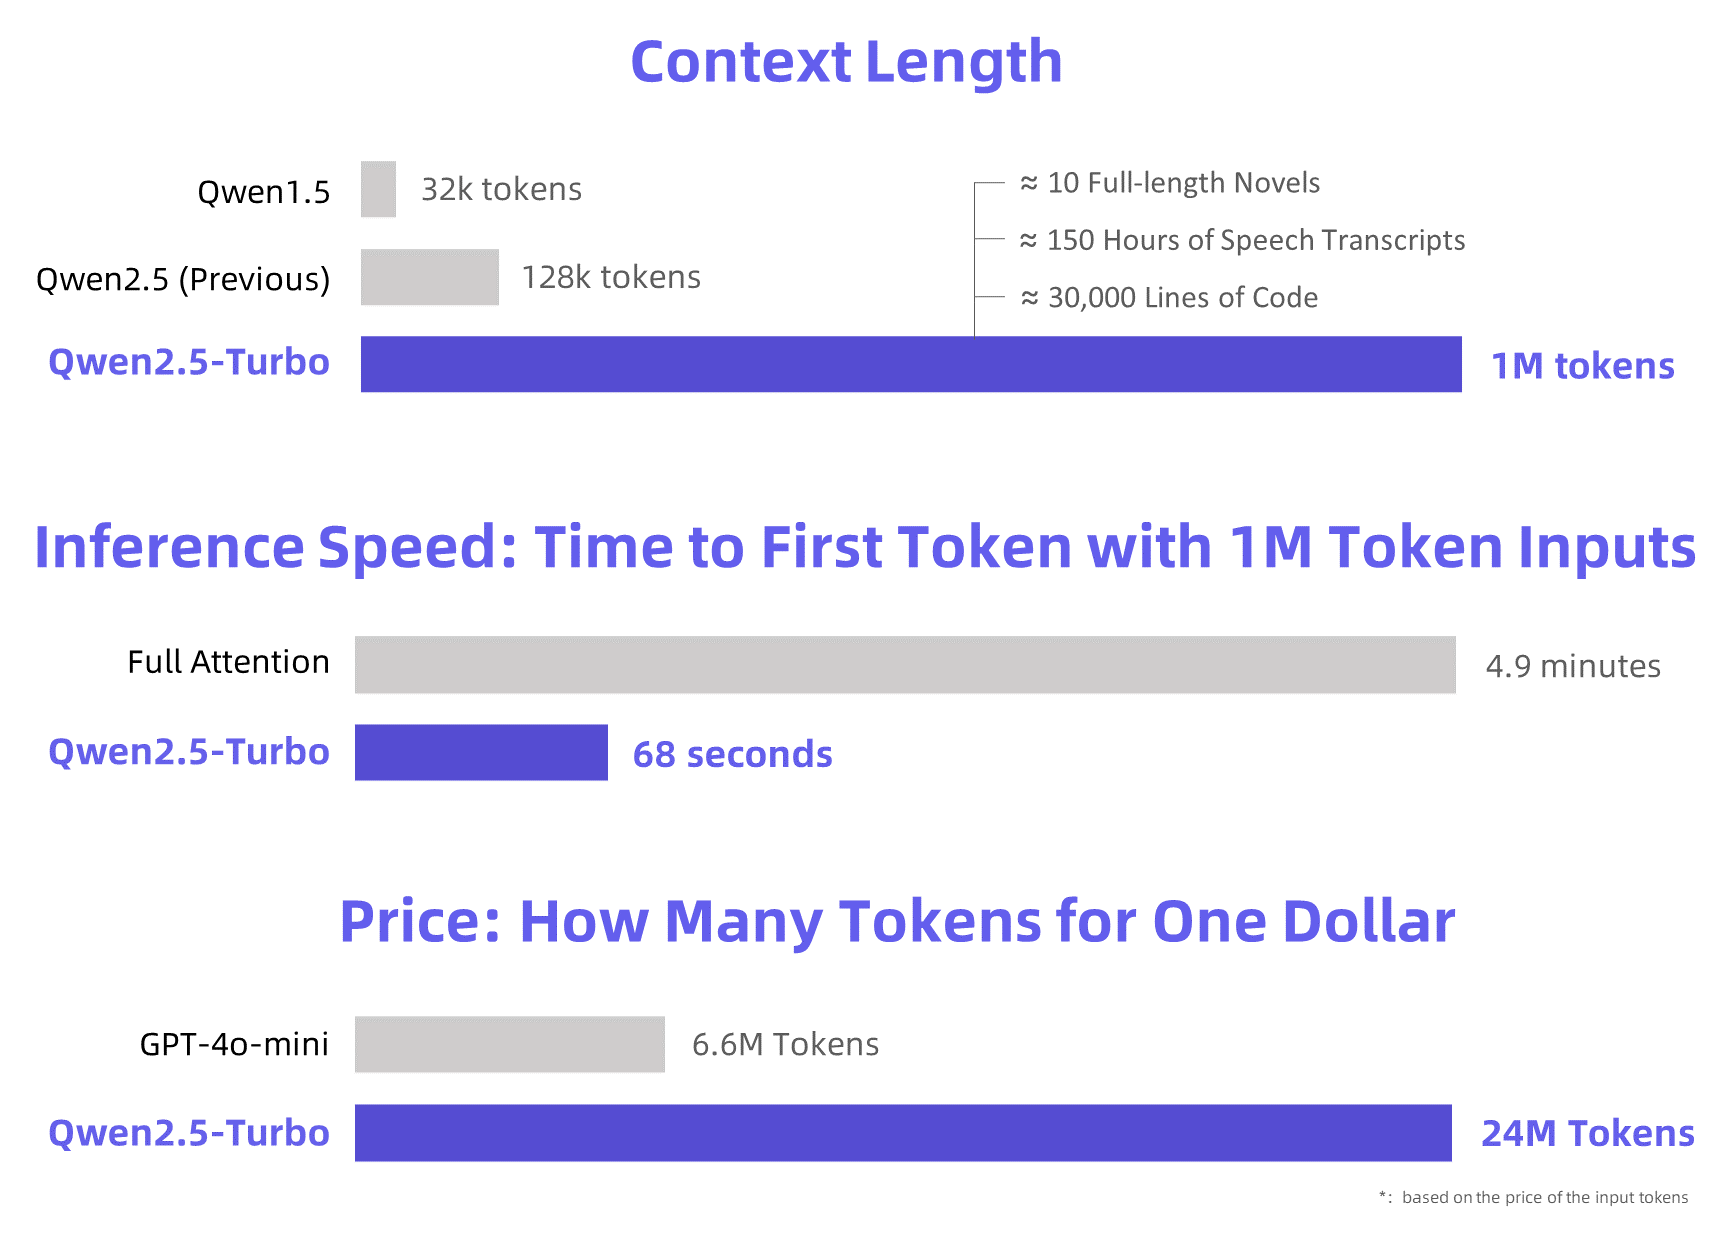
Qwen's Qwen2.5-1M release made million- available in downloadable 7B and 14B models, following the hosted Turbo expansion. The models were trained with sequences reaching 256,000 tokens, then extended to one million through a method that remaps positional distances beyond those encountered during training. The accompanying software accelerates the initial processing of long inputs. Qwen reports a 3.2–6.7-fold improvement in that phase across its tested configurations.
Self-hosting the maximum context remained demanding: the release guide specified at least 120 GB of combined GPU memory for the 7B model and 320 GB for the 14B model. Those requirements make context length a separate deployment consideration from the size of the model itself.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…