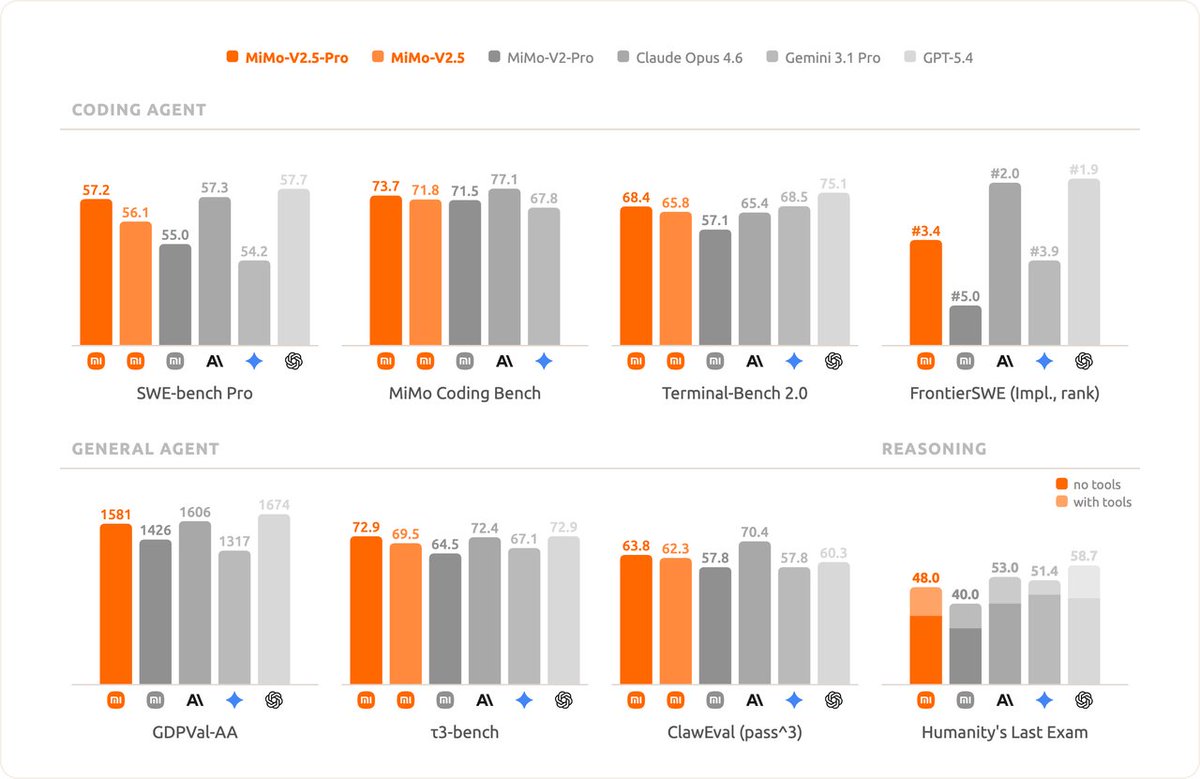
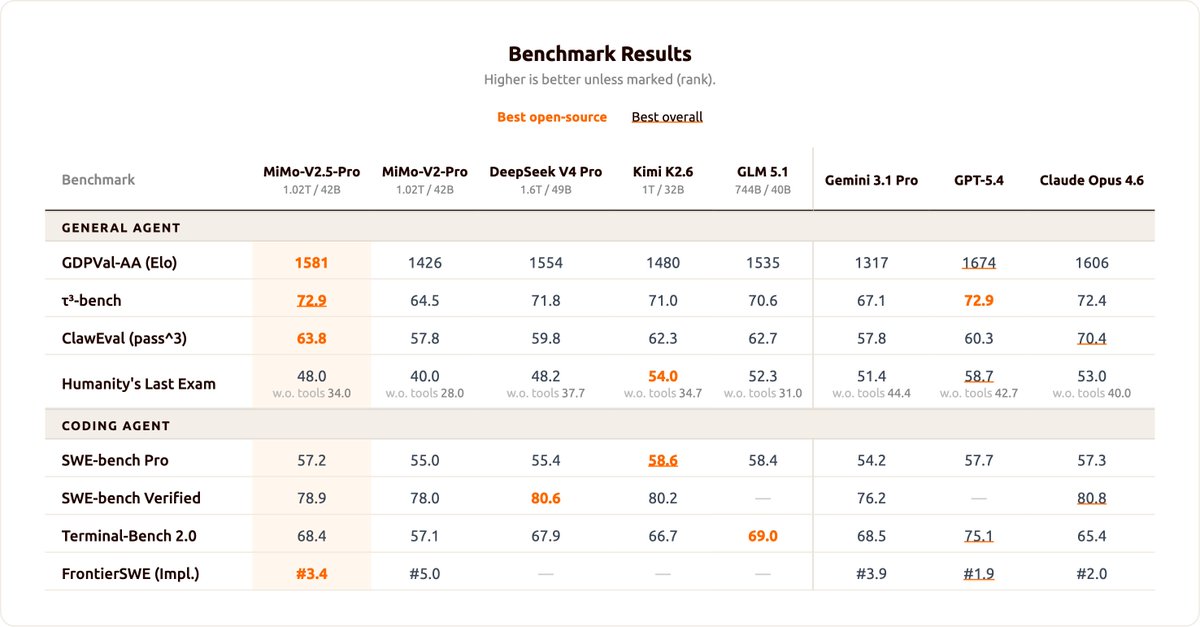
MiMo V2.6 Pro is a sparse mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → model with 1.02T total parameters but only 42B activated per token, aimed at complex software-engineering and long-running AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → work.
MiMo V2.6 Flash uses a much smaller MoE, 309B total parameters with 15B activated per token, positioned as the efficient tier for everyday multimodalA model that works with more than text — reading images, audio, or video, and sometimes generating them too.Full definition → automation rather than heavy coding work.
Beyond its 1M-token input context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, the MiMo V2.6 family supports up to 128K output tokens per response on AI Gateway.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Why it matters
MiMo V2.6's 1M-token context and three serving tiers, including a 20x-faster UltraSpeed option, give builders a concrete tradeoff between throughput and latency for long-running multimodal agent work.