KV-caching makes multi-reference FLUX editing twice as fast
- Source
- x.com
- Date

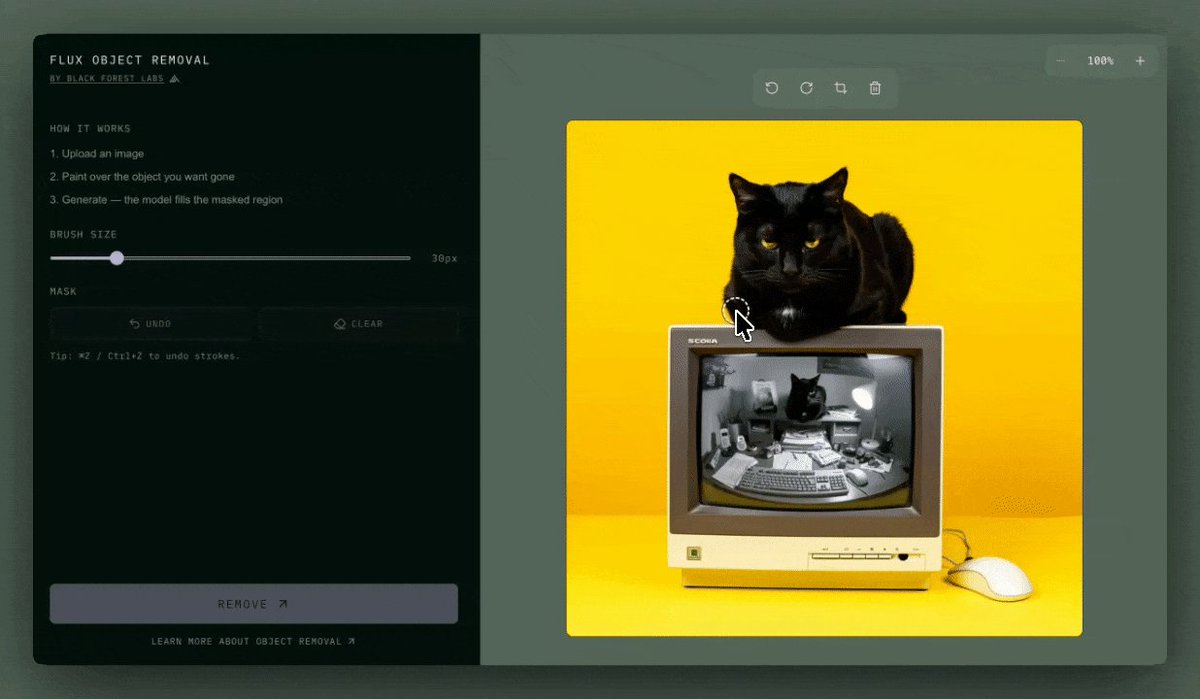
FLUX.2 [klein] 9B just got 2x faster at image editing, especially when you use multiple reference images. Same quality, no price increase.

Under the hood: KV-caching lets the model skip redundant computation on your reference images. The more references you use, the bigger the speedup. Inference is up to 2x+ faster for multi-reference editing.
We're also releasing FP8 quantized weights, built with @NVIDIA_AI_PC Run Klein 9B with less VRAM and faster inference for local and self-hosted deployments.
Already on FLUX.2 [klein] 9B via API? Free upgrade, faster, same price. On [klein] 4B and want better quality? 9B is now closer in speed. Docs → https://t.co/ZhlyBkTgG9 Weights → https://t.co/Aao6QYvTAt Try it → https://t.co/b7cnzrss3B
Context
Black Forest Labs says its FLUX.2 klein 9B editing update saves time by reusing computations for reference images. This technique, called , lets the model skip redundant work on the reference images it is given while creating an edited image. The announcement reports faster multi-reference editing, with larger benefits as more references are supplied. Building on the klein release, the change addresses a specific source of repeated work in editing, so the reported gain applies to that workload rather than establishing a typical speedup for every request.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
Checking sign-in…
Loading comments…