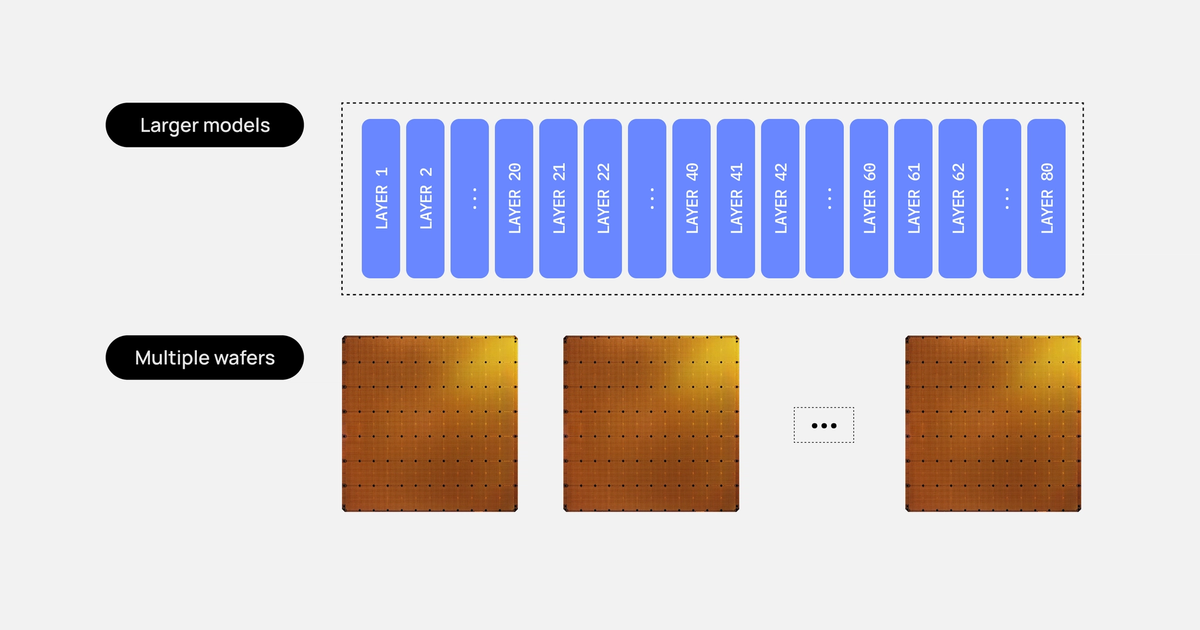
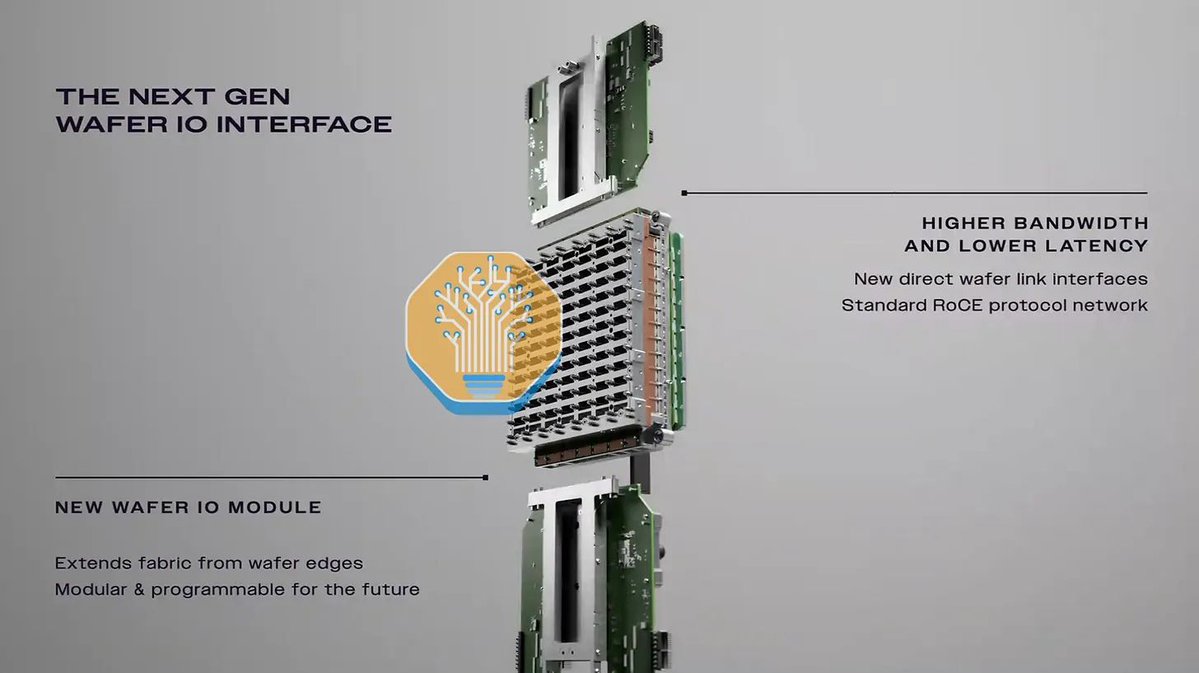
Shows how on-chip memory (44 GB per wafer) forces layer placement, and why linear attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → changes the wafer count for trillion-parameter inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition →. Helps explain where fast-inference capacity and cost come from.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.