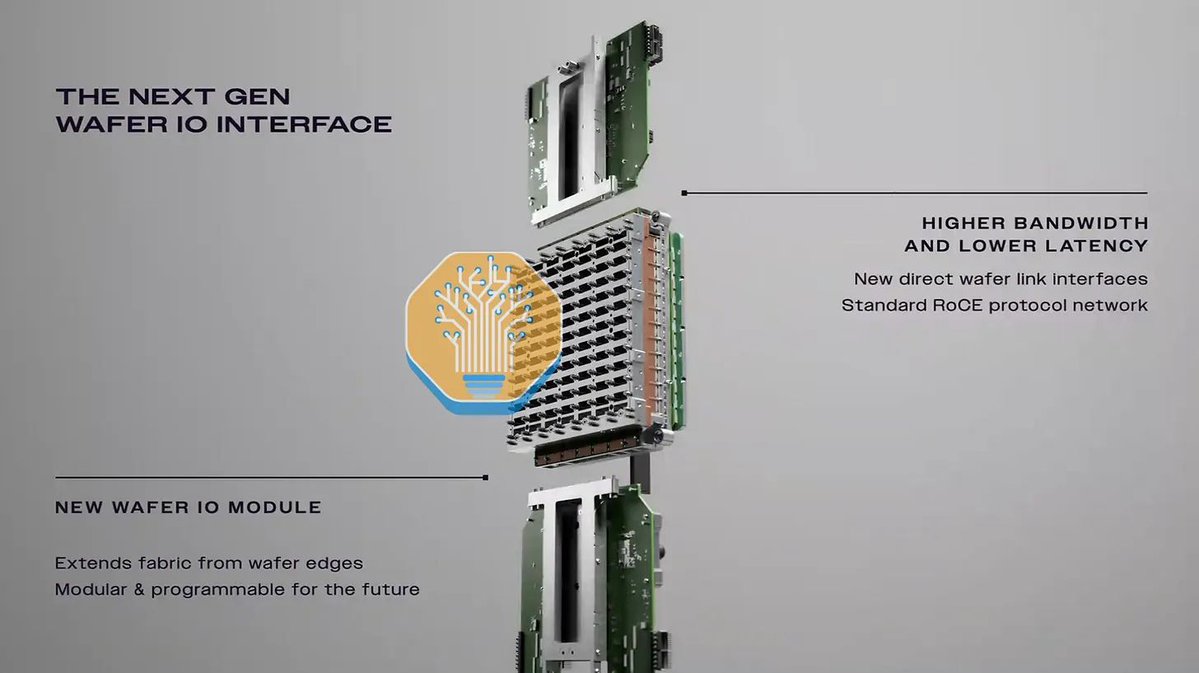
Wafer-scale chips keep weights in on-chip memory instead of streamingSending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.Full definition → them across a GPU cluster, which is why inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → latency can drop by an order of magnitude — a different cost and speed curve than GPU-based serving.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.