Qwen3.8-Max-0902 lands with 1M context and $2 input pricing
- Source
- x.com
- Date

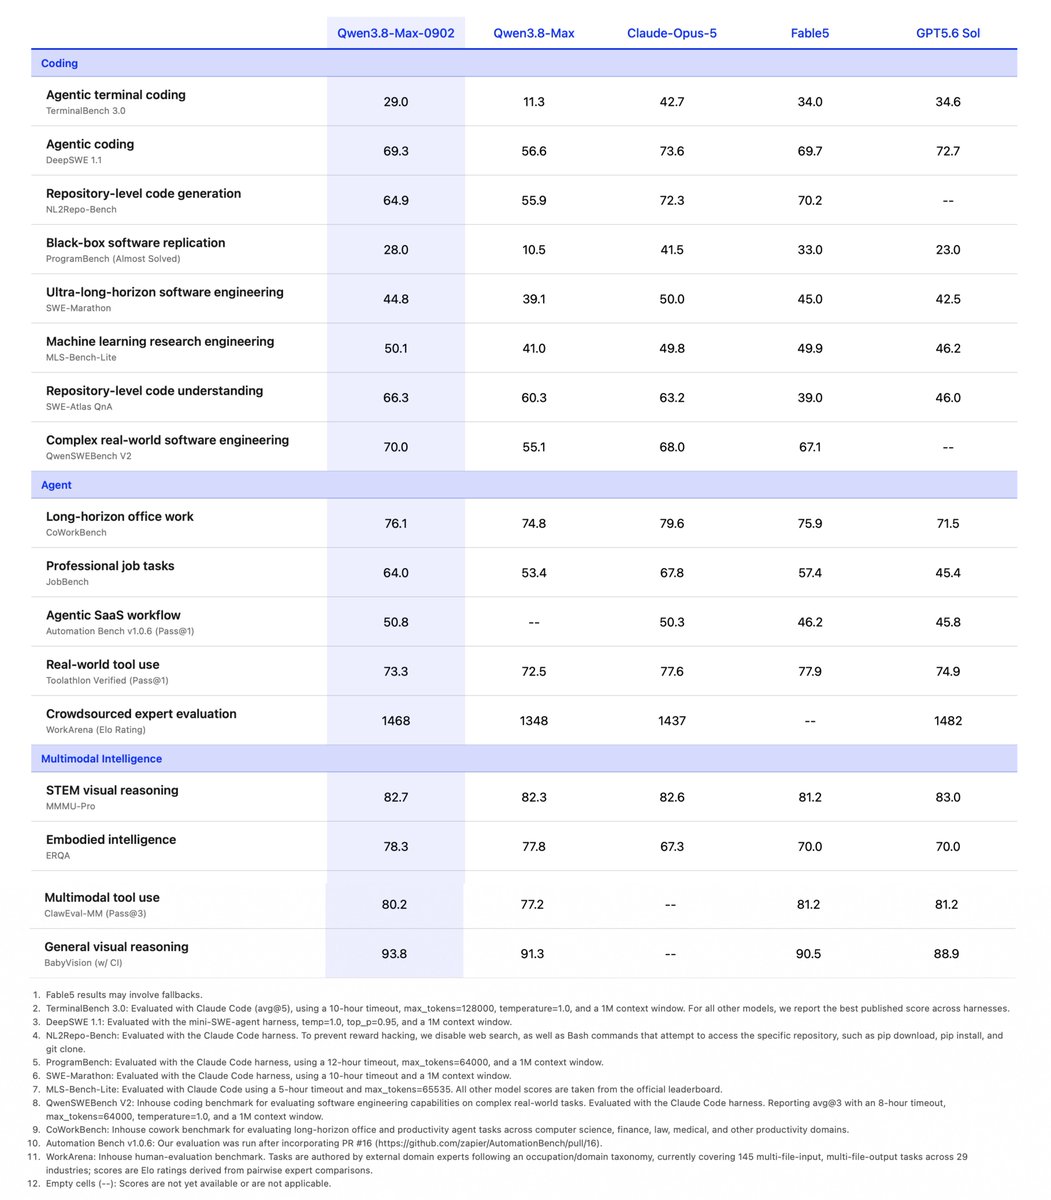
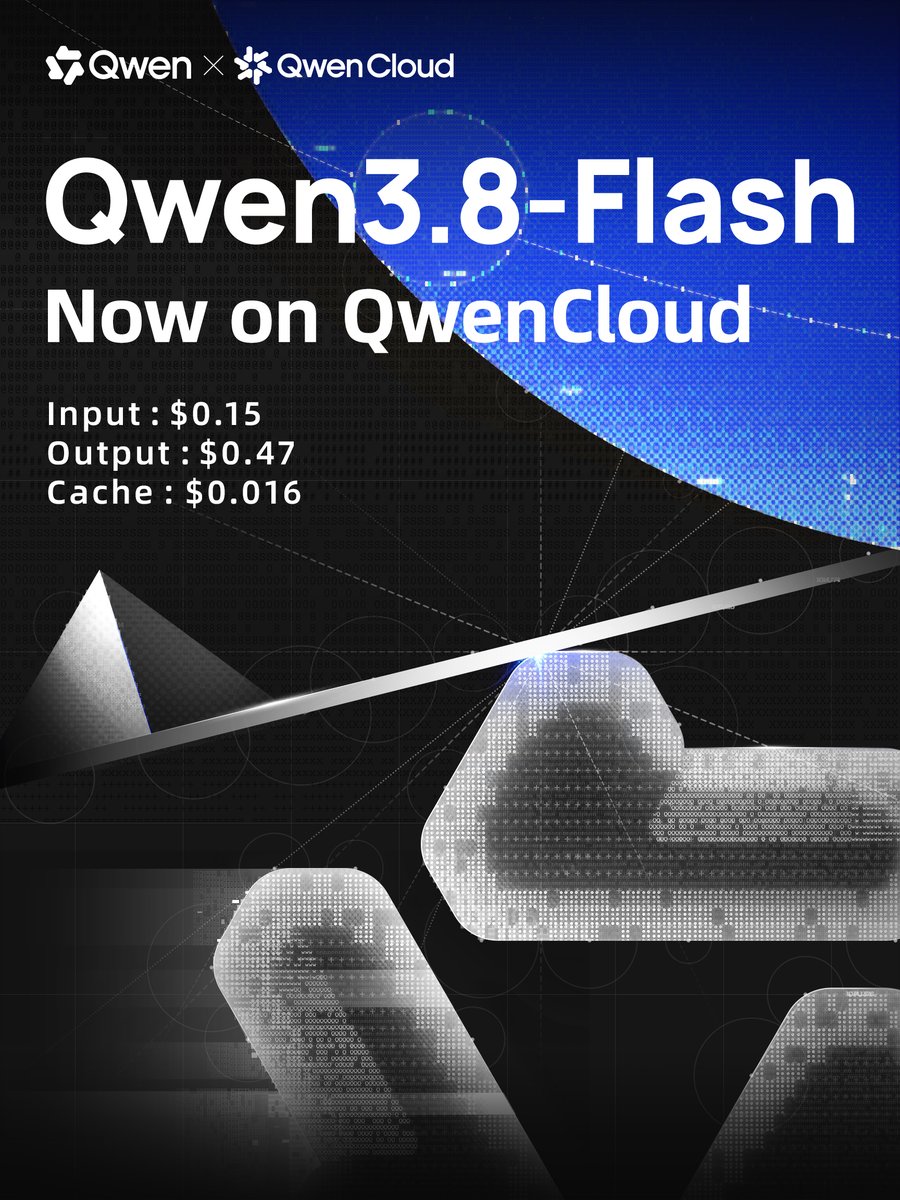
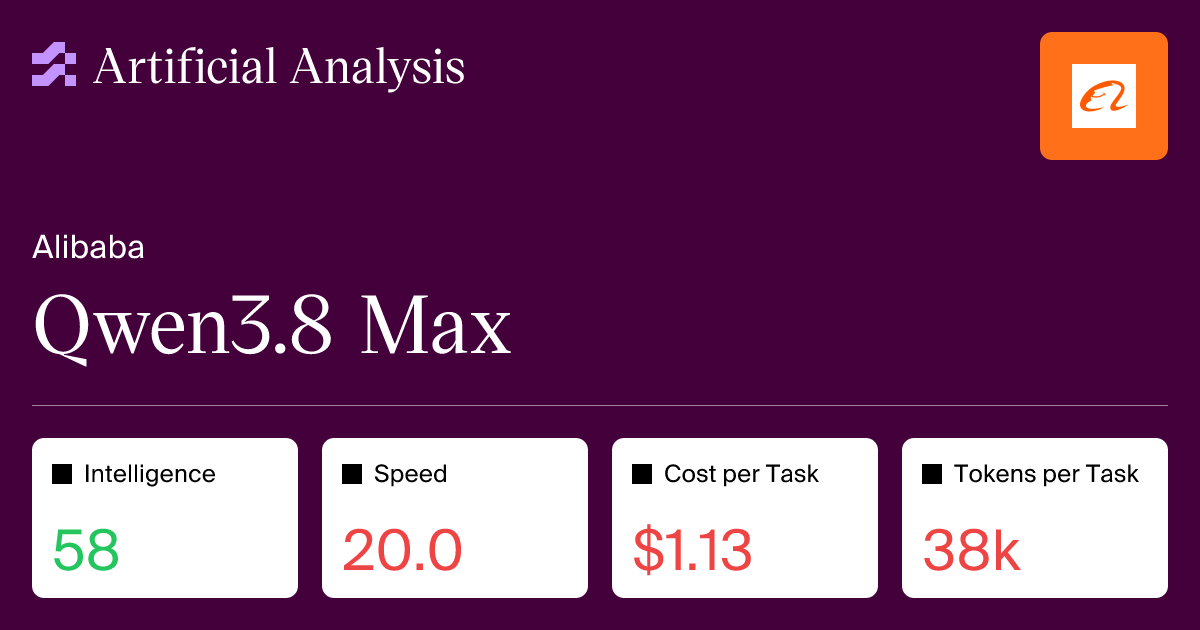
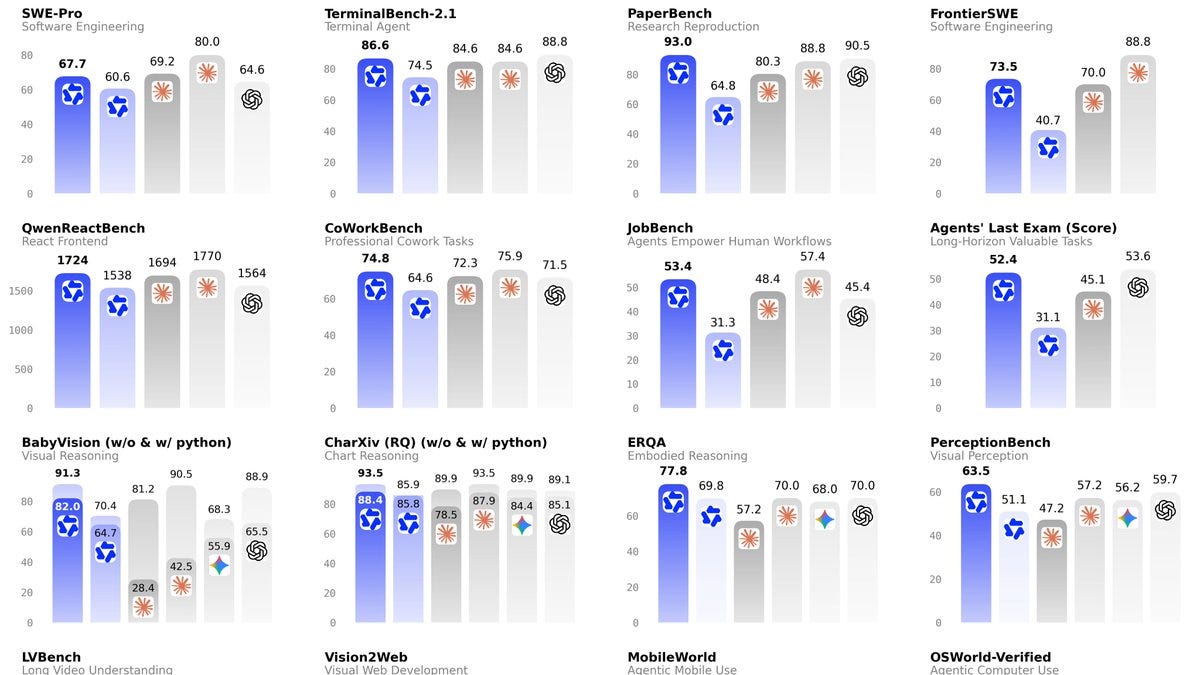
🚀Qwen3.8-Max just got upgraded. Meet Qwen3.8-Max-0902! 2.4T parameters. 1M context tokens. Built for real world complexity. Further post trained on Coding & Cowork, Qwen3.8-Max-0902 now delivers stronger performance across complex enterprise tasks, scientific research, and long horizon workflows. 💰Pricing per 1M tokens: $2 input, $6 output. $0.17 explicit cache hit, $0.25 implicit cache hit. Now live via API on QwenCloud. Come try it! 🙌 API:
Context
Qwen's Qwen3.8-Max-0902 has a one-million- and offers lower charges when requests reuse cached input. Its QwenCloud page lists $2 per million ordinary input tokens and $6 per million output tokens, with cache reads at $0.17 for explicitly created caches or $0.25 for automatic cache hits. Explicit cache creation has its own charge. The distinction matters for applications that repeatedly send shared material: the low read price applies to reusable cached content, rather than all input. Model pricing and cache description.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…