Qwen4 Max benchmarked: higher scores, lower cost per task
- Source
- x.com
- Date

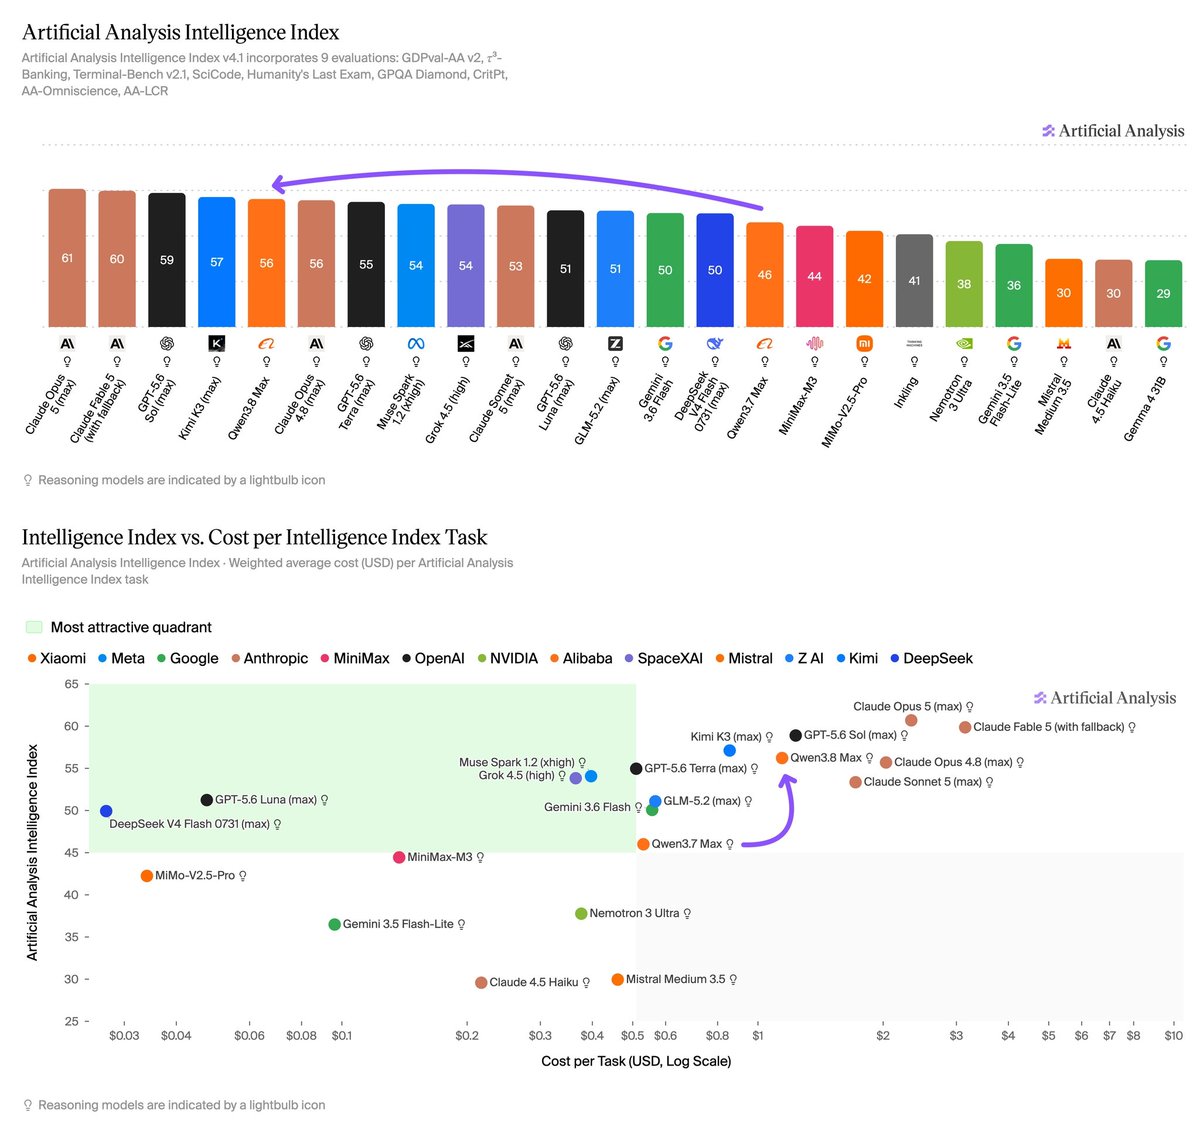
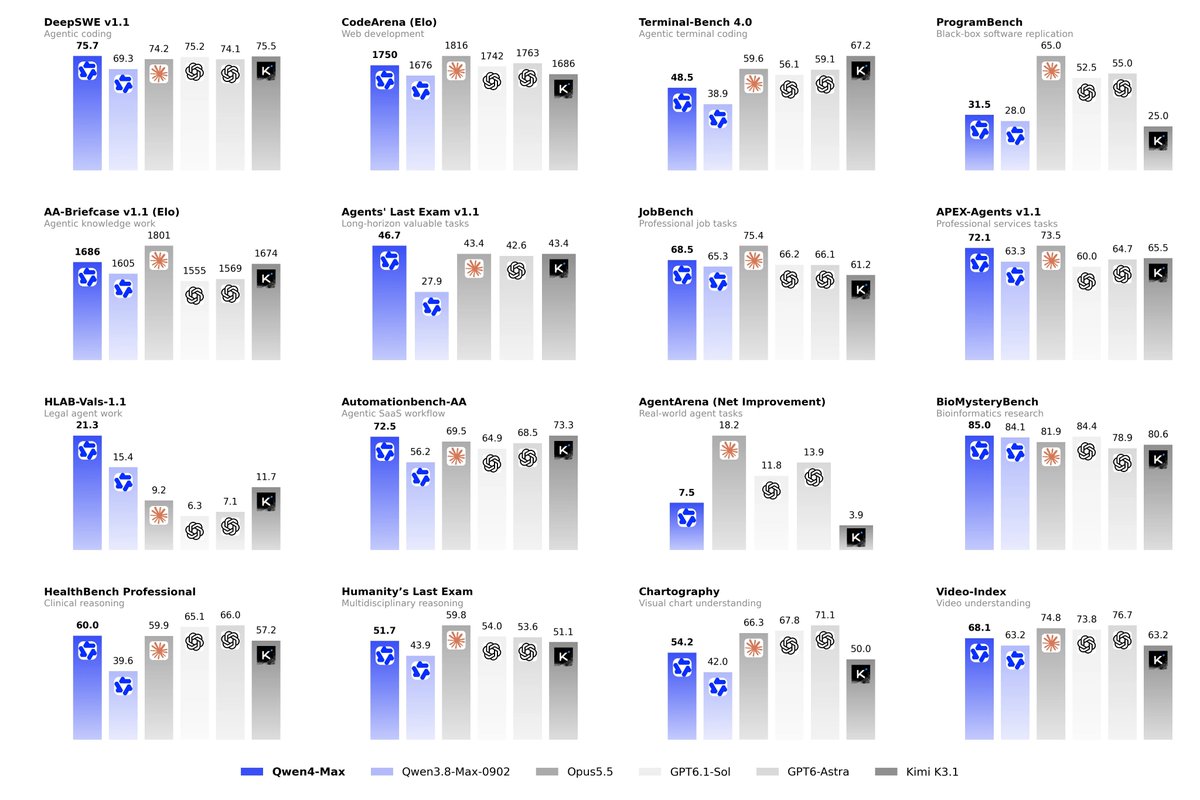
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46) Key takeaways: ➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo. ➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index. ➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1…

Context
Qwen4 Max, the new model from Qwen, Alibaba's model team, scores higher than its predecessor on Artificial Analysis's Intelligence Index while costing about a third as much to run through it. Artificial Analysis, a firm that benchmarks AI models, puts Qwen4 Max at 43 on the index, 9 points above Qwen3.8 Max, with both models run at xhigh reasoning effort, a setting that lets a model spend more computation working through a problem before it answers. The index combines nine evaluations that the firm runs itself, and Qwen4 Max improved on every one of them. The largest gain was on HLE-Diamond, where its score rose from 24% to 45%.
The cost figure is the firm's measured cost of having a model complete one Intelligence Index task, so it depends on prices and on how many tokens the model spends. Qwen4 Max comes to $3.27 per task, against $10.02 for Qwen3.8 Max. Artificial Analysis attributes the drop to per-token prices that are 25% lower, now $1.50 per million input tokens and $4.50 per million output tokens on Alibaba's own API; to cache hits that are 70% cheaper, at $0.075 per million tokens for input the service has already processed and stored; and to lower token use, about 105,000 output tokens per task against about 171,000, or 39% fewer. Alibaba's launch post had claimed, from its own internal , up to about 50% fewer tokens and an average cost per task more than 60% lower. The outside measurement of cost per task is consistent with that claim.
Against Kimi K3.1 Pro, the comparison the firm leads with, the result is closer. Kimi K3.1 Pro from Moonshot AI, run at its max setting, scores 46 and costs $3.68 per task, so Qwen4 Max is about 11% cheaper for a score 3 points lower. Kimi also uses fewer output tokens, about 72,000 per task, and leads clearly on Terminal-Bench 4.0, 67% to 48%. On FrontierCode 2.0, which the firm describes as Cognition's private evaluation of real-world coding tasks, the two tie at 26%, behind Tencent Hy4 at 31%. Qwen4 Max comes out ahead on AA-Briefcase, the firm's test of agentic work across real business files, with an Elo rating of 1686 against 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4. Tencent Hy4 is the low-cost option in this comparison: about $1.03 per task, roughly a third of Qwen4 Max's cost, for a score 8 points lower.
These are Artificial Analysis's measurements on its own index, and its chart places Qwen4 Max well below the top of the field, where Claude Fable 5.2 at max effort scores 65. What the results support is a large step in price and efficiency within Alibaba's lineup: for someone paying for Alibaba's API, Qwen4 Max does better than Qwen3.8 Max on every test in the index for about a third of the cost per task. Against Kimi K3.1 Pro, it is a near match on score and price, with a clear gap on terminal tasks.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.

Checking sign-in…
Loading comments…