Tencent's Simple attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → Sparsification release teaches a model which portions of earlier text to consult during generation. Its learned router ranks blocks of stored attention information and selects a limited subset. Adjustable gates let training improve those choices using the model's text-prediction objective, according to the model card.
The downloadable files contain the routers, while the underlying Qwen3 models remain separate. The release requires the matching base model and the project's modified serving software. Its contribution is a trainable way to restrict attention work while retaining useful context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, rather than a new standalone LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition →.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
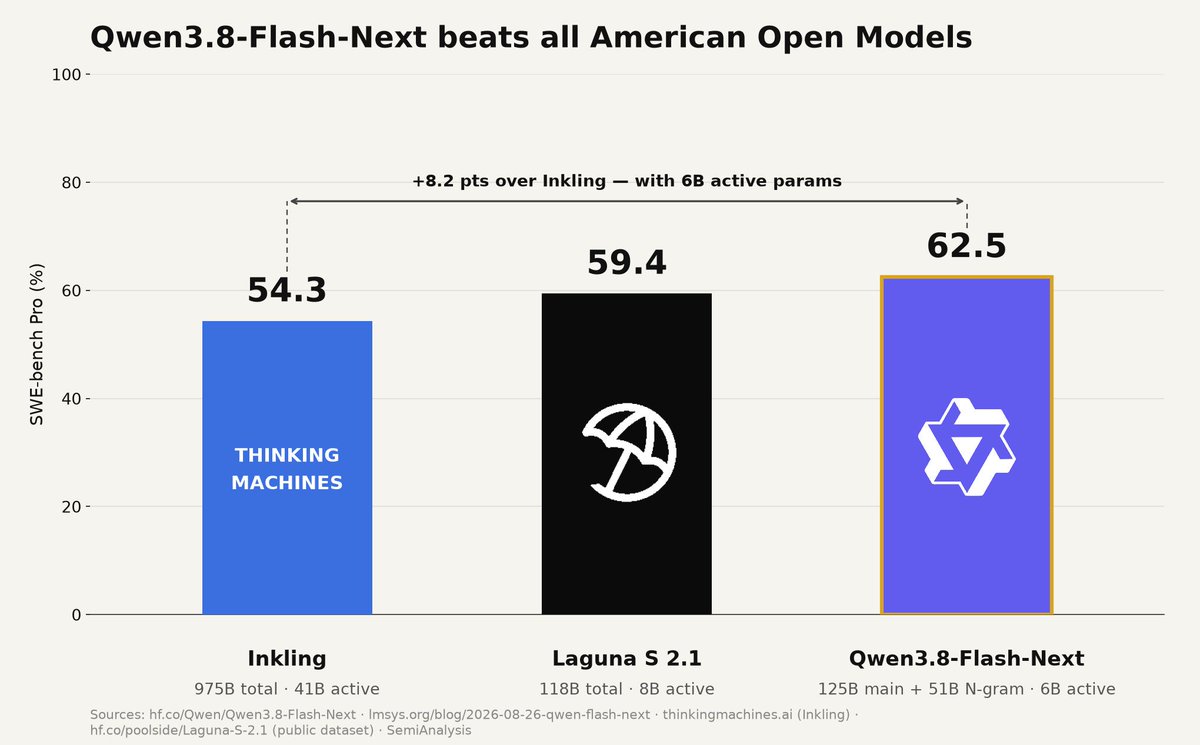 postInside Qwen3.8-Flash-Next: n-gram embeddings, gated residuals, sparse attentionSemiAnalysis
 articleRBS-Attention: Radius-Bounded Sparse Prefill for Long-Context Large Language ModelsChuxu Song, Jiuqi Wei, Zhencan Peng
 articleExperiment with Qwen3.8-Flash-Next 176B Model on NVIDIA GB300 NVL72 for Agentic CodingMichelle Horton