Gemini 3.6 Flash Debugging Benchmark: It Can Fix Real Bugs, but Is It Efficient?
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
A small code patch can require a large amount of AI investigation. AlphaSignal reports that Gemini 3.6 Flash resolved 60 of 65 attempts in its private debugging benchmark, which repeated thirteen tasks five times each. Yet the model averaged 391,879 of total traffic per attempt despite producing patches averaging only 4.3 added lines.
The had to locate faults from symptom descriptions, inspect an unfamiliar application and test its changes. Those steps explain why patch size alone says little about the resources needed to produce it. The reported success rate belongs to this application and task set; the useful finding is that investigation cost and final edit size can differ sharply.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
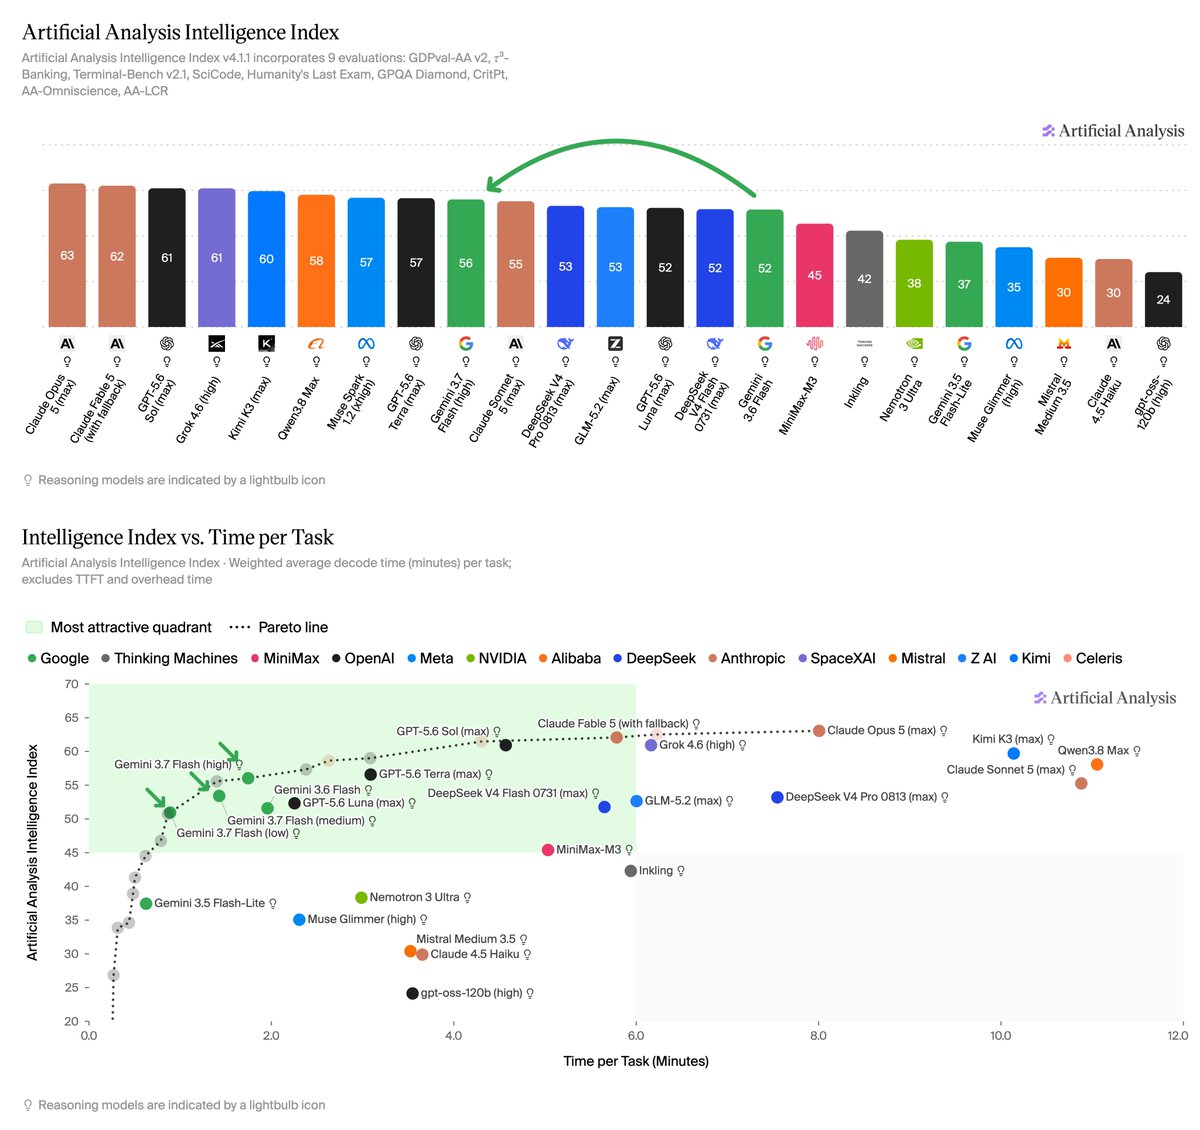
“Gemini 3.6 Flash achieved a 92.3% resolve rate (60/65 attempts) on a private 13-task debugging benchmark across a real full-stack codebase, but ranked seventh out of nine models, behind Grok 4.5, GPT-5.6 Sol, Fable 5, GLM-5.2, Opus 4.8, and Gemini 3.1 Pro Preview.”
AlphaSignalAI
“Despite producing small, focused patches (averaging 4.3 added lines and one changed file), Gemini 3.6 Flash consumed the highest total token traffic of any model tested, averaging 391,879 tokens and 16.8 agent turns per attempt, undermining Google's efficiency claims in a real-world agentic context.”
AlphaSignalAI
“Its worst failure mode occurred on a performance regression task where the model correctly diagnosed a quadratic complexity problem and reported implementing a fix, but after 40 agent turns the repository contained no changed files — visible tests passed, hidden performance tests failed.”
AlphaSignalAI
“A model can carry a low API price and still become expensive if it needs a large amount of context or takes a long path to the answer.”
AlphaSignalAI
“It works inside a fresh Docker sandbox with no internet connection, so the model cannot search for the repository, copy an answer from an issue tracker, or pull in external documentation while solving the task.”
AlphaSignalAI
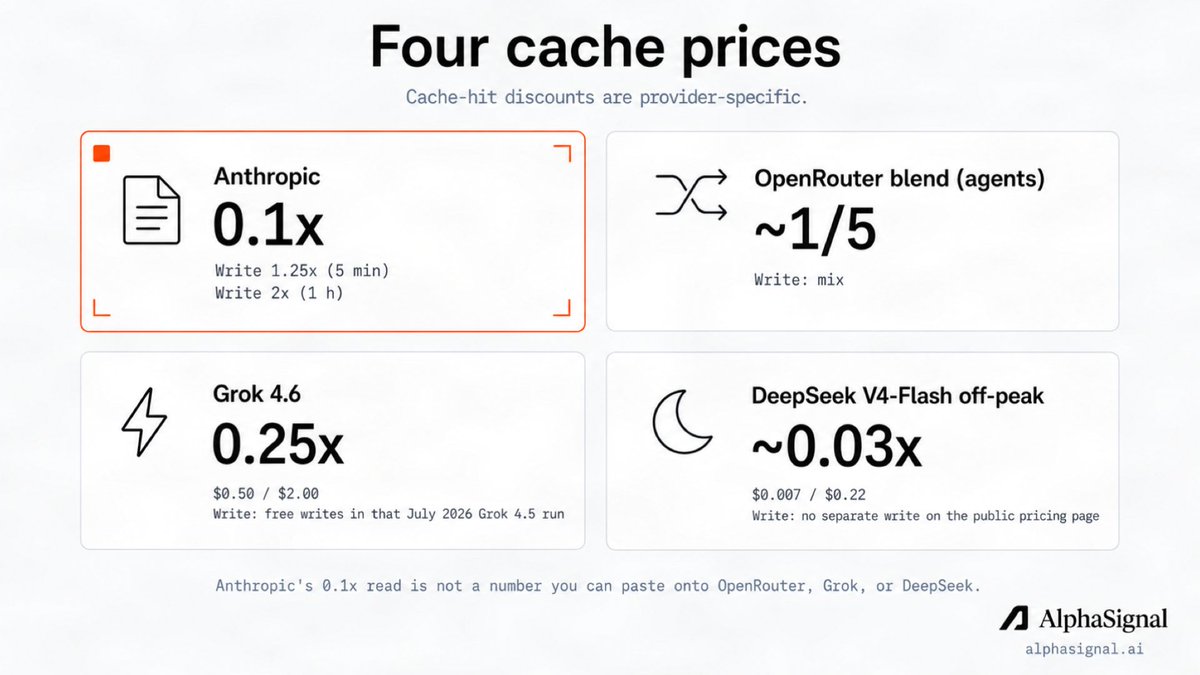 postPrompt cache TTL is a hidden cost in long agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to
Checking sign-in…
Loading comments…