Google has released Gemini 3.7 Flash, improving 4 points over Gemini 3.6 Flash a
- Source
- x.com
- Date

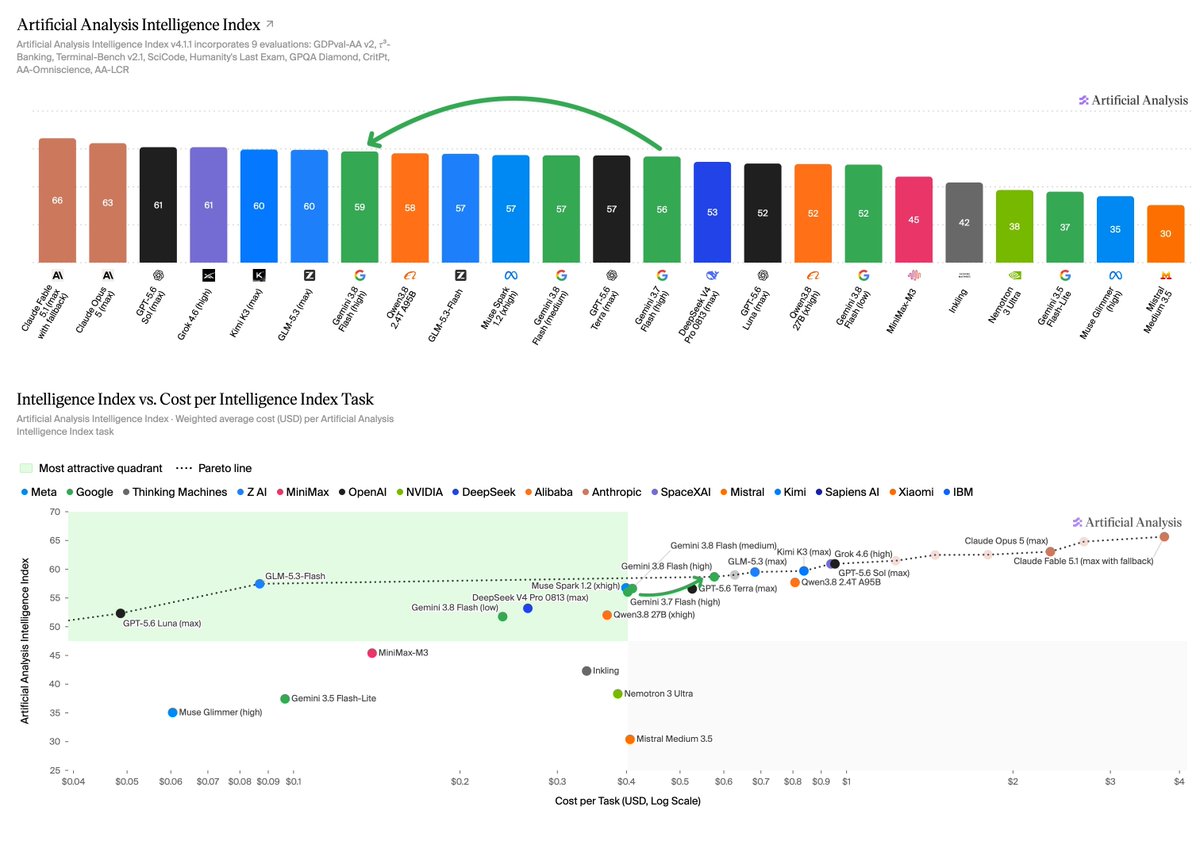
Google has released Gemini 3.7 Flash, improving 4 points over Gemini 3.6 Flash and reaching the Intelligence vs. Time per Task Pareto frontier @GoogleDeepMind has released its third new Gemini Flash model in three months. Gemini 3.7 Flash (high) scores 56 on the Artificial Analysis Intelligence Index, just behind GPT-5.6 Terra (max, 57) and Muse Spark 1.2 (xhigh, 57) We benchmarked Gemini 3.7 Flash across all three reasoning levels (high, medium, low) ahead of release. With high reasoning, Gemini 3.7 Flash is a 4 point improvement over 3.6 Flash, while achieving an average Time per Task of 1.7, 40% faster than GPT-5.6 Terra (max). This places Gemini 3.7 Flash on the Intelligence vs. Time per Task Pareto frontier, reinforcing Google’s focus on speed across the Gemini Flash family of models Key benchmarking results across Gemini 3.7 Flash’s three reasoning levels: ➤ 4 point Intelligence Index improvement: Gemini 3.7 Flash (high) scores 56 on the Artificial Analysis Intelligence Index, up 4 points from Gemini 3.6 Flash. The improvement is driven primarily by gains on agentic evaluations, including Tau3 Banking (+3 points), Terminal-Bench v2.1 (+8 points), and GDPval-AA v2 (+103…

Context
Artificial Analysis, which benchmarked the model ahead of release, found that Google DeepMind's Gemini 3.7 Flash gains most on tasks and runs much faster than the models that score near it. In its evaluation thread, the high reasoning setting scored 56 on the Artificial Analysis Intelligence Index, the firm's headline score, up 4 points from Gemini 3.6 Flash and one point behind GPT-5.6 Terra and Muse Spark 1.2 at 57. The firm attributes most of the gain to agentic evaluations, tests in which the model acts on tasks instead of only answering: Terminal-Bench v2.1 rose 8 points and Tau3 Banking rose 3. It is Google's third new Flash model in three months, following the Gemini 3.6 Flash announcement.
Speed is where the model stands out. It produced about 340 output per second, nearly three times the output speed of GPT-5.6 Terra and GLM-5.2, and at high reasoning it averaged 1.7 minutes per Intelligence Index task, which the firm says is 40% faster than GPT-5.6 Terra at its max setting. That places it on the firm's Pareto frontier for intelligence against time per task: among the models measured, none scores higher while also finishing tasks faster.
The cost advantage rests on a temporary price cut. Standard pricing is unchanged from Gemini 3.6 Flash at $1.50 per million input tokens and $7.50 per million output tokens, but Google is charging half that, $0.75 and $3.75, through the end of the year. At the discounted rate, the high setting cost $0.40 per Intelligence Index task, 30% less than Gemini 3.6 Flash, while the medium setting scored 53 at $0.26 per task. Artificial Analysis gives no per-task cost at standard pricing, so the 30% saving describes the discount period only.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…