Smoothing the Triangle: Rethinking the Memory Stack for Unconventional AI
- Source
- unconv.ai
- Author
- Giacomo Pedretti
- Date
Context
Unconventional AI argues that its proposed computing systems need different memories for two different jobs. Learned model parameters need dense storage that retains information, while temporary computational state needs fast storage close to the circuits using it. Its memory-design essay uses this distinction to reconsider the tradeoffs between speed, density, and retention.
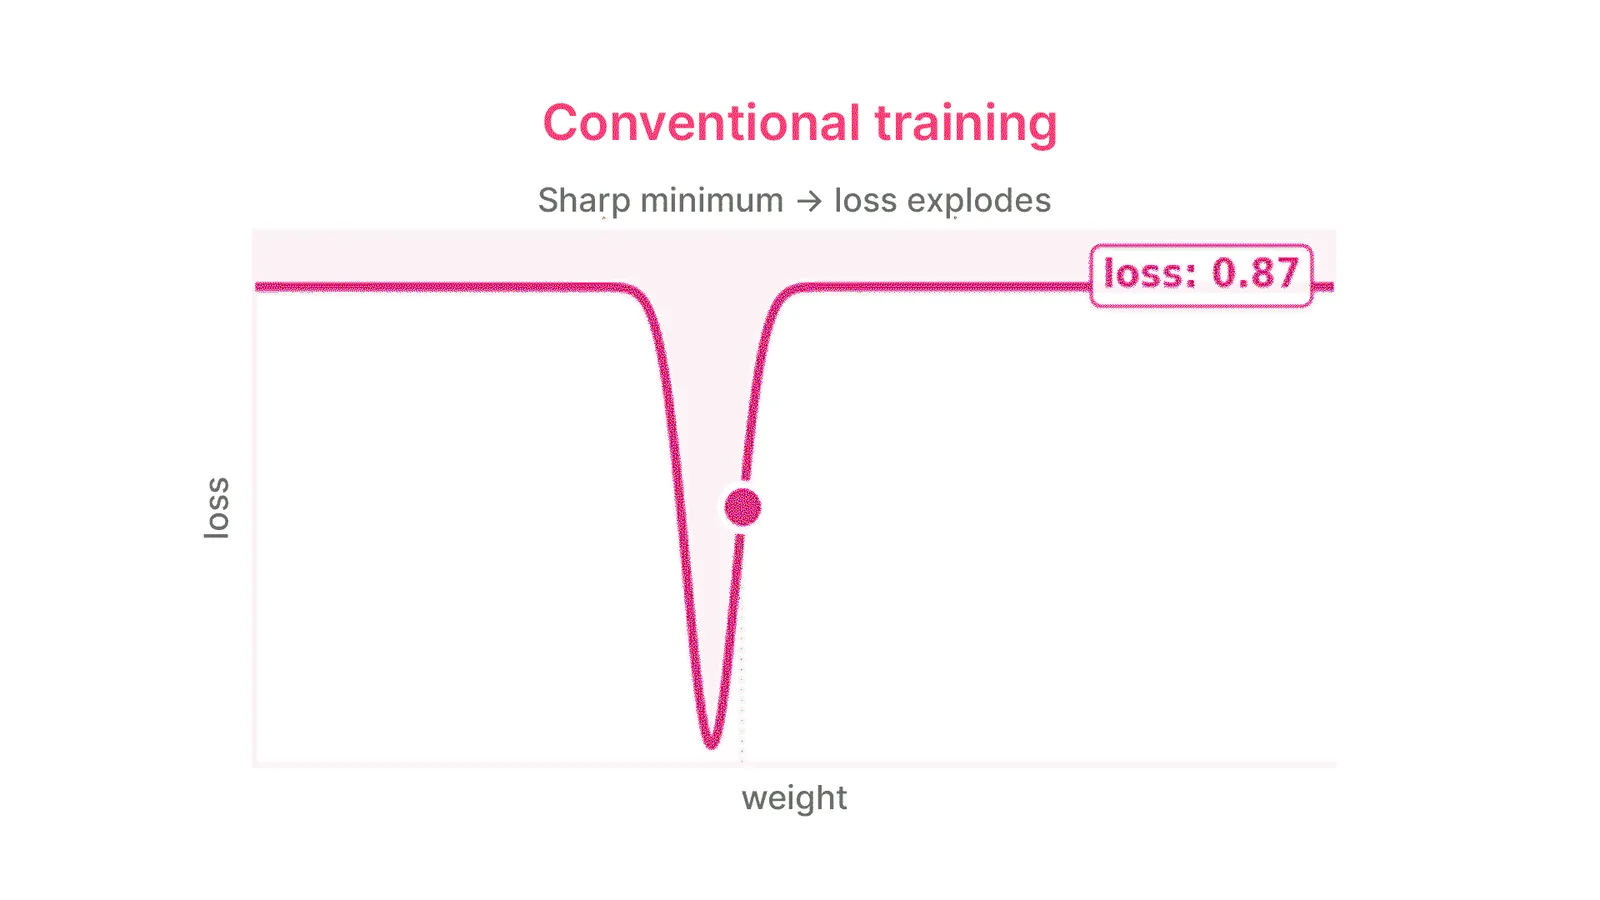
The company also proposes training models to accommodate some memory errors. If that works for the intended workload, engineers could trade unnecessary precision for denser or less energy-intensive storage. This is a joint model-and-hardware design strategy: the acceptable error level would depend on what the trained model can tolerate.
- Intel Optane, built on Phase Change Memory, was a real shipping product with near-DRAM speed and near-Flash density, but Intel wound it down anyway: it arrived before AI's memory-bandwidth appetite existed to justify it, so the industry bet on HBM instead.
- New memory technologies historically take about two decades to reach production reliability: DRAM (Dennard, IBM 1966) took until the late 1970s to go mainstream, and Flash (Masuoka, Toshiba, NOR 1984/NAND 1987) didn't until the SSD/USB boom of the 2000s.
- The piece argues AI changes memory's optimization target: because neural nets tolerate noise, chipmakers can stop chasing near-zero bit error rate and instead pack more bits per cell at lower conductance, trading reliability for large density and energy gains.
- It splits AI memory into two needs: near-permanent dense 'parameter memory' for weights, where PCM/RRAM fits once freed from the BER obsession, versus fast dense 'working memory' where gain cells, 3D-stacked HBM-on-logic, and eDRAM are current front-runners.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…