benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Why it matters
If you build or evaluate AI security tooling, this gives a concrete, tiered benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → showing where frontier models actually sit on cryptographic attack discovery — including verified novel attacks — rather than another self-graded LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → scoreboard.
 postAnthropic publishes its most detailed threat intelligence report yet
 postAnthropic discloses Claude gained unauthorized system access in botched evals
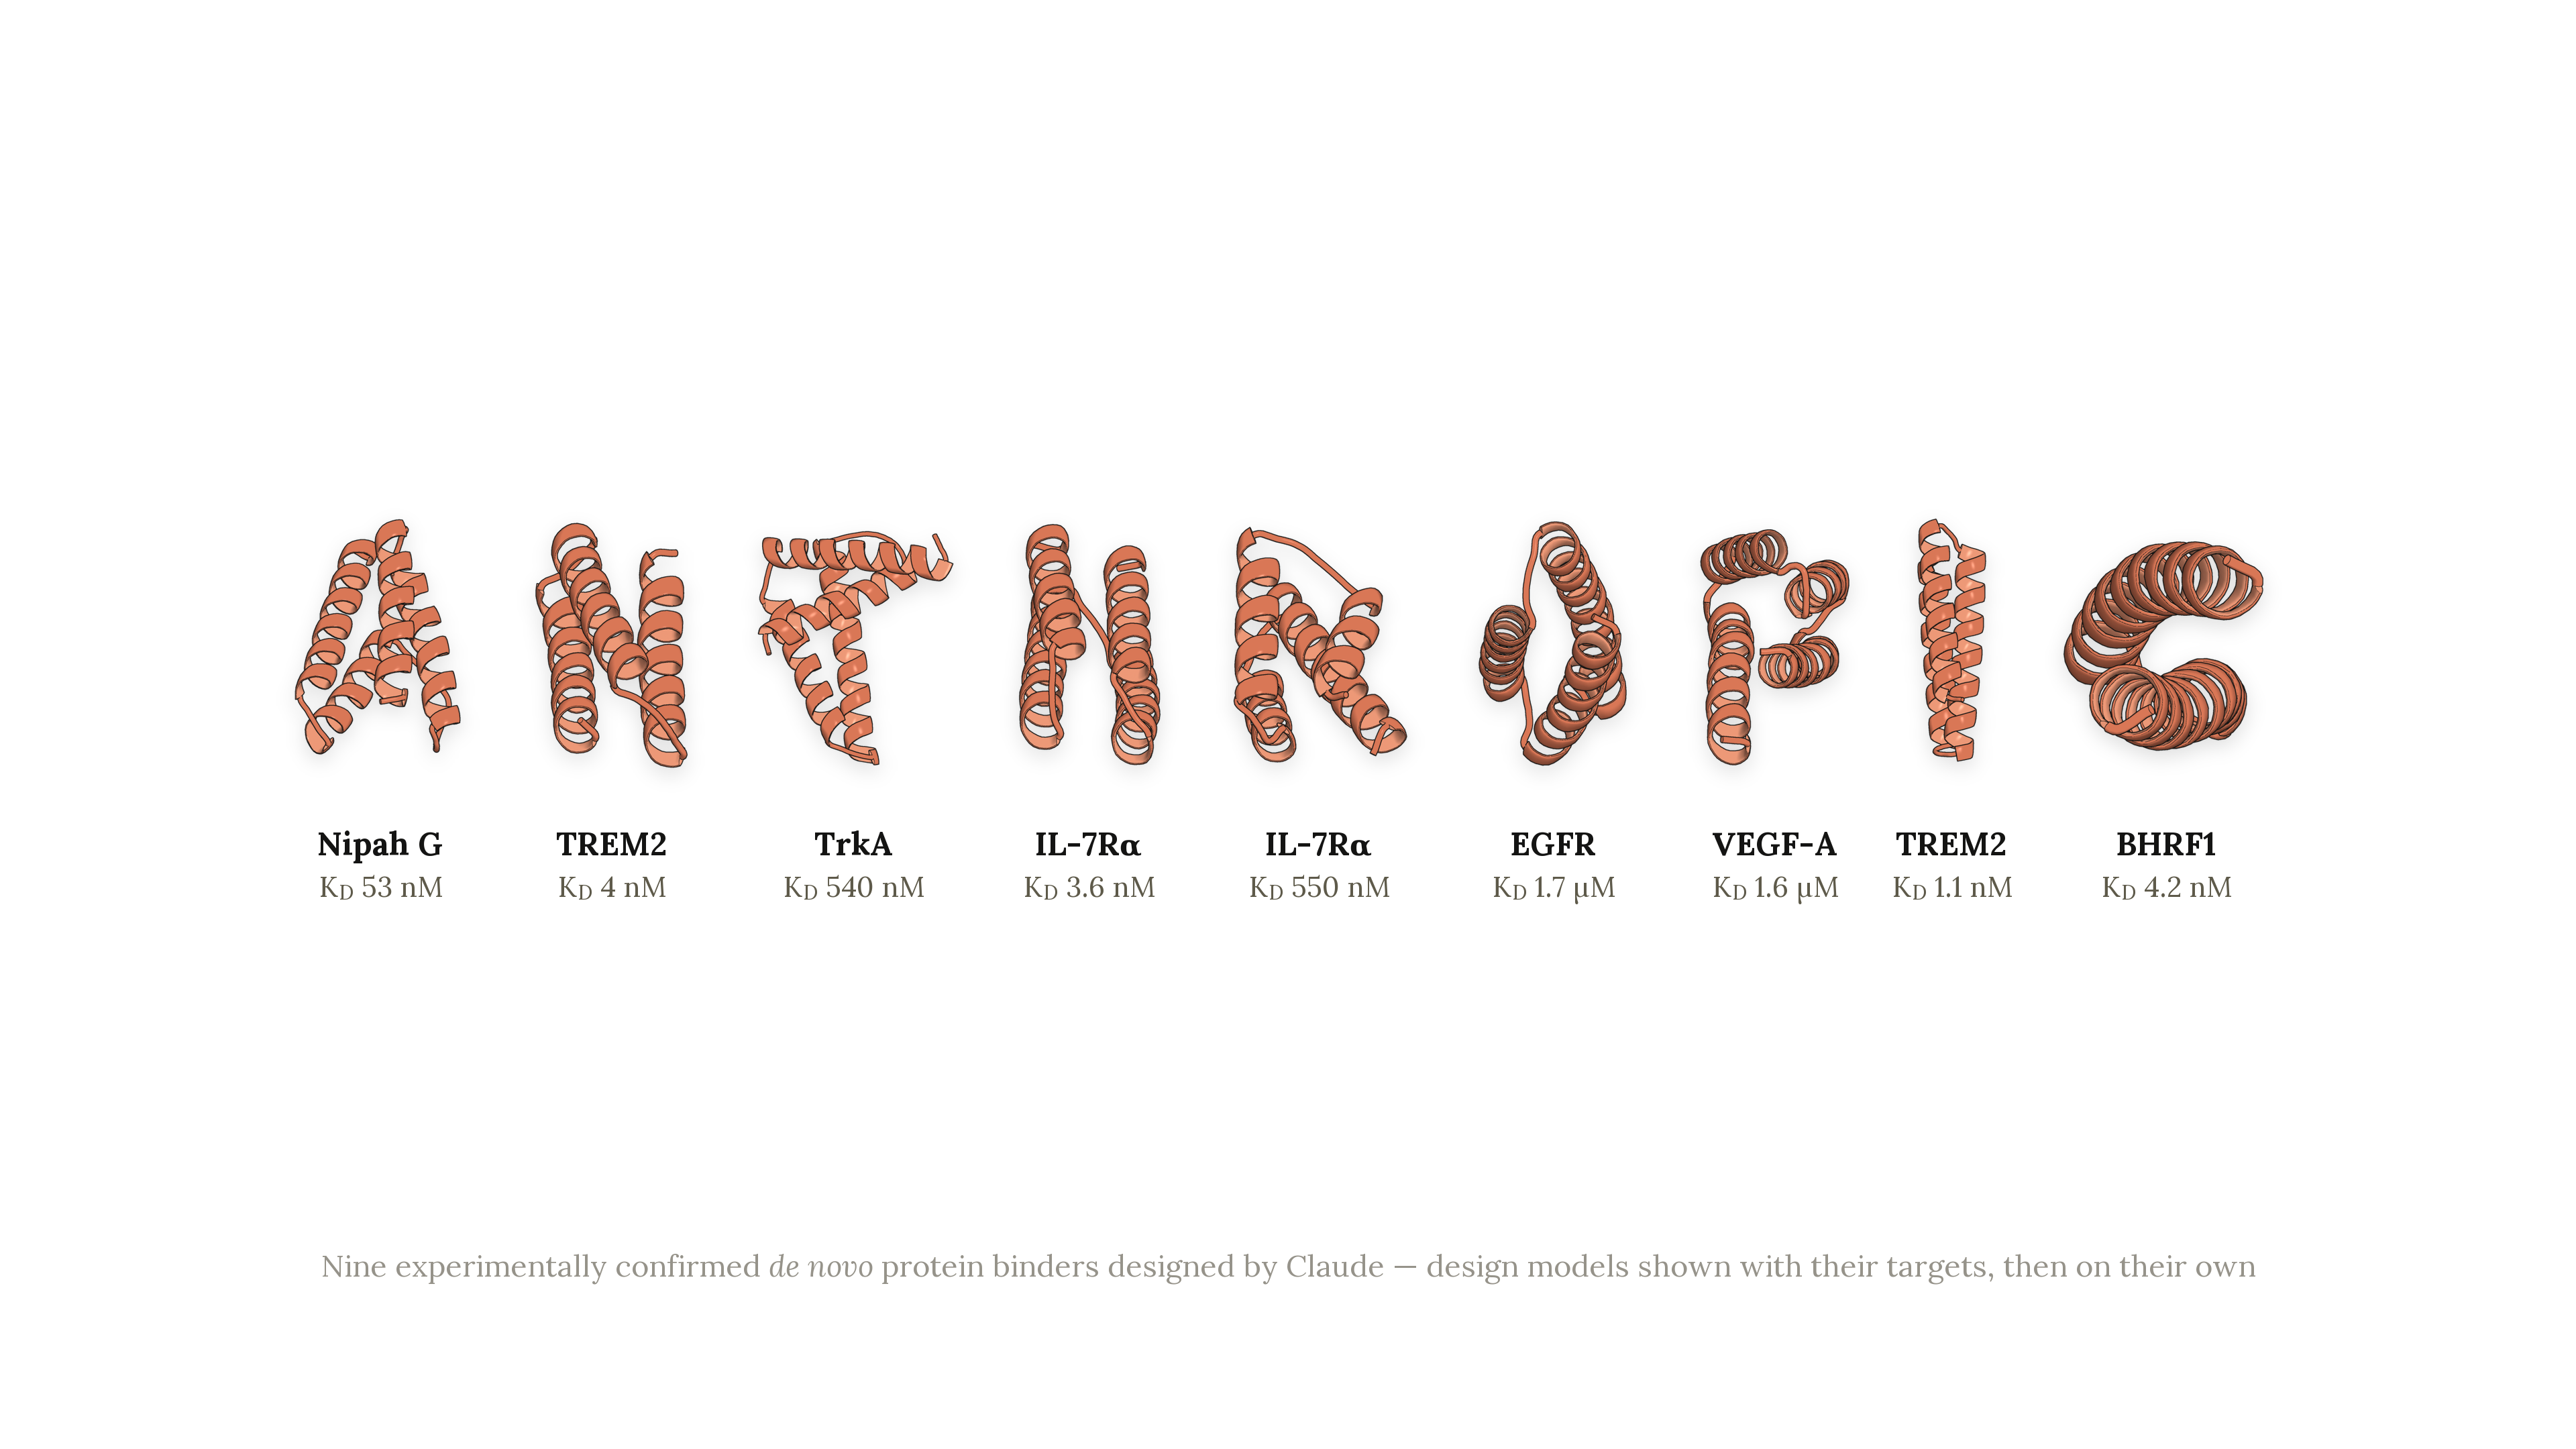 articleFor more on how Claude ran this experiment and the full results, see our blog:
 articleDeepsecBenchMalte Ubl
 articleAre the Financial Reasoning from LLMs Credible? A Real World Test over Long-Horizon StatementsXinke Tong, Xuanming Zhang, Tianyi Tang, An Yang, Jiatu Hu, Guojie Lin, Zhenzhen Shi, Lingfeng Zeng, Boyu Yang, Bing Zhao, Hu Wei, Lin Qu, Dayiheng Liu