NVIDIA's Axolotl3D Reconstructs Occluded 3D Geometry From Images
- Source
- x.com
- Date

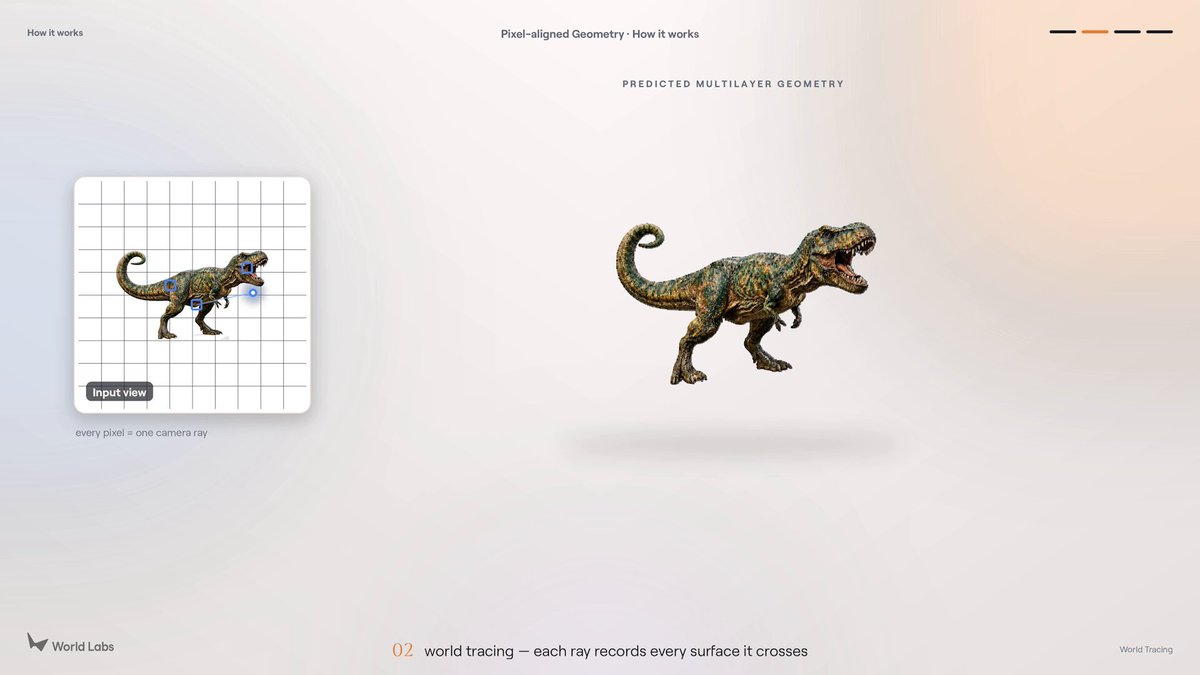
Images rarely show an object’s full 3D geometry. At #ECCV2026, our research team introduced Axolotl3D, a multimodal and occlusion-aware 3D generation model. It combines images, camera data and partial geometry to reconstruct missing regions while preserving observed ones, achieving state-of-the-art results across single- and multi-view settings. Project page:

Context
A photo or video usually shows only part of an object's true 3D shape, since occluded surfaces and backsides go unseen. NVIDIA's Axolotl3D, presented at ECCV 2026, is a 3D reconstruction model built to fill in those missing regions rather than only work with what is visible. It combines an image, camera parameters, and a partial point cloud, using the point cloud as a geometric anchor so the completed shape stays faithful to what was actually observed instead of drifting into a generic guess.
The accompanying paper reports that Axolotl3D outperforms prior methods on geometric accuracy and reconstruction fidelity, tested on the Toys4K and OmniObject3D object datasets under single- and multi-view conditions, with and without synthetic occlusions added to the input. Those results come from NVIDIA's own paper rather than an independent , and the announcement itself provides only a demonstration video rather than tables, so the comparison should be read as the authors' reported finding, not third-party confirmation.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…