I trained a 160M code model on one GPU and got 22.56% on HumanEval
Source
jakubcwirlej.com
Author
jakcwi
Date
Why it matters
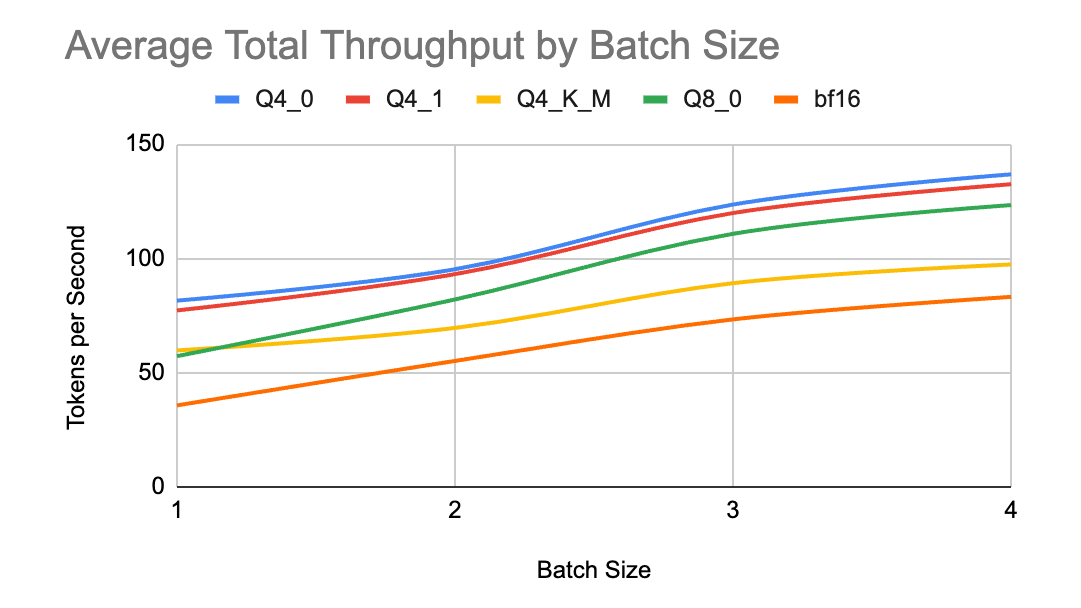
Shows what a from-scratch 160M code model reaches on one GPU (22.6% HumanEval pass@1, CPU inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → up to 364 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per second), a reference point for small local autocomplete models.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.