IFStruct puts structured-output evals on messy, real-world schemas
- Source
- x.com
- Date

Today we release IFStruct, a new benchmark to measure how well models generate structured outputs. A 350M model trained on it outperforms models more than 10x its size. 🧵

Structured output is one of the most common things we ask models to do and still where they break. Most benchmarks test with clean, finalized schema. Real requests use plain language, paste an annotated example, switch formats halfway, and slip in constraints like "no code fence" or "no commentary." (2/n)
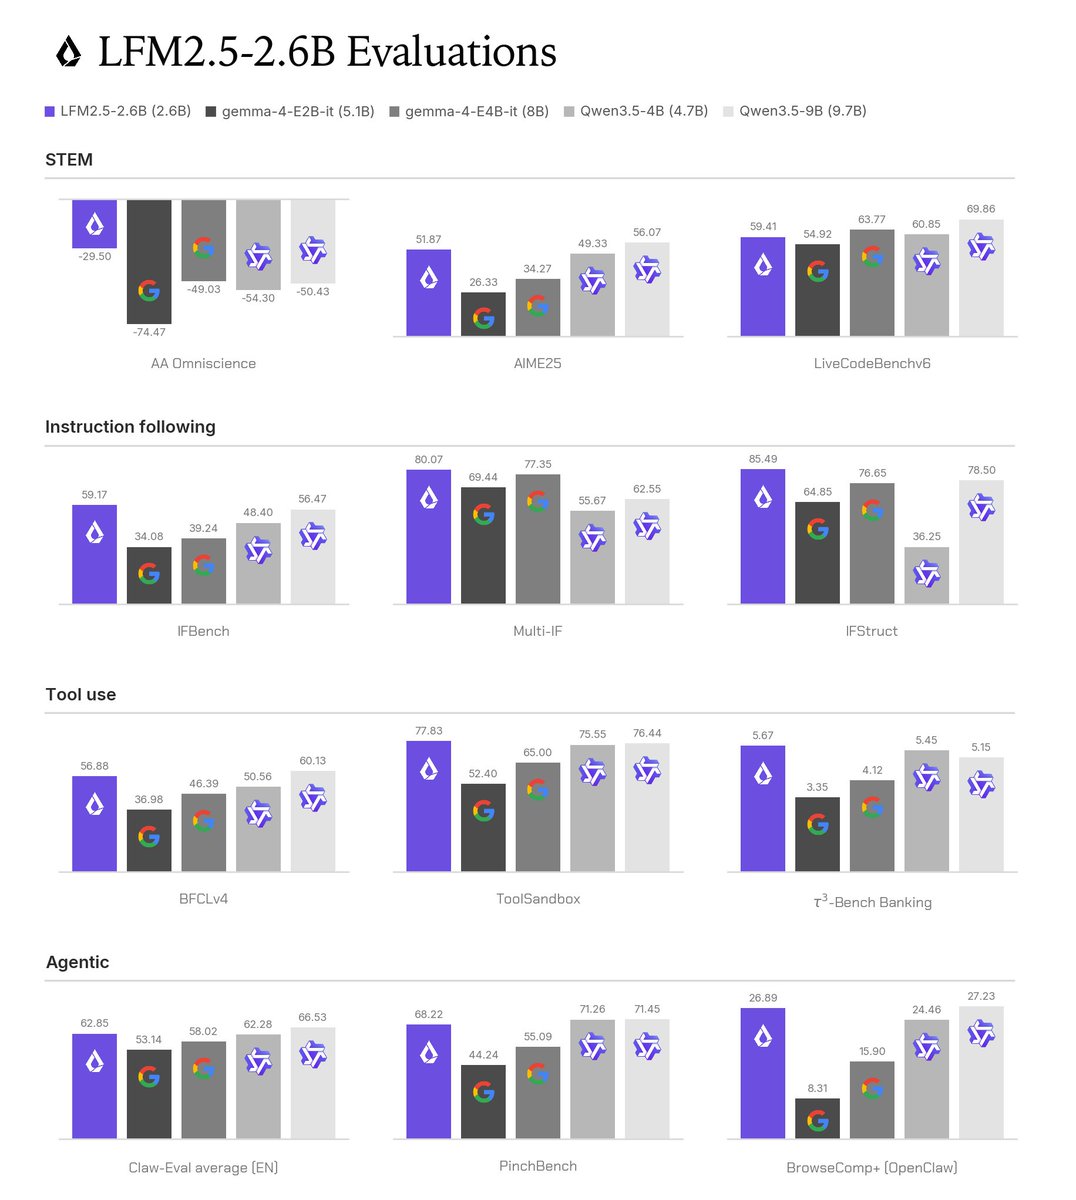
IFStruct presents requirements in all of those forms: chat requests, bullet lists with explicit paths, raw JSON Schema, annotated JSON or YAML, ASCII tables. Half are rewritten into natural prose. Scoring is binary. Every field, type, enum, bound, and count right, with no invented keys. The same generator that builds the eval builds training data just as easily. The same yes/no check that scores the benchmark can train the model. (3/n)
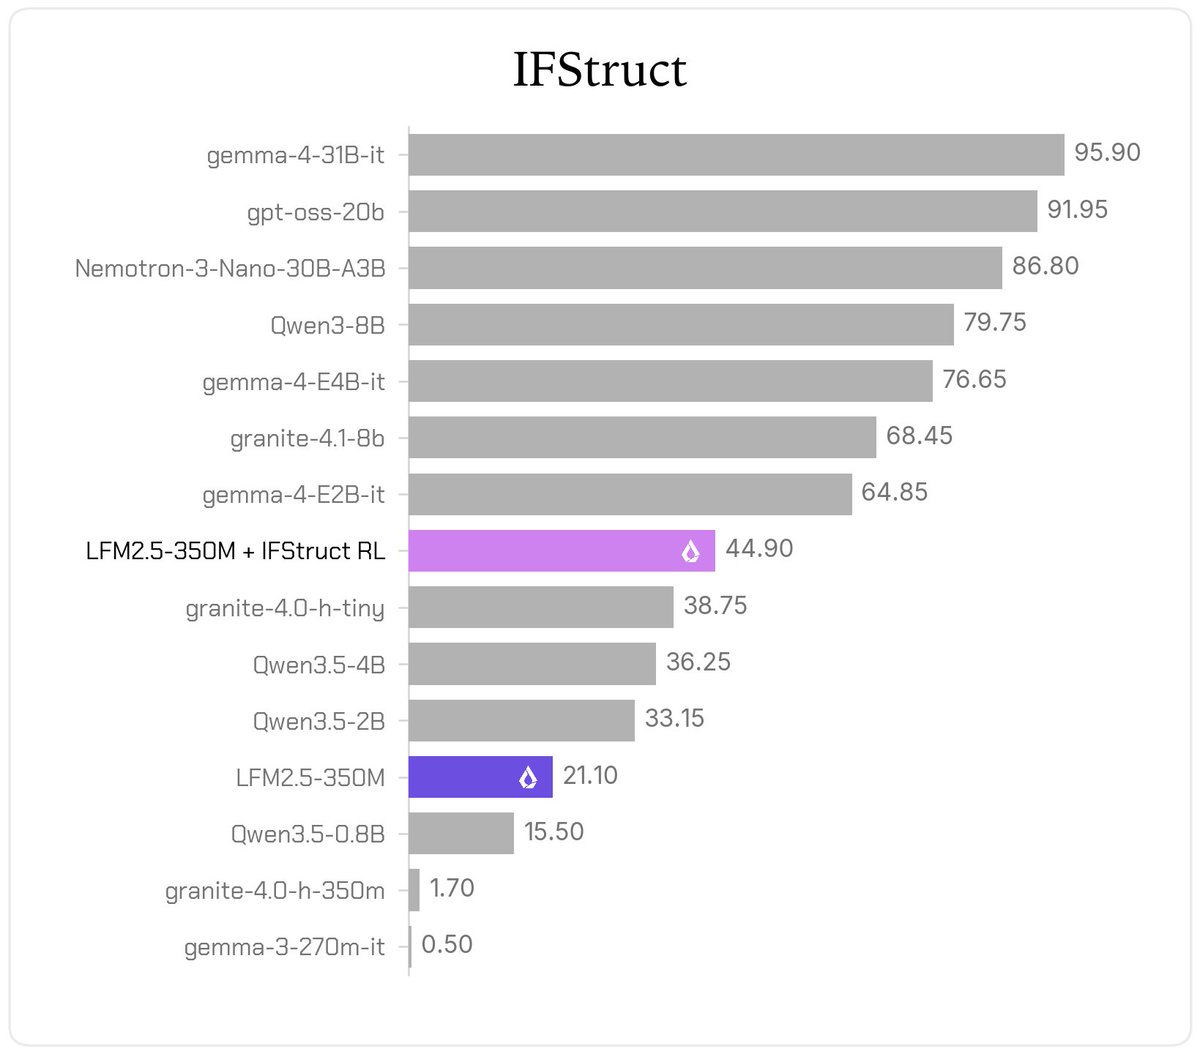
LFM2.5-350M starts at 21.10% and reaches 44.90% after training, ahead of Qwen3.5-4B at 36.25% and granite-4.0-h-tiny at 38.75%. Frontier models near 100%. (4/n)
Context
IFStruct tests whether a model can obey output requirements when people describe them inconsistently. Liquid AI's presents requirements through ordinary requests, annotated examples and formal schemas. An answer passes only if every required field, value type, limit and count is correct, without extra fields. Benchmark announcement.
The same system can generate training examples and automatically judge them. Liquid AI reports that training its 350M model increased the pass rate from 21.10% to 44.90%. That is a substantial improvement on this task, while still leaving more than half the evaluated outputs short of complete compliance. The result illustrates both the value of targeted training and the strictness of fully correct machine-readable output.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 postLiquid AI ships LFM2.5-24B-A2B open weights for local agents
 postToday we release Open d1: two open-weight multimodal models in our d1 decision…
 postLiquid AI's d1 decision model adds vision at a fraction of frontier cost
 articled1 is now available on @vercel AI gateway!We worked with the amazing vercel…

Checking sign-in…
Loading comments…