A Thai research team adapted our Dolma data-curation toolkit to build…
- Source
- x.com
- Date

A Thai research team adapted our Dolma data-curation toolkit to build Mangosteen, a 47B-token corpus for Thai LLMs. They used Dolma to filter widely used web datasets into a smaller corpus that improved Thai LLM performance despite using less data. 🧵 https://t.co/exvf02cy4U

The team saw a problem with existing Thai pretraining data: it often leaned heavily on web crawls, hadn’t been extensively audited by Thai speakers, and missed useful sources like books, research papers, authoritative sites, & YouTube subtitles.
Dolma gave the team a strong starting point, so they didn’t have to build a data-curation pipeline from scratch. Because it’s open, they could keep what worked and change what didn’t for Thai—including deduplication, quality filters, & language-specific tools.
That work became Mangosteen, the team’s 47B-token Thai pretraining corpus. Models trained on it matched or beat Thai LLMs trained on larger web datasets after filtering out lower-quality and duplicate text—showing careful curation can mean less data without worse models.

Context
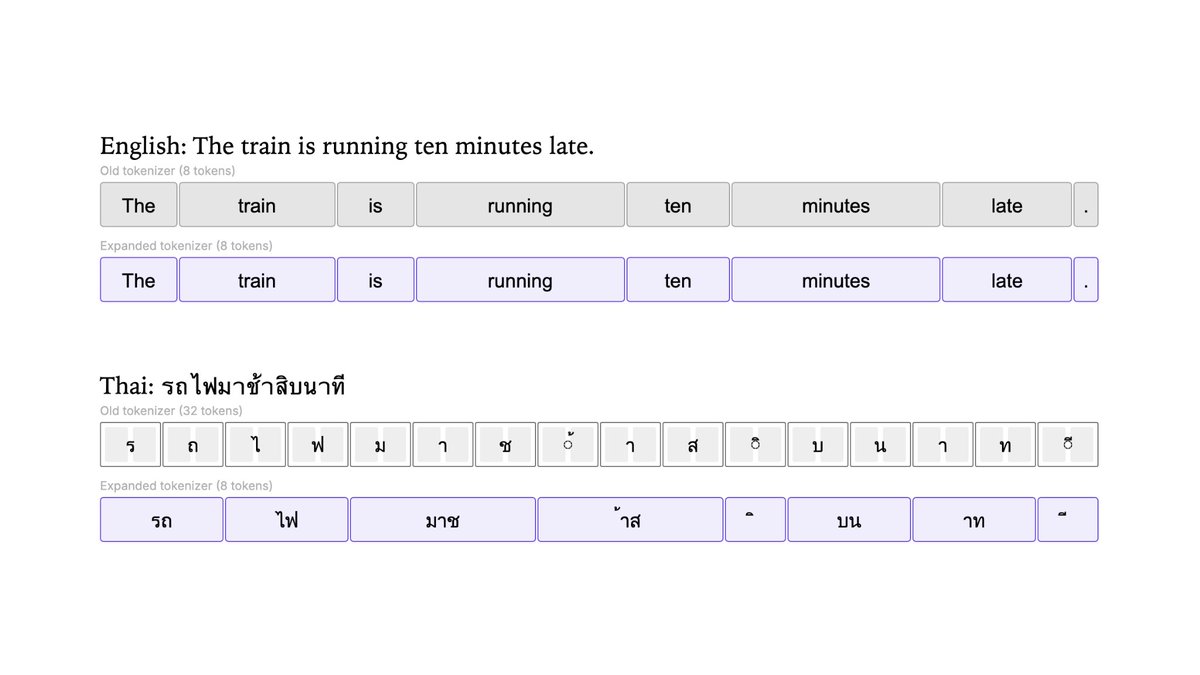
Preparing good Thai training text required changing the rules used to clean it. A Thai research team adapted Ai2's open Dolma toolkit after finding that sentence- and paragraph-based duplicate removal discarded almost all their data because Thai marks sentence boundaries differently from English. They retained useful document-level checks and changed language-specific processing and quality filters. According to Ai2's account, the resulting Mangosteen corpus supported models that matched or improved on models trained with larger web datasets. Ai2 presents this as evidence that careful curation can mean less data without worse models, a result reported for this team's tests.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…