Chain-of-Models: Cross-Model Auditing for Bias-Robust LLM Judges
- Source
- arxiv.org
- Author
- Qian Wang, Zhanzhi Lou, Zhenheng Tang, Nuo Chen, Bingsheng He
- Date
Context
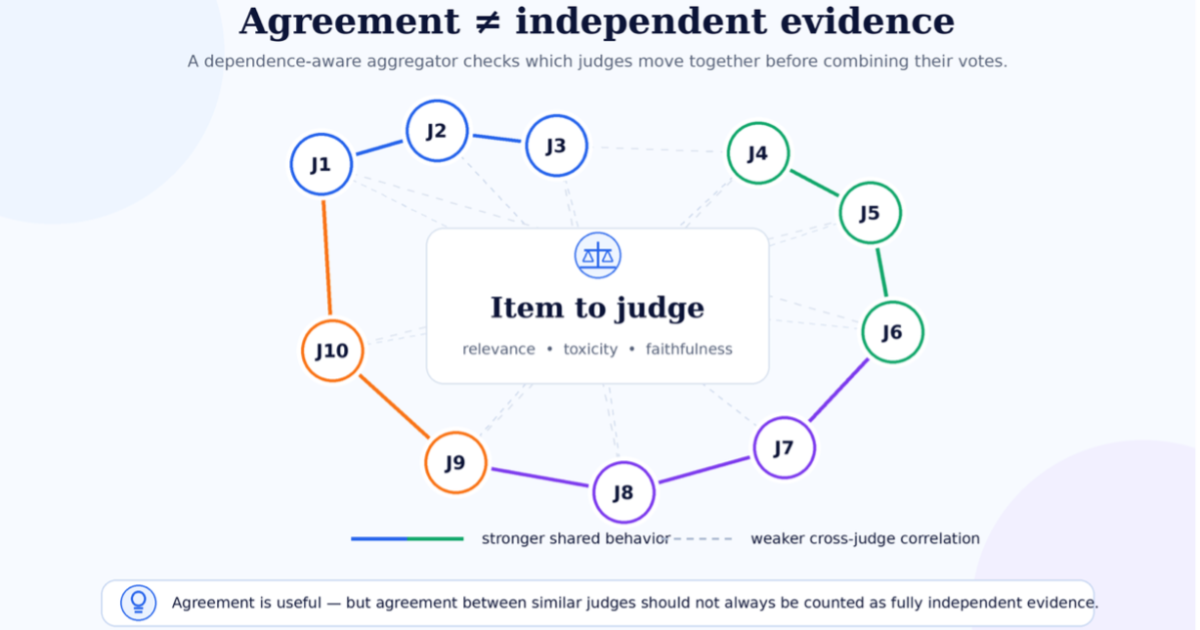
Choosing an AI reviewer requires testing how it audits another model, because its own standalone performance may not predict that . Chain-of-Models has a second model inspect the first model's reasoning before producing a final judgment. Across nine models, four bias types, and four factual datasets, the researchers found that the best auditor depended on the bias being tested. A selection rule given the bias type achieved 88.4% accuracy on the held-out , compared with 82.4% for the strongest fixed auditor. The result supports evaluating reviewer pairings for a defined failure mode rather than choosing solely by standalone scores.
- agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.
“standalone bias resistance does not predict audit effectiveness”
“the best auditor is bias-specific”
Checking sign-in…
Loading comments…