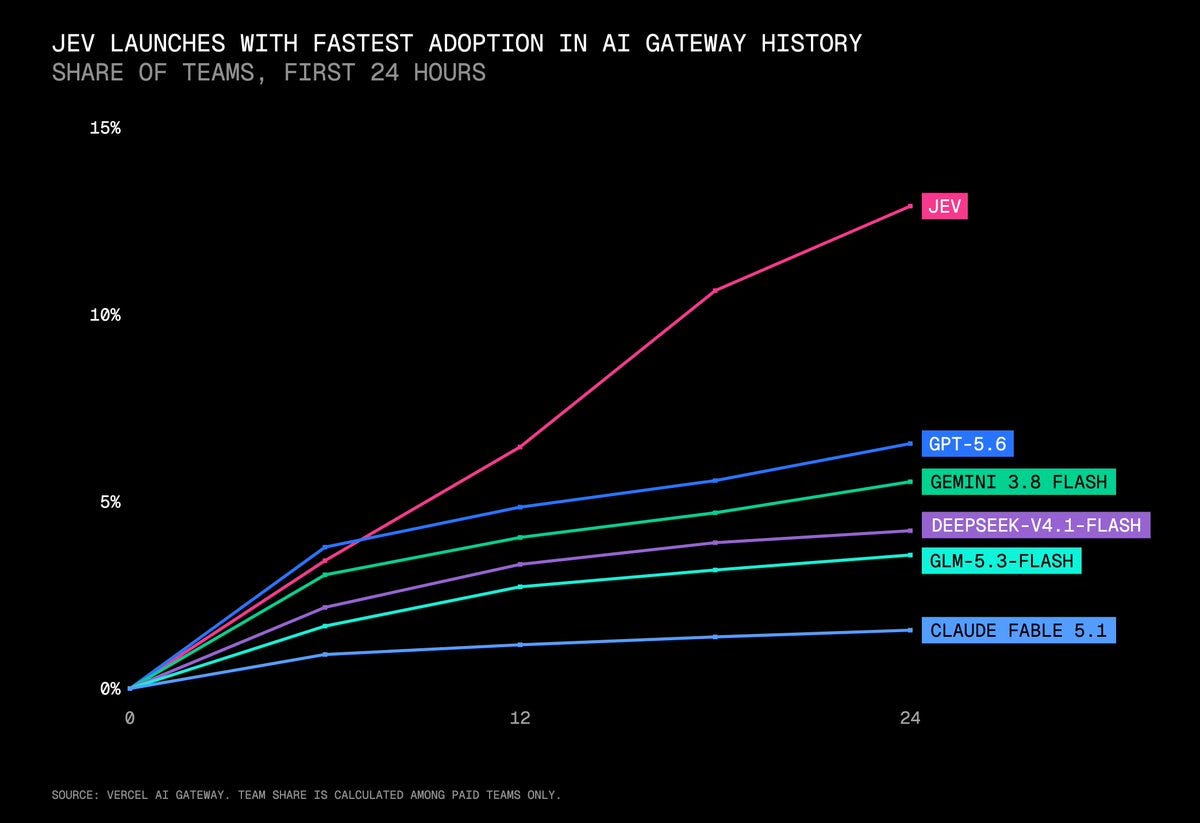
You can now load Inkling 2 Small, a 594B-parameter MoE with 17B active parameters that takes text and image input, and the JEV decision head directly in transformers.
Key takeaways · AI-distilled
In v5.23.0, every export returns an ExportedModel that you call like the original model, push to the Hub and load back on the backend's own runtime, with one API for Dynamo, ONNX Runtime, OpenVINO and ExecuTorch. The old output_path options give way to save_pretrained.
Hugging Face reports that on EmbeddingGemma2, ONNX Runtime with the TensorRT execution provider ran 7.6x faster than eager PyTorch and 1.4x faster than torch.compile on an A100, and that OpenVINO exports now decode 2.4 to 3.9x faster through fused CPU kernels.
Expert parallelism now has a selectable ep_implementation: all-reduce for CUDA-graph-friendly inference and all-to-all for training. The older ep_router expert-parallel style is removed, which the release flags as a breaking change.
The [audio] install extra is cut down to torchaudio, soundfile and soxr, dropping librosa and phonemizer, and Wav2Vec2ProcessorWithLM with pyctcdecode/kenlm language-model decoding is deprecated. Both are marked as breaking changes.
Inkling 2 Small's language backbone has 48 mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → decoder layers that each route a token to 8 of 384 experts, and its Perception Encoder-based vision transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition → feeds the model one embeddingA list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.Full definition → per 40x40 pixel image patch.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.