Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters
- Source
- arxiv.org
- Author
- Charlie Snell et al.
- Date
Context
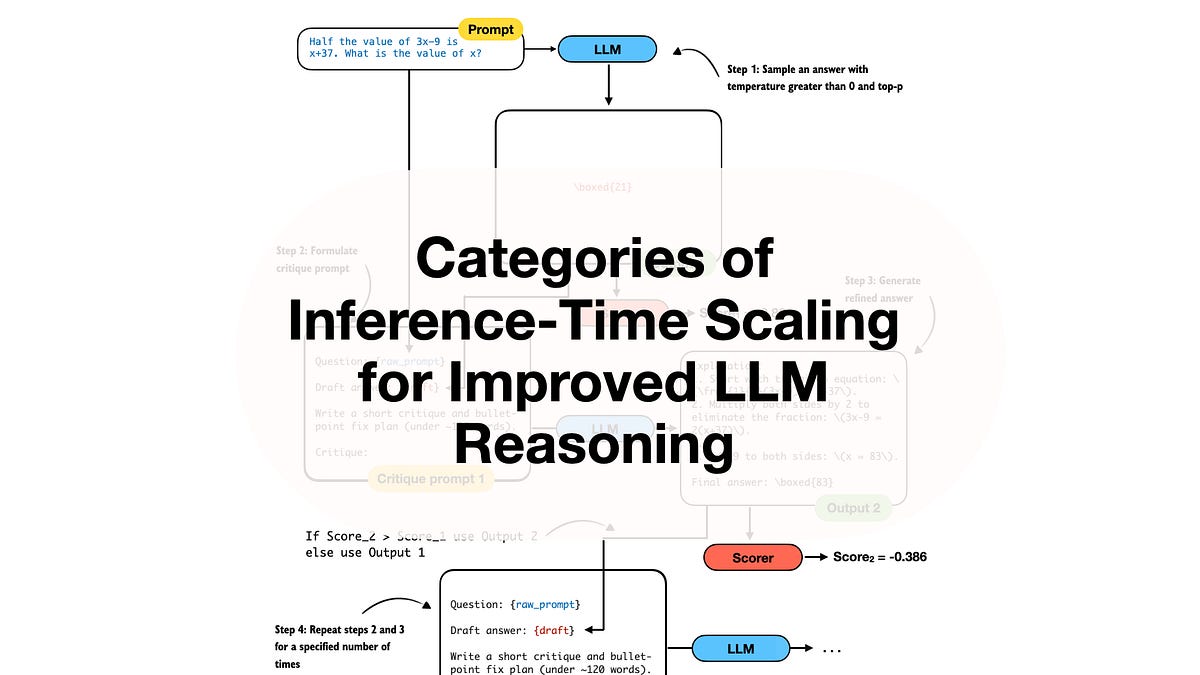
Extra computation while answering works better when its strategy matches the problem. In this 2024 study, researchers tested specially fine-tuned models on mathematics problems, comparing repeated answer revision with searching solutions using a model that scores intermediate steps. Easier problems could benefit from refining an existing answer; harder ones could require exploring different approaches. Choosing the strategy according to difficulty improved efficiency over generating independent answers and selecting the highest-scoring one. The paper reports more than fourfold compute savings in its comparisons. The result concerns allocating work among tested methods, rather than merely asking a model to produce a longer response.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.

Checking sign-in…
Loading comments…