Categories of Inference-Time Scaling for Improved LLM Reasoning
- Source
- magazine.sebastianraschka.com
- Author
- Sebastian Raschka, PhD
- Date
Context
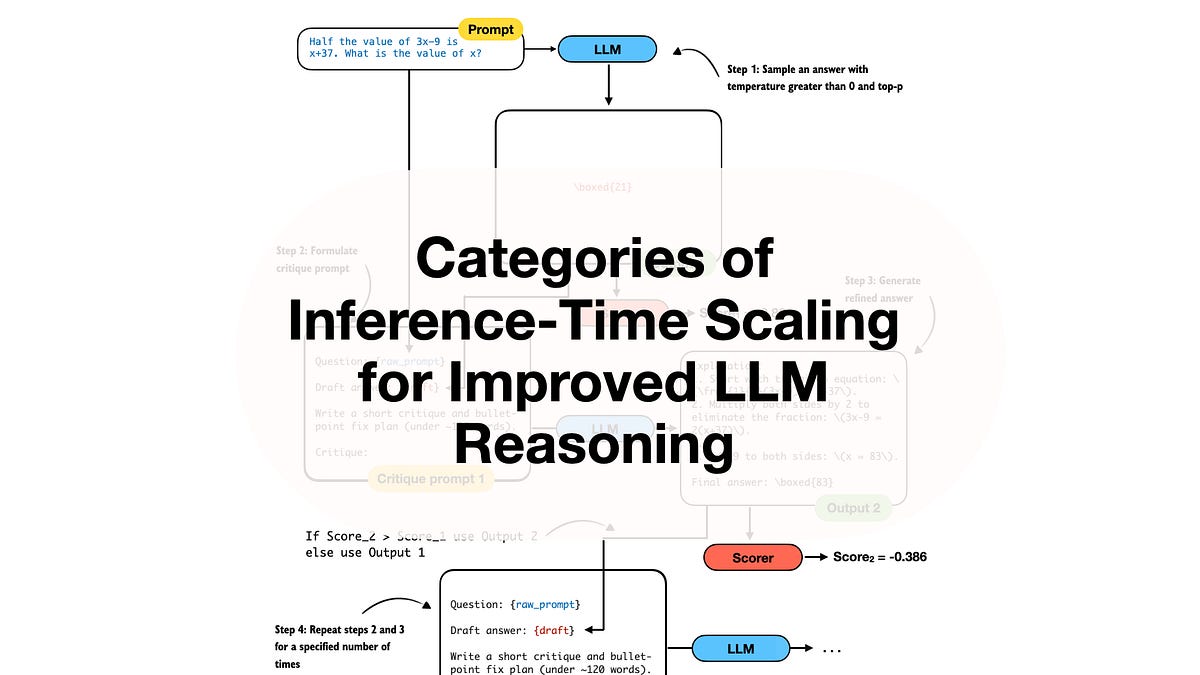
A can spend more computation producing an answer without changing what it learned during training. That is the distinction Sebastian Raschka draws in an inference-time scaling overview. The model's learned parameters stay fixed while the answering process gets more time and computing resources.
Raschka connects this to the older idea of combining multiple models' outputs: additional work during use can improve the result even without retraining. This creates a separate engineering choice from making the underlying model larger or training it longer. The question is whether the improvement in answers is worth the additional delay and computation for the task.
- Two separate knobs raise accuracy: compute spent training and compute spent generating. OpenAI's o1 curves showed both work, and the practical move is to turn both, training a stronger model and then scaling its on top of that.
- is an old idea in new clothes. Classic ML ensembles bought accuracy the same way, by running more computation at prediction time instead of changing the model.
- It travels under several names, test-time scaling, inference-compute scaling, inference scaling, all meaning training-free methods that leave the weights untouched. That is why they apply to any model, including ones you did not train.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- test-time compute — Spending more computation when the model answers — thinking longer, trying multiple attempts — to buy accuracy without training a bigger model.
- chain-of-thought — Having a model write out intermediate reasoning steps before its answer, which markedly improves performance on hard problems.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
“It takes the base model from about 15 percent to around 52 percent accuracy, which makes it one of the most rewarding pieces of the book so far.”
 articleScaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model ParametersCharlie Snell et al.
 articleDiverse reasoning traces teach LLMs to make better decisionswww.amazon.science
 articleAdaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scalingbair.berkeley.edu
Checking sign-in…
Loading comments…