Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster
Source
engineering.fb.com
Date
Why it matters
Shows what a gigawatt-scale training site takes (closed-loop liquid cooling, goodput above 85%), informing how practitioners think about future frontier model capacity and cost.
Key takeaways · AI-distilled
Meta reports more than 85% goodput on Muse Wonder pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → runs and more than 90% on RL runs, with a mean time between interruptions of about 47k GPU hours, since raised above 54K GPU hours through fleet firmware fixes.
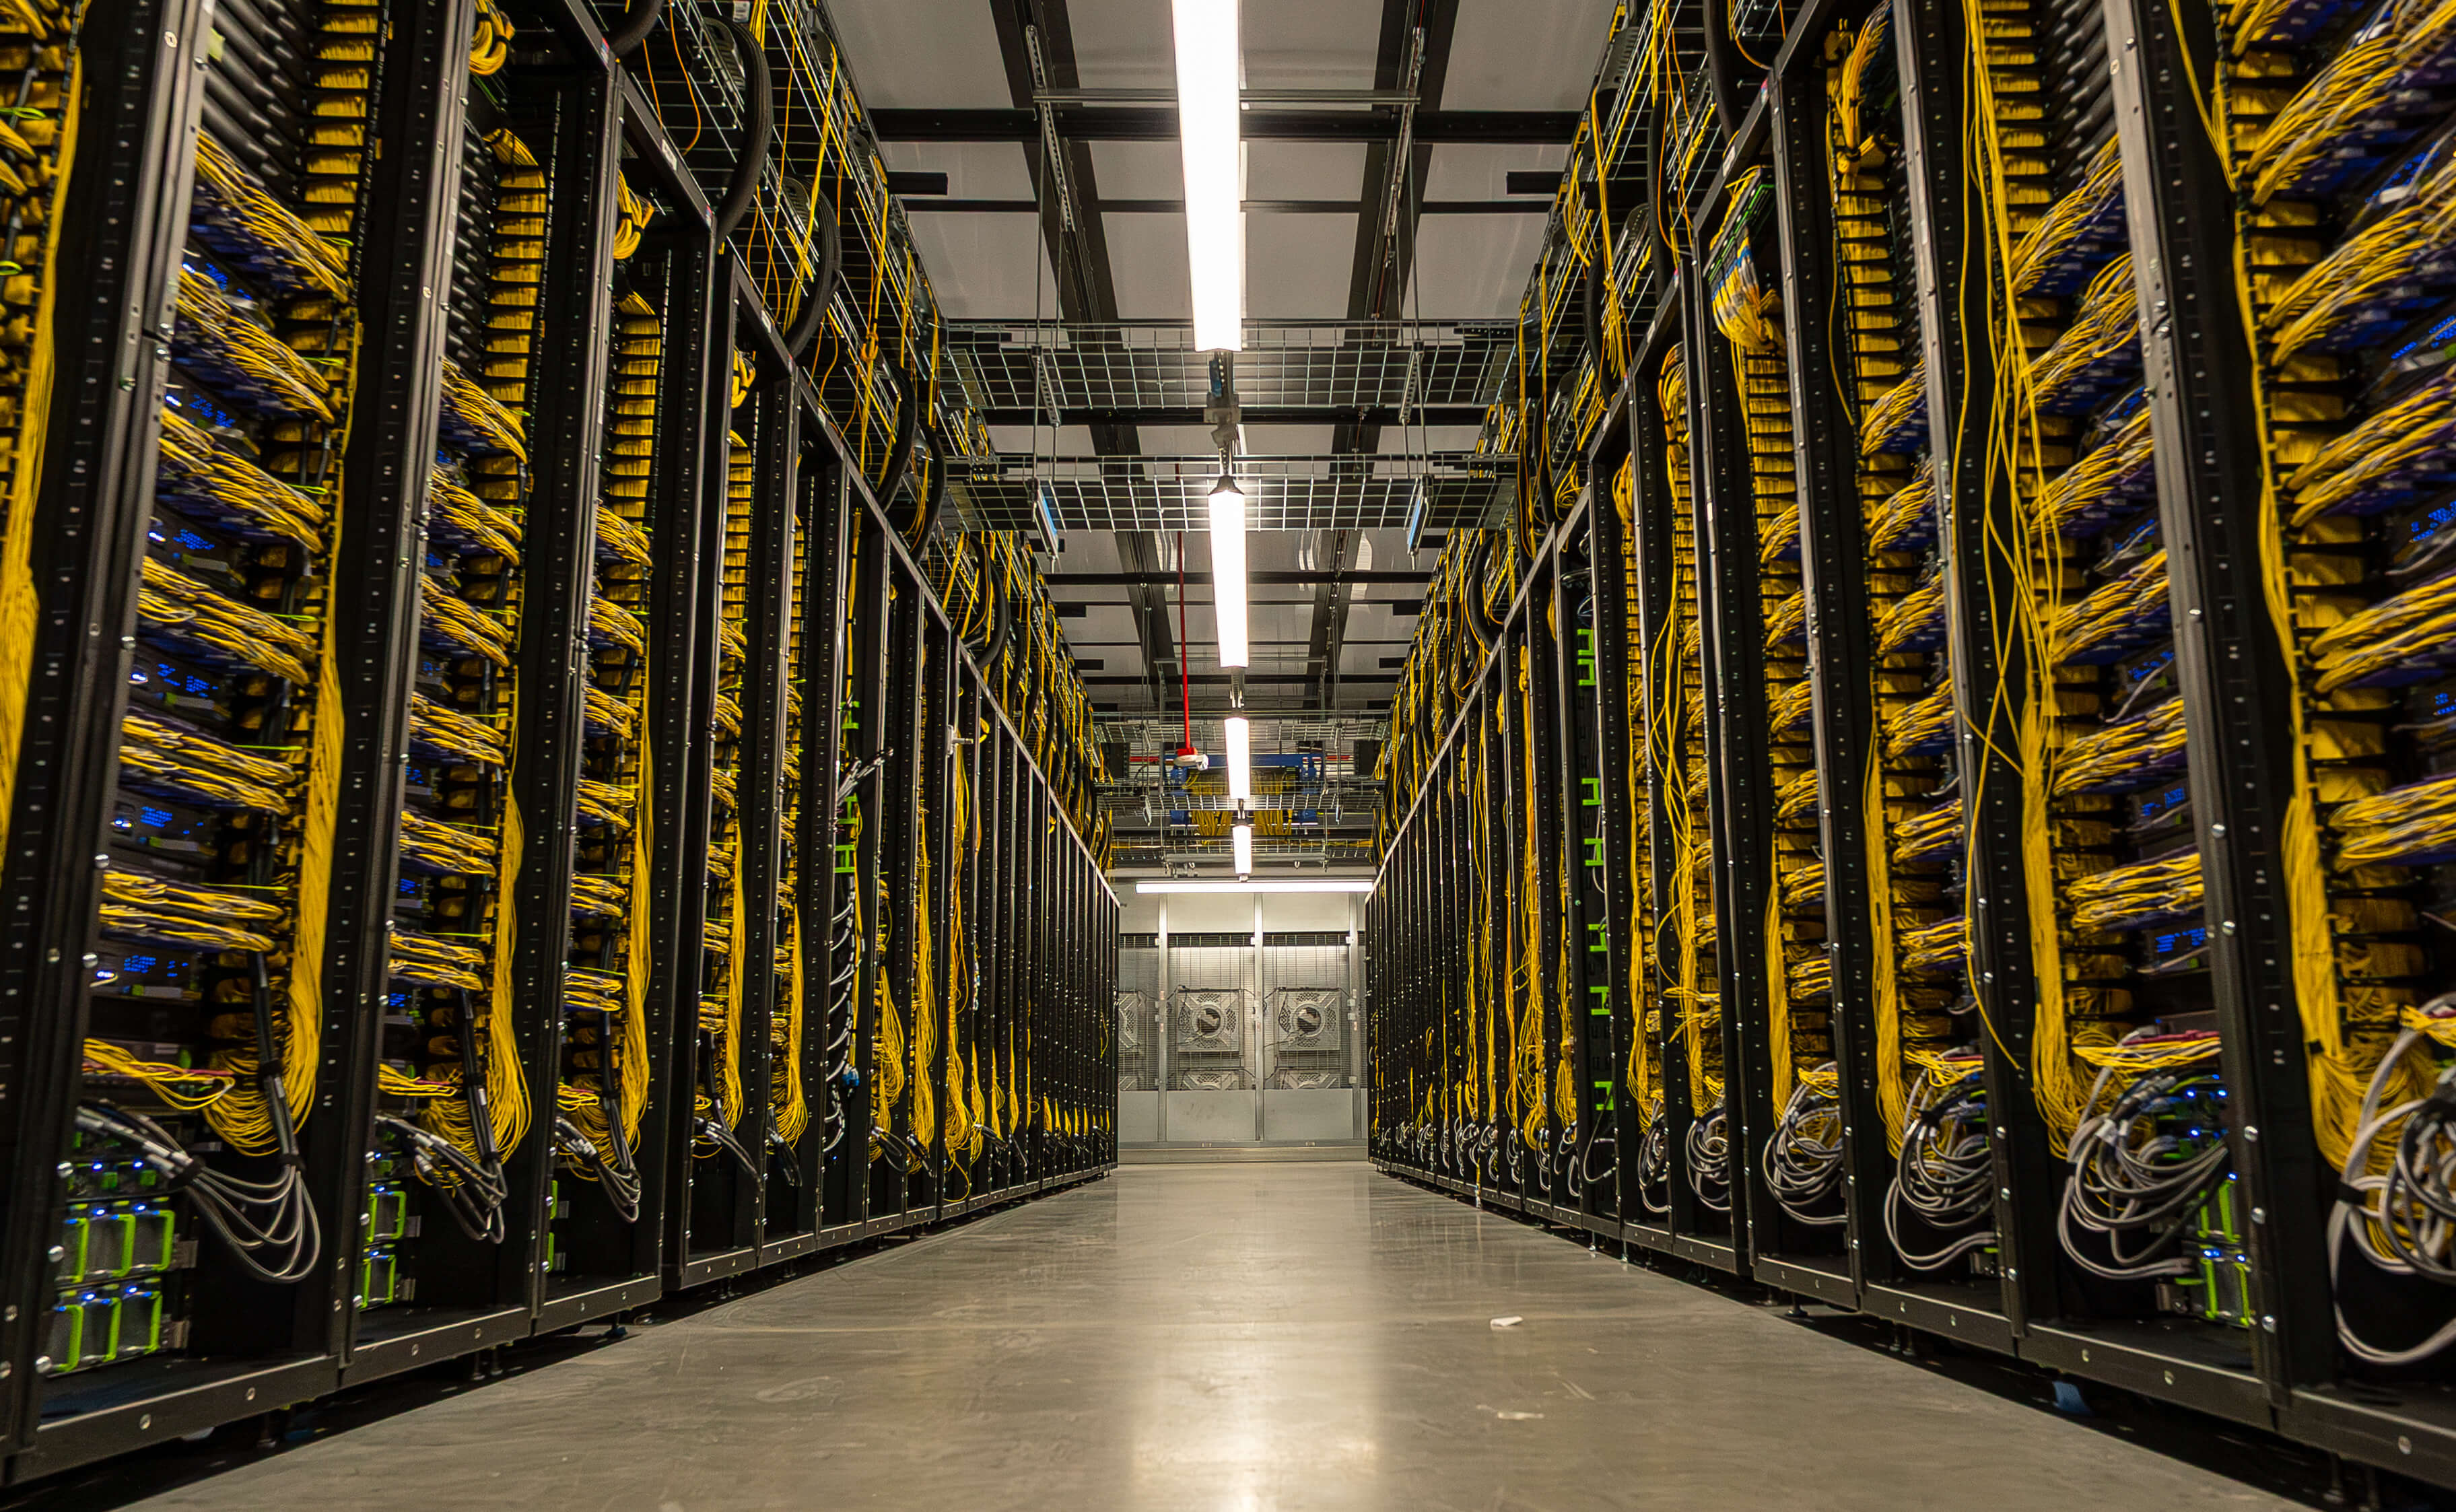
Each NVL72 rack runs a 64-GPU slice and keeps eight GPUs as in-rack spares, so a failed GPU is swapped and the job restarts from checkpoint. With about 2% spare racks, a 32,768-GPU run needs 523 racks, about 13% above the active footprint.
Meta says interruptions peaked near 1,000 events per 8K GPUs per day in mid-2025 and fell 99% over a year. NVLink signal integrity across 600,000+ connections was the main early bottleneck on GB200; the target is two per 8K GPUs per day.
Synchronized training swings cluster power by 30-40%, and starting or pausing a large job can shift tens of megawatts in seconds. Meta's Dynamo Dimmer lowers GPU power caps gradually near the electrical ceiling instead of stopping jobs.
Meta deployed its GB200 racks with 800G of scale-out per GPU rather than 400G, because GB200 raised compute and memory bandwidth over H100 while per-GPU scale-out bandwidth would otherwise have stayed flat.
Terms in this piece · Glossary
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
 articleThe Future of Meta Superintelligence: A 1 Year Progress UpdateMax Kan
 articlexAI’s Colossus 2 – First Gigawatt Datacenter In The World, Unique RL Methodology, Capital RaiseJeremie Eliahou Ontiveros
 articleRun Local Agentic AI Workflows with Meta’s Muse Glimmer on NVIDIAMichelle Horton