Run Local Agentic AI Workflows with Meta’s Muse Glimmer on NVIDIA
- Source
- Michelle Horton
- Author
- Michelle Horton
- Date
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Concrete numbers on running a capable agentic model locally, which changes the build-vs-API calculus for on-device agents.
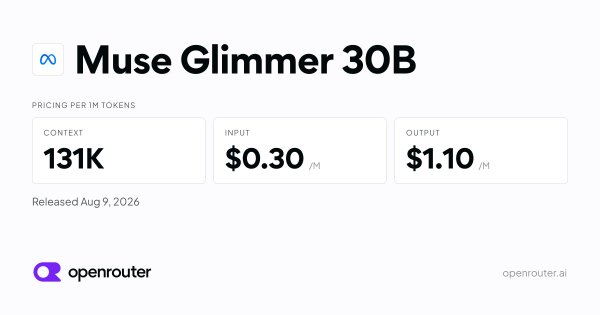
“Meta returns to the open source ecosystem with the release of Muse Glimmer, a 30B open-weight dense model with a 120K+ context window built for local AI agentic work.”
Rajath Narasimha and Sachin Beldona
“Muse Glimmer uses a dense architecture that activates every parameter for each token it processes, with no routing, expert selection, or variance across token pathways.”
Rajath Narasimha and Sachin Beldona
“It’s large enough for complex multi-step reasoning, but small enough to fit within the VRAM of a single NVIDIA GPU, with no need for model sharding, CPU offloading, or using external endpoints.”
Rajath Narasimha and Sachin Beldona
“On NVIDIA Blackwell Ultra, Muse Glimmer delivers over 20K tokens/sec/GPU at BF16/NVF4 precision, with the throughput-interactivity curve showing the 30B dense architecture sustaining high concurrency without the routing overhead of MoE models.”
Rajath Narasimha and Sachin Beldona
Checking sign-in…
Loading comments…