LFM2.5 24B A2B DSpark released
- Source
- huggingface.co
- Author
- Liquid AI model releases
- Date
Context
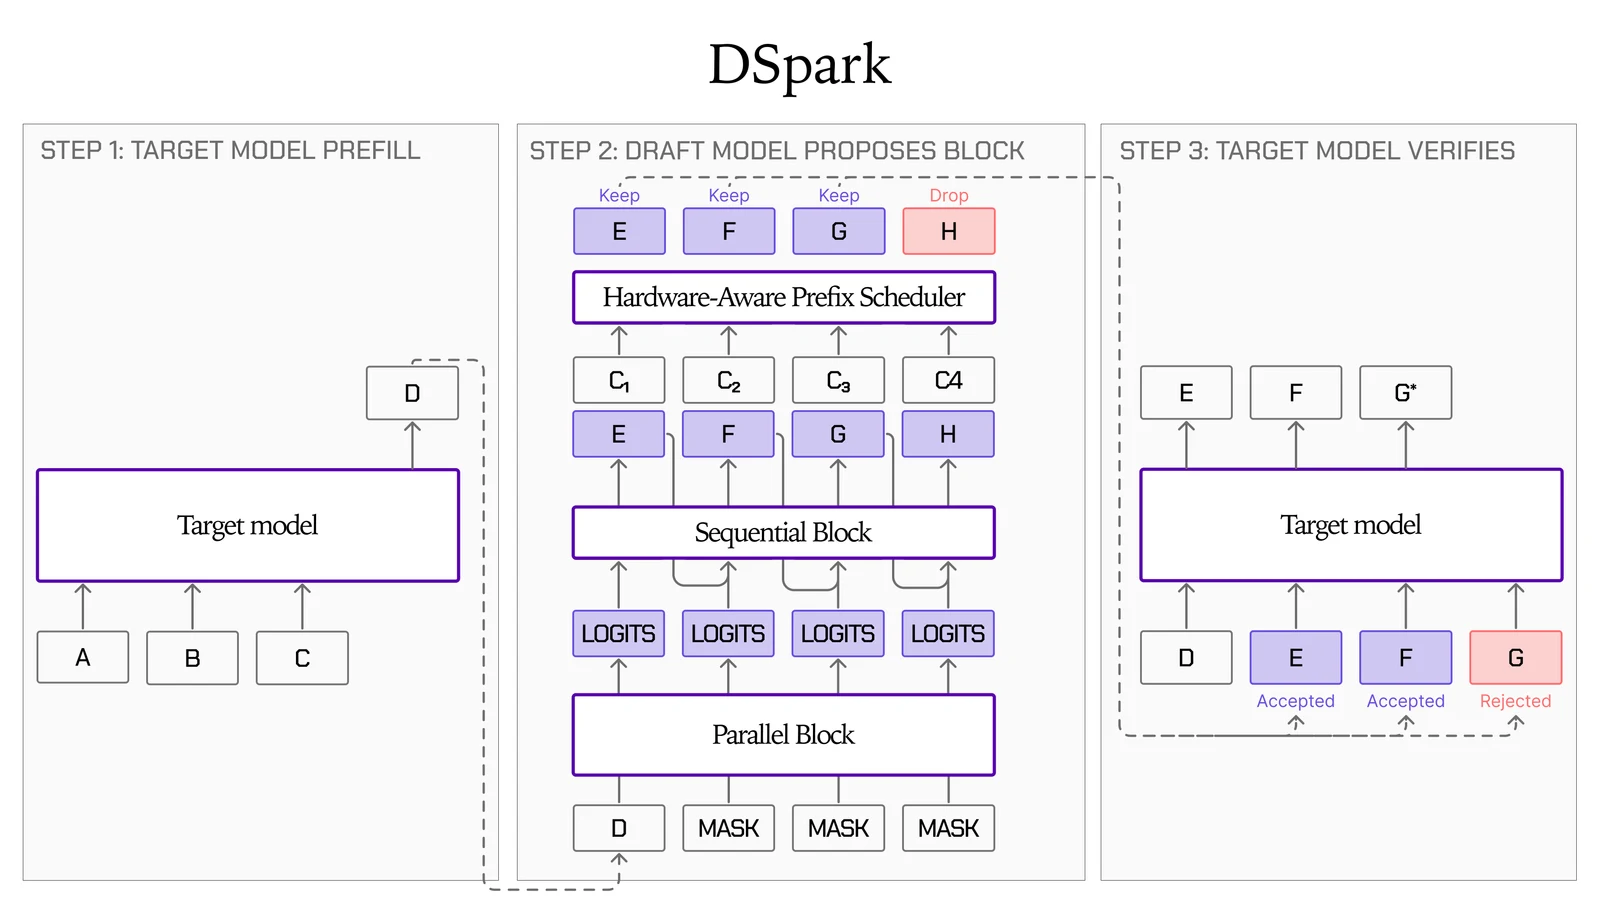
LFM2.5-24B-A2B-DSpark is not a model to use on its own. It is a 327.7-million-parameter draft model that runs alongside Liquid AI's LFM2.5-24B-A2B to make that larger model generate text faster. This technique, , has the small drafter propose a block of upcoming tokens and the large target model check them all in a single forward pass, keeping the ones it accepts, so one expensive pass can produce several tokens instead of one. Liquid's August DSpark post, which introduced drafters for three smaller LFM2.5 models (earlier coverage), describes DSpark as drafting a whole block in parallel, adding a small head that makes each drafted token depend on the one before it, and adding a confidence head that predicts which drafted tokens will be accepted. The new card lists the same parts for this drafter: five layers, a Markov head, a confidence head and a block size of 9.
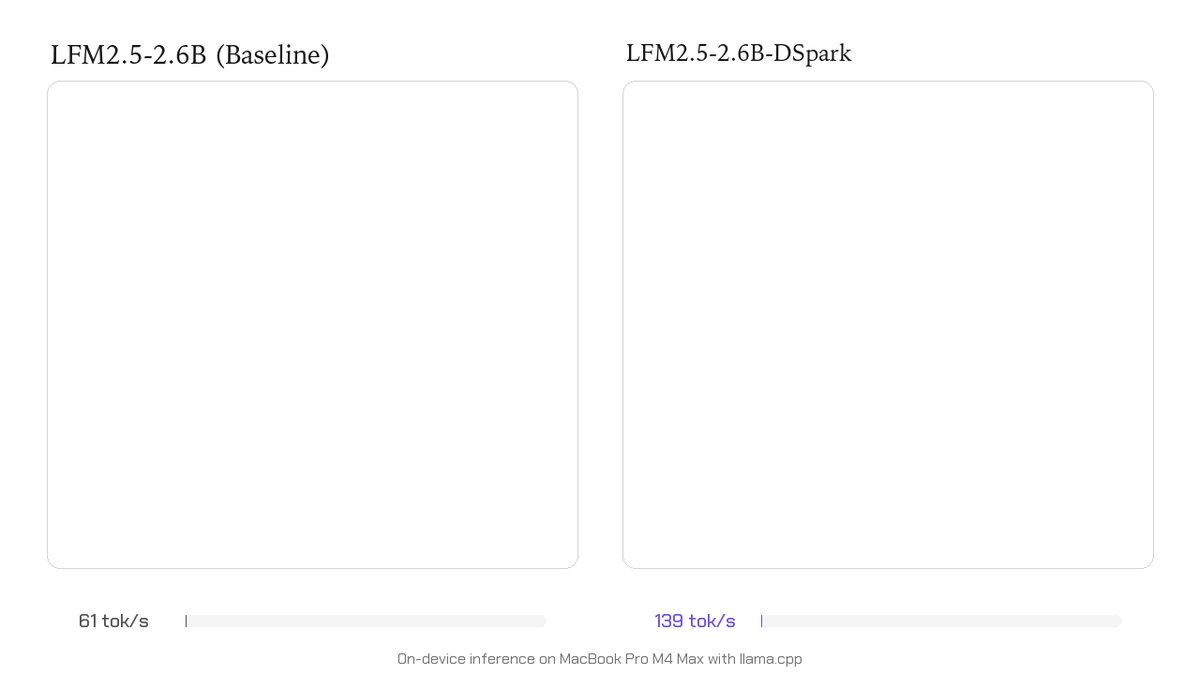
Liquid's measurements for this pairing were taken on one NVIDIA B300 running the FP8 version of the target in SGLang at temperature 0. Averaged over eight datasets, output throughput was 2.38 times the target alone with one request at a time, ranging from 1.71 times on GSM8K to 3.08 times on MBPP, 2.69 times with 32 concurrent requests and 1.71 times with 256. At one request, an average of 5.16 tokens came out of each verification step, against a ceiling of 10. The August post explains the general pattern behind the smaller gain at high load: decoding is limited mostly by moving weights from memory, which speculation exploits, but as concurrency rises the hardware becomes limited by computation instead, and verifying extra draft tokens adds to that work.
These are Liquid's own throughput figures, and the card says they measure performance, not task accuracy. It is also more cautious than the August post, which said greedy output is identical to the baseline by construction: the 24B card warns that floating-point differences between batched verification and plain decoding can produce different text, even under greedy sampling, and points to the target model's card for quality benchmarks. The card documents only an SGLang setup, which needs a recent build that includes two named SGLang pull requests. The 24B-A2B target model itself was released the week before (earlier coverage).
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…