Today, Xiaomi releases MiMo, our first open-source reasoning model.
- Source
- x.com
- Date

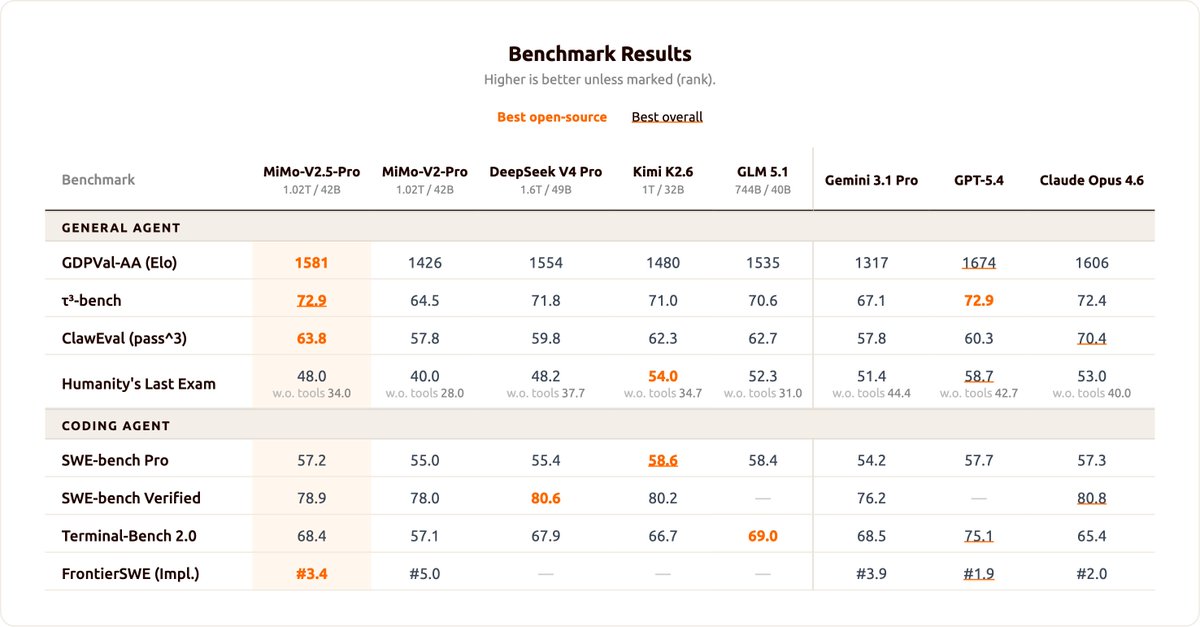
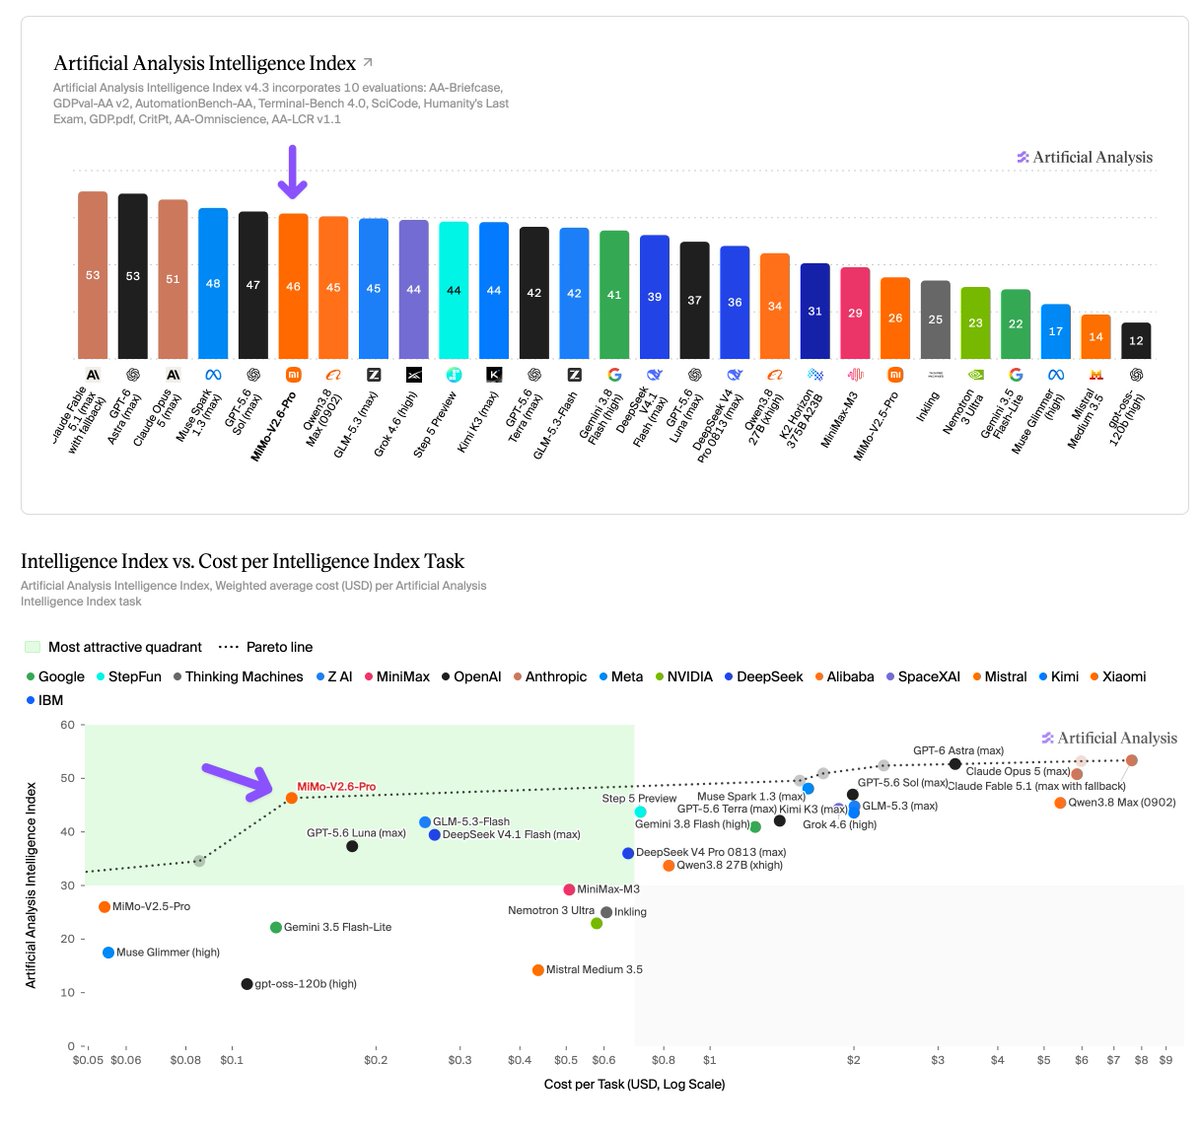
Today, Xiaomi releases MiMo, our first open-source reasoning model. At 7B parameters, it’s optimized for reasoning through pre-training and post-training, surpassing OpenAI’s o1-mini and QwQ-32B-Preview on AIME 2024-2025 and LiveCodeBench v5 benchmarks. #XiaomiMiMo #MiMo7B

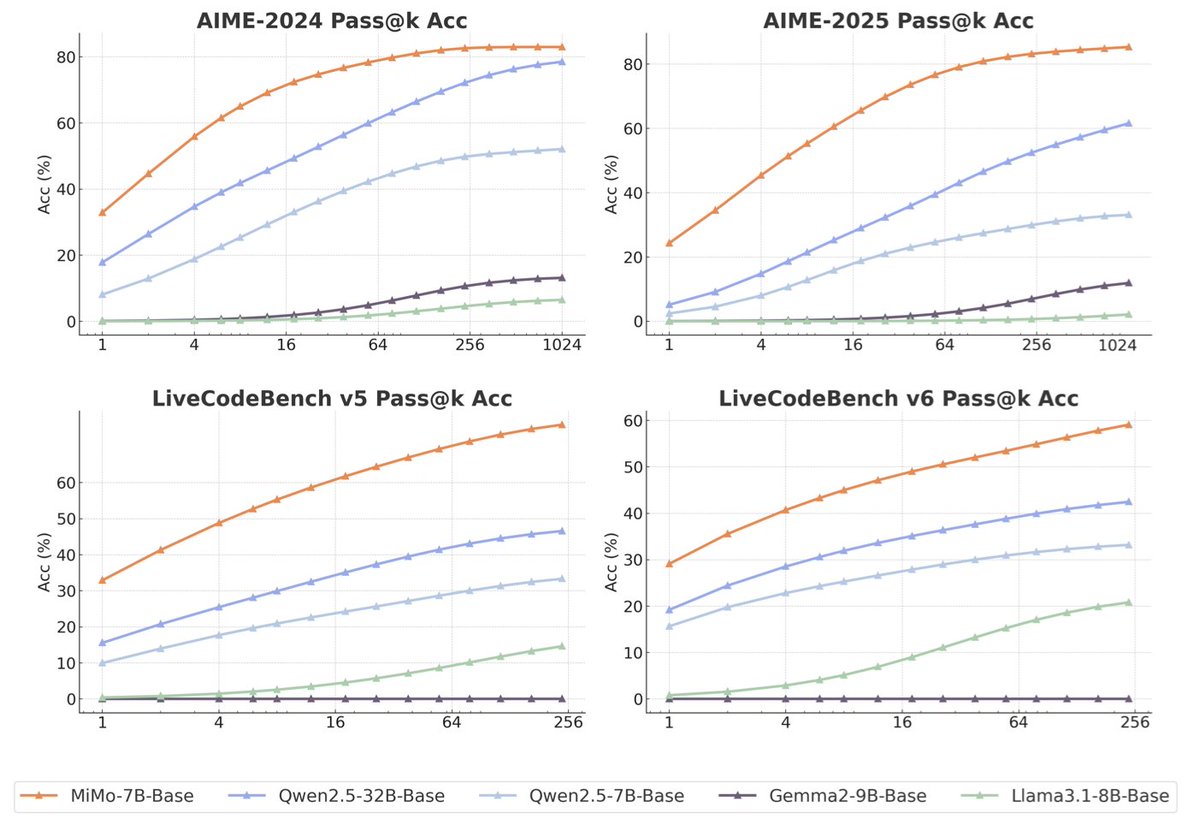
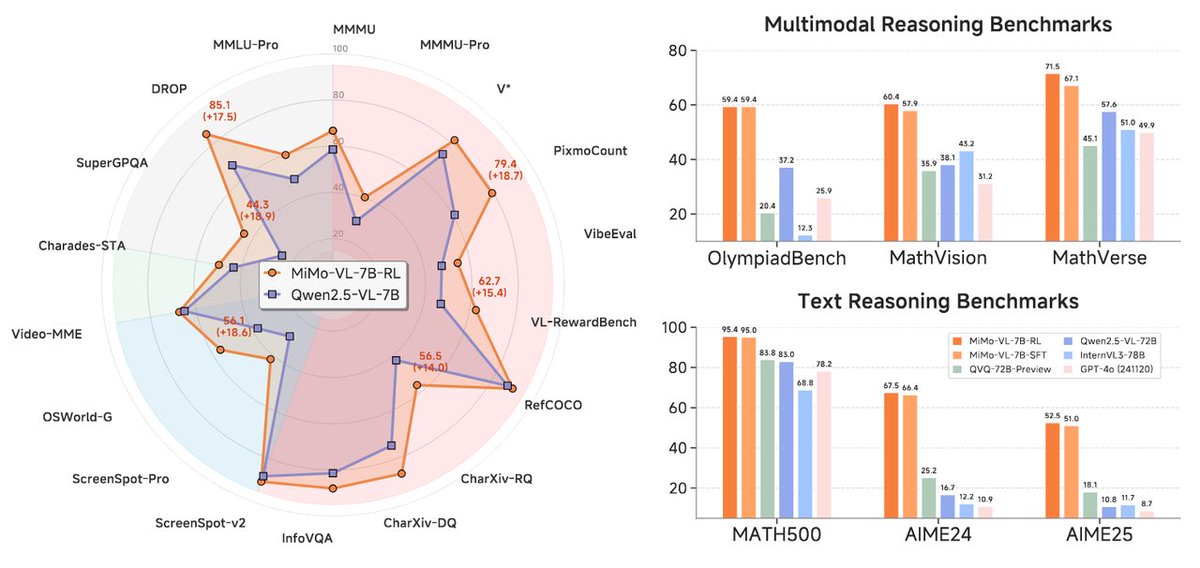
MiMo-7B-Base achieves significantly higher pass@k scores in reasoning benchmarks than all compared models, including the 32B baseline, across all benchmarks and evaluated k values. These results highlight the exceptional reasoning capabilities of MiMo-7B-Base.
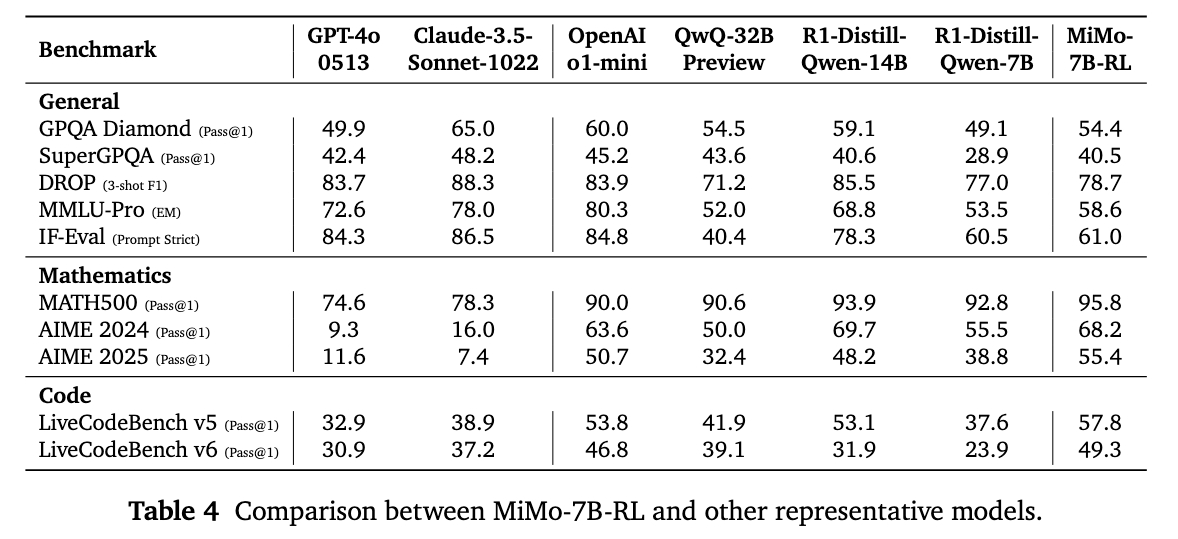
MiMo-7B-RL not only excels in code and algorithmic tasks but also outperforms both QwQ-32B-Preview and DeepSeek-R1-Distill-Qwen-7B across general tasks, even when the reinforcement learning evaluation is limited to mathematics and code problems.
Both the MiMo-7B-Base, SFT, RL-Zero and RL model checkpoints are now open-sourced and available at: https://t.co/Odu43jXTJp For further details, please refer to the technical report: https://t.co/QAwZx5tBeD
Context
Xiaomi's MiMo lab released MiMo-7B, its first open-source , reporting that the 7B model surpasses OpenAI's o1-mini and QwQ-32B-Preview on the AIME 2024-2025 math benchmarks and LiveCodeBench v5. The company also reports its RL-trained version outperforms DeepSeek-R1-Distill-Qwen-7B on general tasks even though its reinforcement learning was restricted to math and code problems.
Xiaomi open-sourced every stage of the training pipeline, the base model, the supervised fine-tuned version, and both an RL-Zero and a final RL checkpoint, rather than only the finished model, which lets outside researchers study how each training stage changed the model's behavior.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
Checking sign-in…
Loading comments…