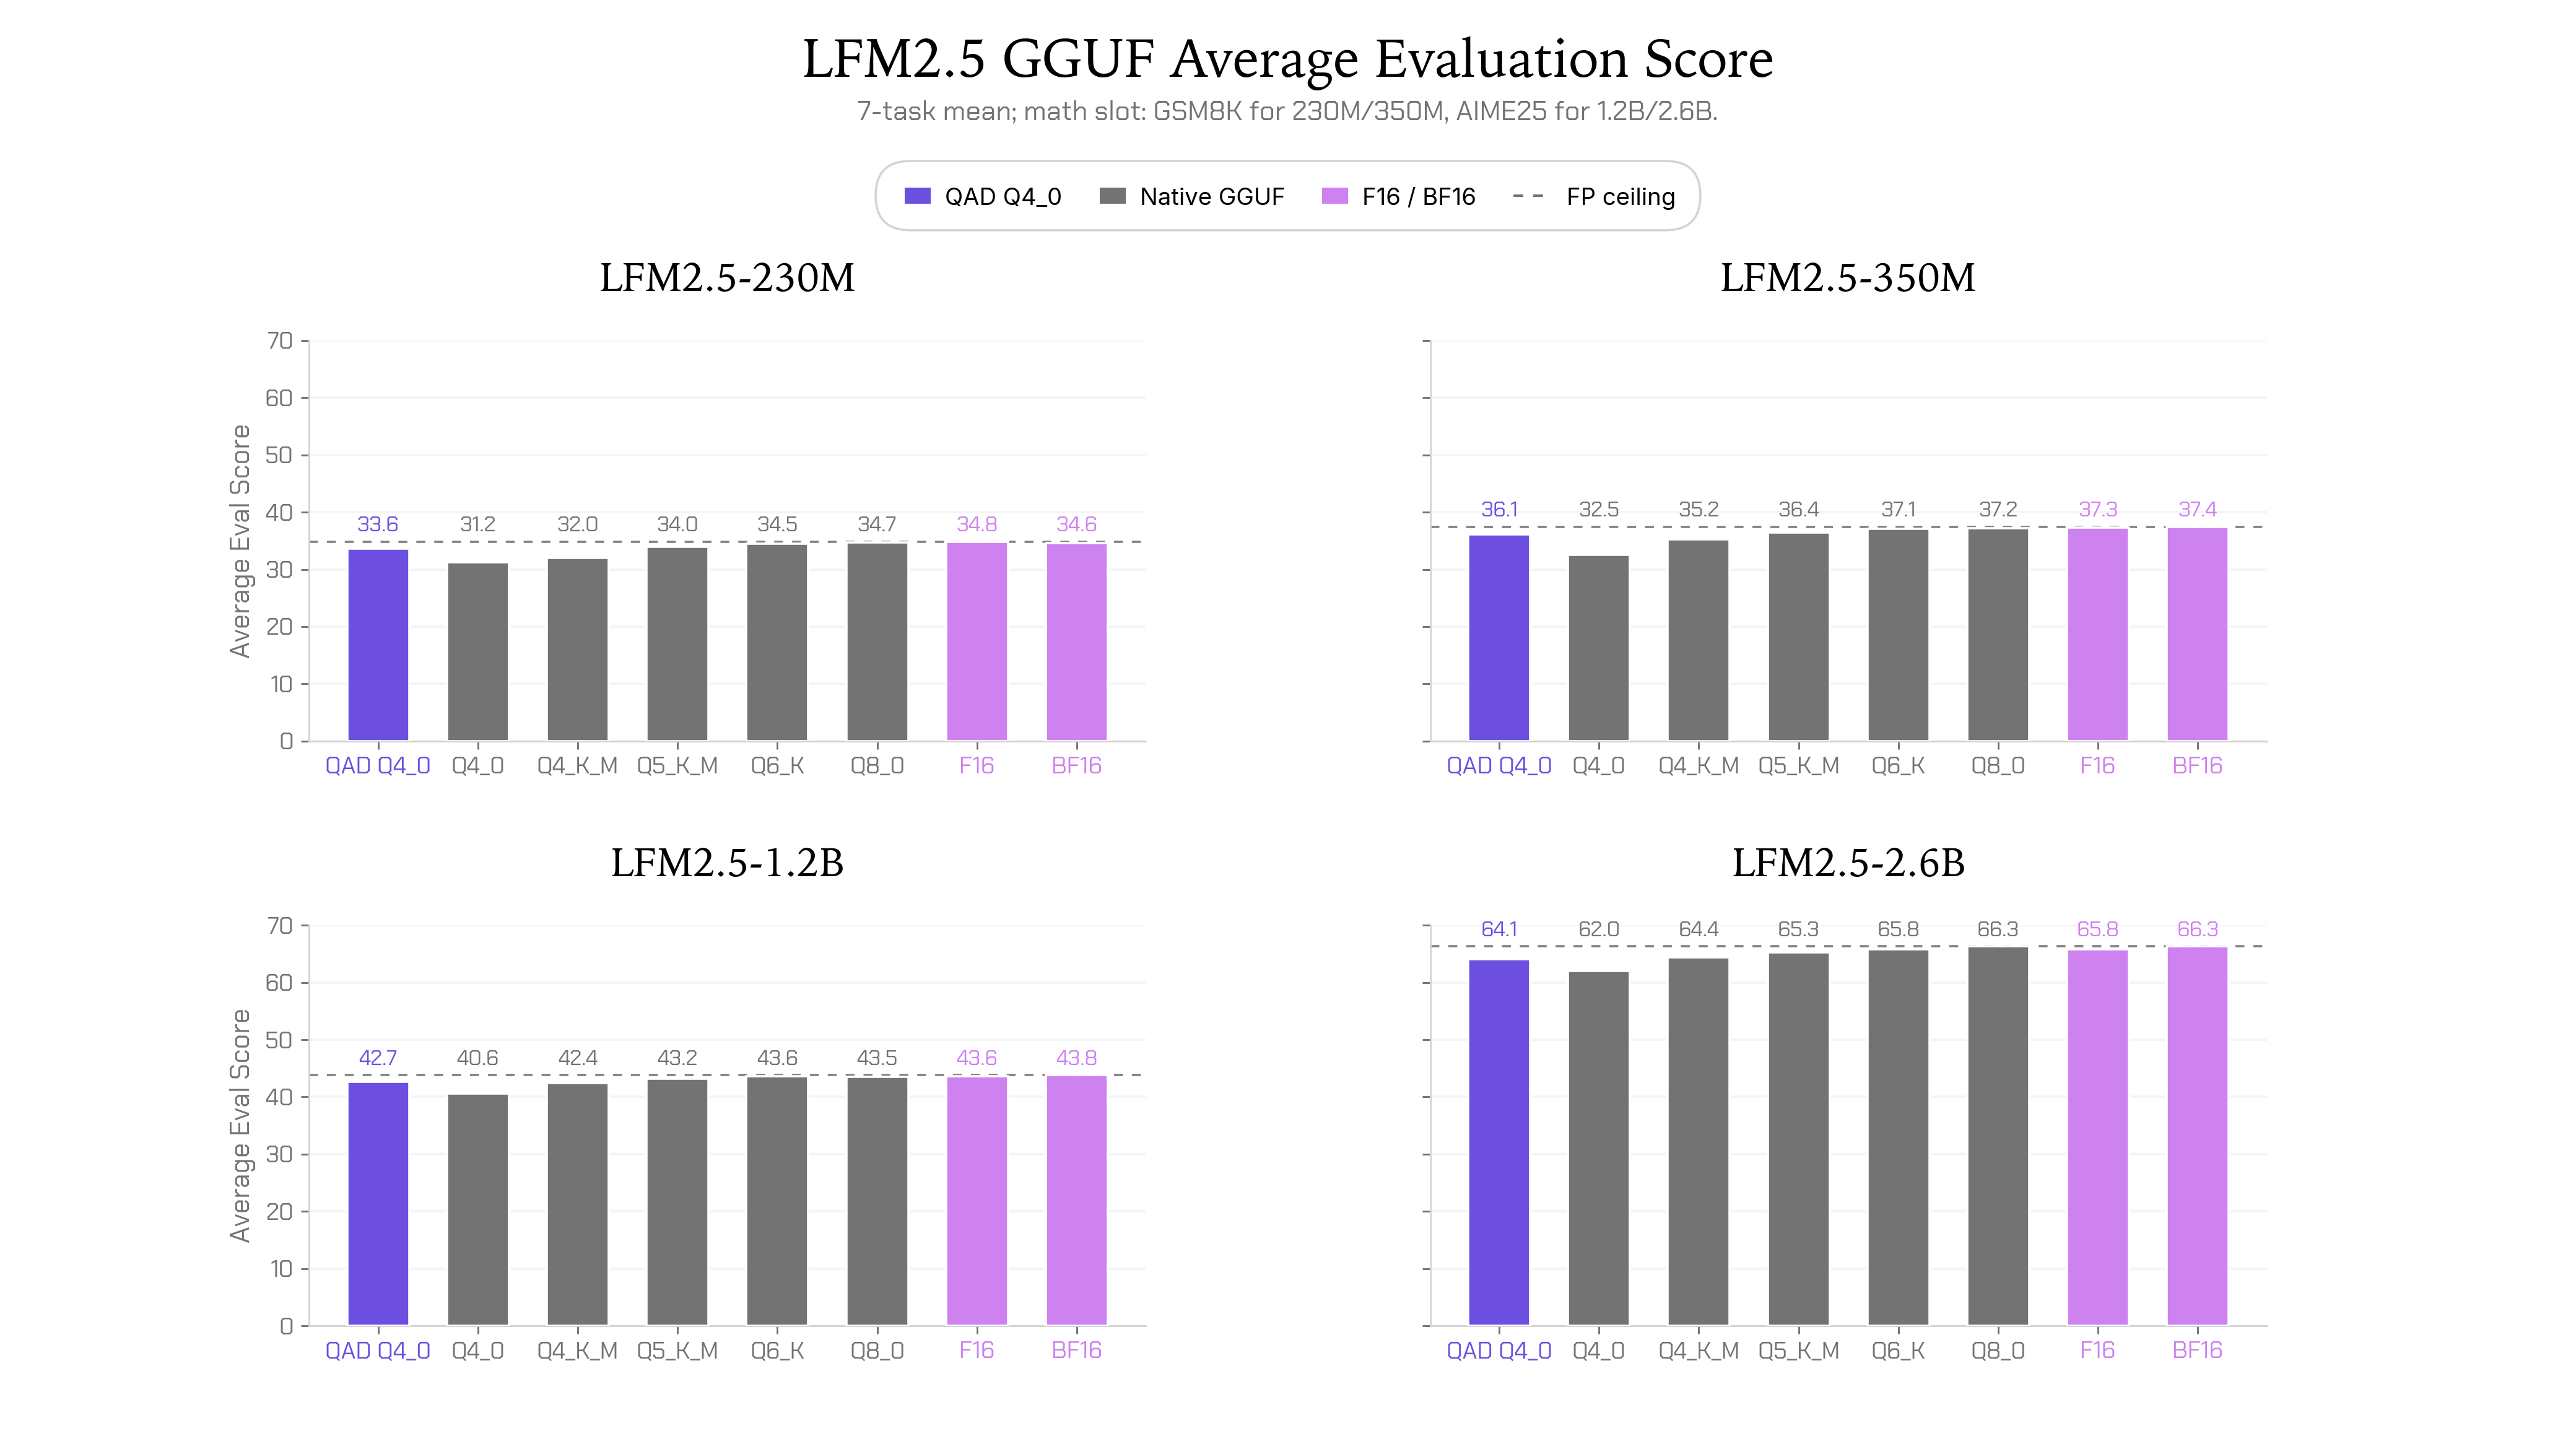
LFM2.5 Q4\_0 Checkpoints from Quantization-Aware Distillation
Source
huggingface.co
Date
Why it matters
quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition →-aware distillationTraining a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.Full definition → gives Q4_0 GGUFs that match Q4_K_M/Q5_K_M quality at 3-33% higher decode throughput and smaller footprint, so edge deployments no longer pay the usual accuracy tax for the fastest quantization format.
Terms in this piece · Glossary
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.