From Pixels to Pairs: A Comprehensive Benchmark of LLM-Based Key-Value Extraction in Noisy Document Settings
- Source
- arxiv.org
- Author
- Zahra Anvari, Vassilis Athitsos
- Date
Context
A tested open-source instruction-tuned LLMs, including Gemma, Mistral, Qwen2.5, LLaMA 3, and DeepSeek, on extracting key-value pairs like form fields and receipt line items from documents, comparing performance on clean gold-standard text against text run through three OCR engines, PaddleOCR, EasyOCR, and Tesseract (arxiv.org). On clean text, the models acted as strong semantic extractors, in some cases approaching specialized layout-aware extraction systems built for the task. Once realistic OCR noise entered the pipeline, however, performance dropped substantially, and the gap between models narrowed as input corruption increased, meaning a bigger model's usual edge mattered less as the input got noisier. The researchers identify two separate factors driving results, how well a model reasons over the text semantically and how much the text's fidelity survives OCR, and they found recurring failure modes including key-value misalignment, hallucinated fields, and corrupted numbers.
- As OCR corruption increases, performance gaps between different models narrow — a larger model's advantage shrinks because OCR quality, not model capability, becomes the dominant bottleneck.
- The paper identifies three recurring failure modes under noisy OCR input specifically: key-value misalignment, , and numeric corruption, rather than a uniform across-the-board accuracy drop.
- Larger models' gains over smaller ones hold on clean text but diminish substantially once OCR noise is introduced, since extraction quality then depends on preserved textual fidelity rather than semantic reasoning capacity alone.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
 articleDo large language models scrutinise what they review? A multimodal audit of scoring calibration, error detection, and author-identity effectsEmad Alharbi
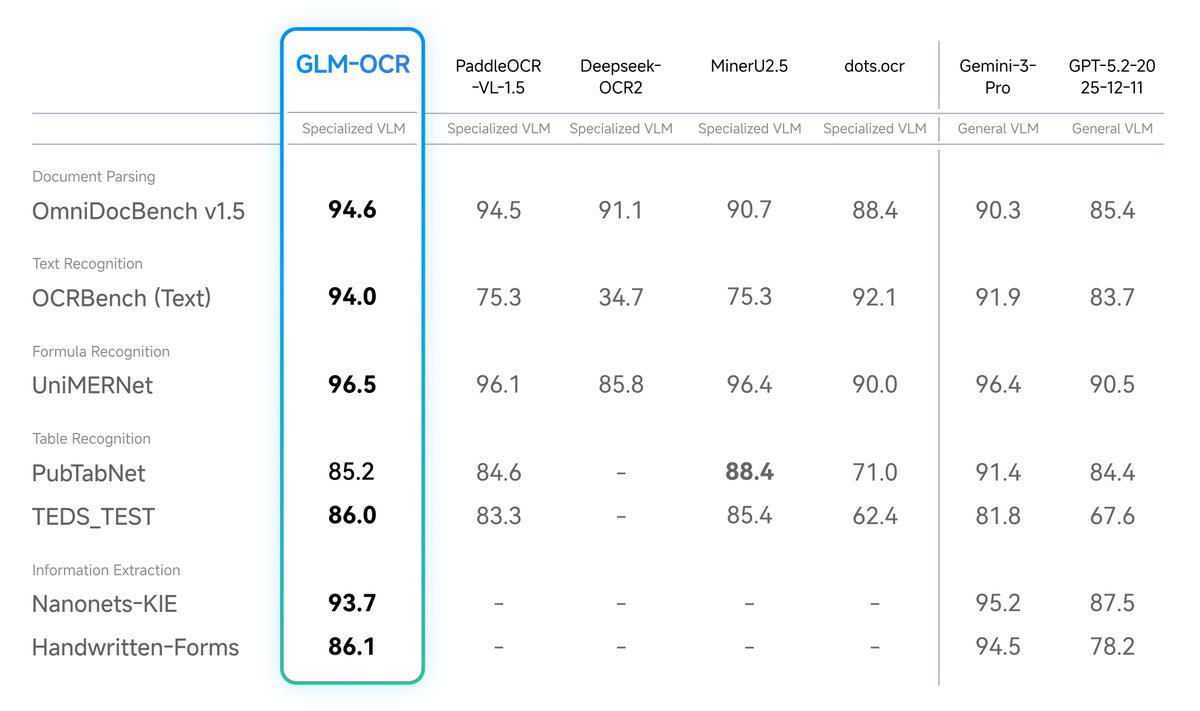 articleGLM-OCR: a 0.9B open model for document parsingZ.ai
 articleGardenBench: A lightweight, daily evaluation of LLM capabilitiesBenedict Cummins-Mburu, Mariana Garcia Mejia, Oscar Heath, Sabrina Kreyzerman, Ellie Murray, Arusan Surendiran, Rohan Alexander
Checking sign-in…
Loading comments…