GLM-OCR puts document parsing into a 0.9B open model
- Source
- x.com
- Date

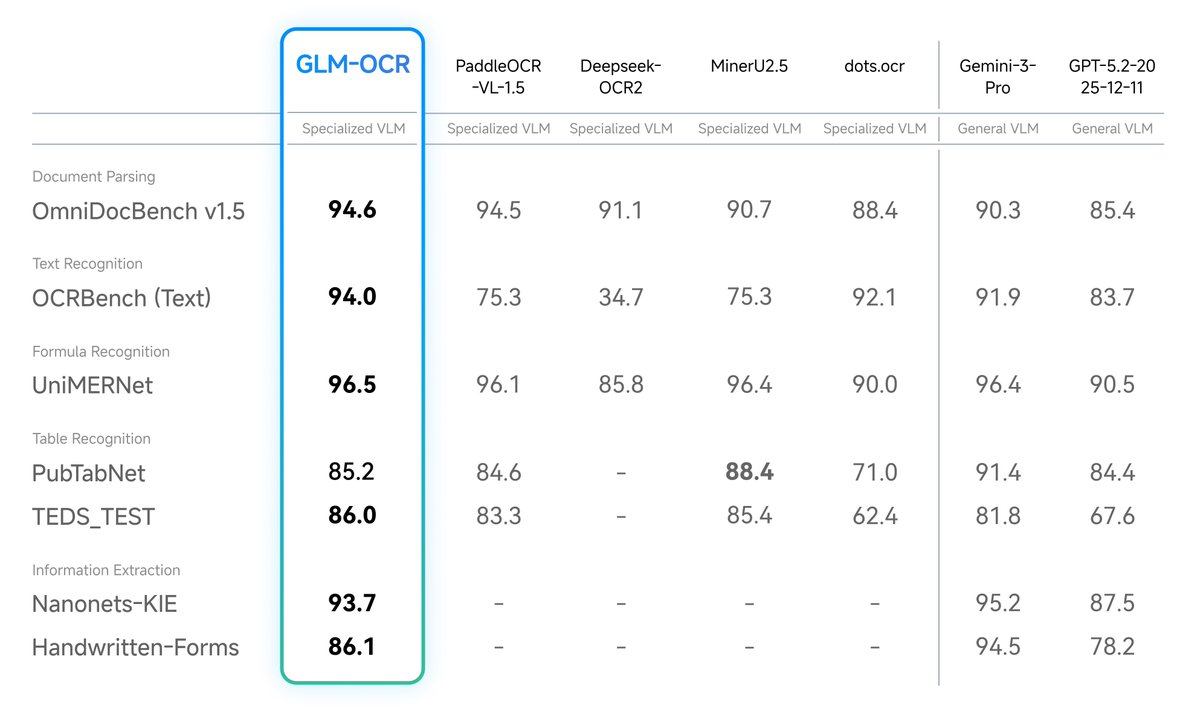
Introducing GLM-OCR: SOTA performance, optimized for complex document understanding. With only 0.9B parameters, GLM-OCR delivers state-of-the-art results across major document understanding benchmarks, including formula recognition, table recognition, and information extraction. Weights: https://t.co/vqIBgBCXYi Try it: https://t.co/Ld7H8Pasls API:
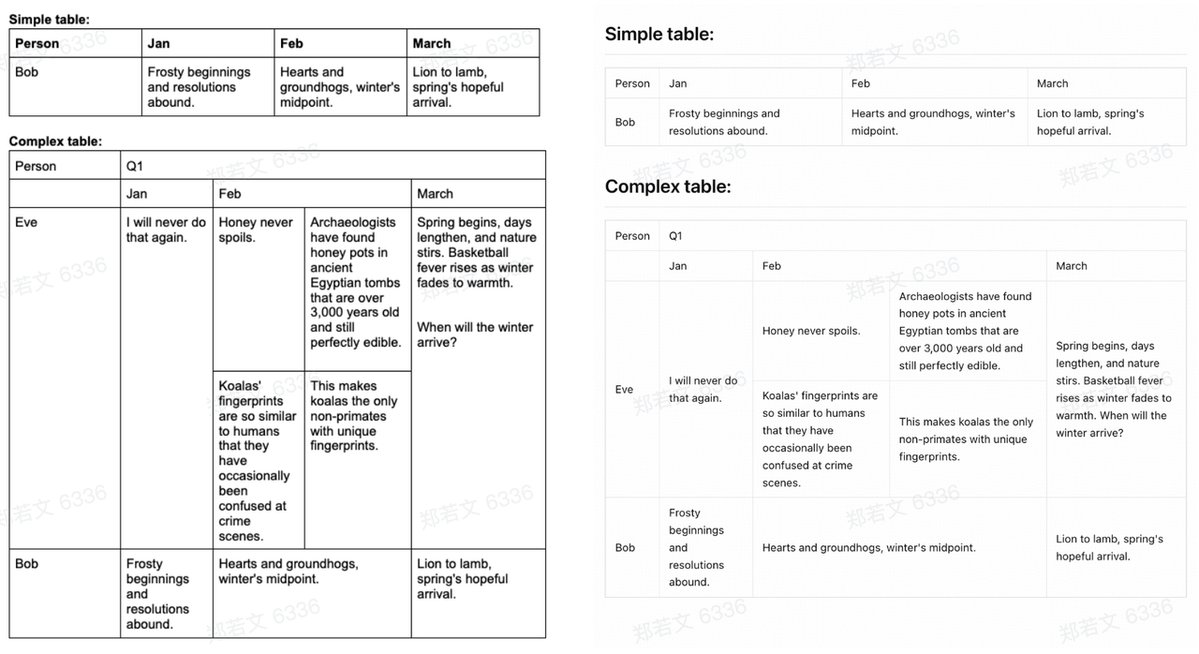
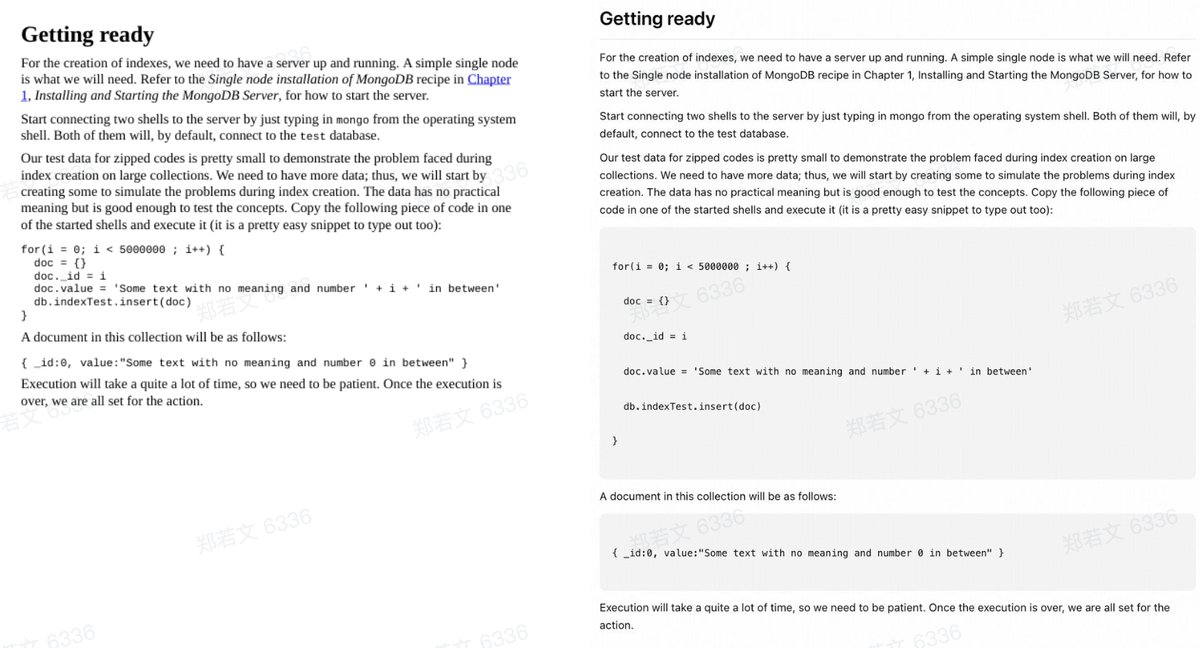
Optimized for real-world scenarios: It handles complex tables, code-heavy docs, official seals, and other challenging elements where traditional OCR fails.
The model integrates the CogViT visual encoder pre-trained on large-scale image–text data, a lightweight cross-modal connector with efficient token downsampling, and a GLM-0.5B language decoder. Combined with a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3, GLM-OCR delivers robust and high-quality OCR performance across diverse document layouts.
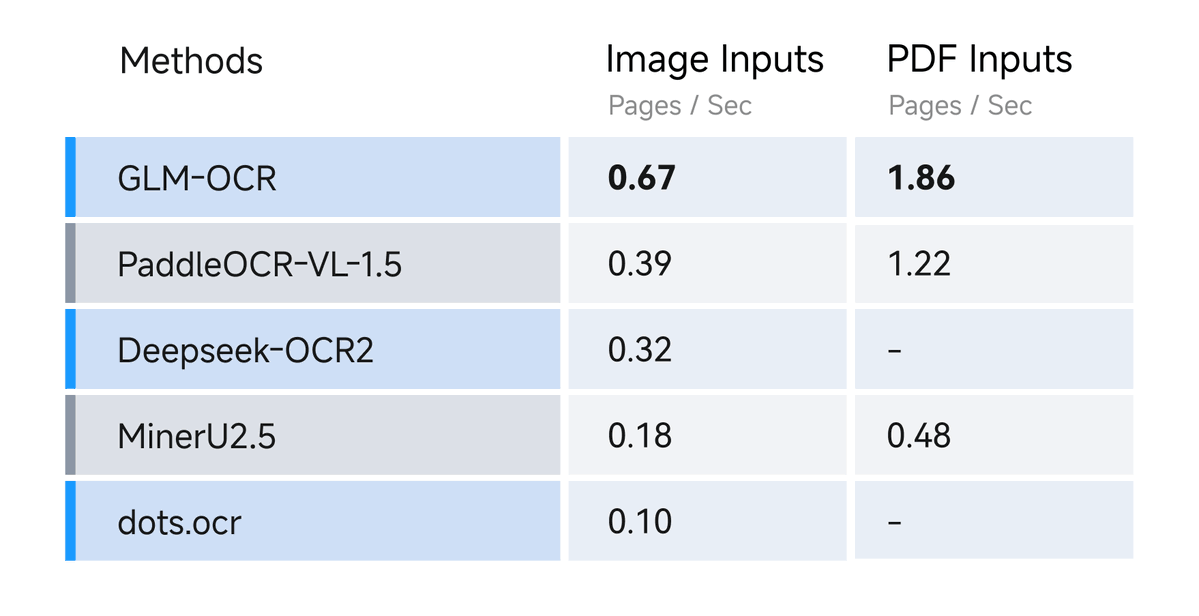
GLM-OCR achieves a throughput of 1.86 pages/second for PDF documents and 0.67 images/second for images, significantly outperforming comparable models.
Context
Z.ai's GLM-OCR turns document images into machine-readable content, including text, formulas, and tables. Its document-processing pipeline has two stages: layout analysis first, then recognition carried out in parallel. The published model has 0.9 billion parameters and downloadable weights under an MIT license. The official model card also distinguishes the complete document-parsing toolkit from using the model directly for structured information extraction, which helps developers choose the appropriate starting point.
 postWe’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
- postGLM-5 lands in Zhipu's Coding Plan Pro as pricing shifts
 articleZ.ai details GLM-5.3's leap in exploit analysis and staged release
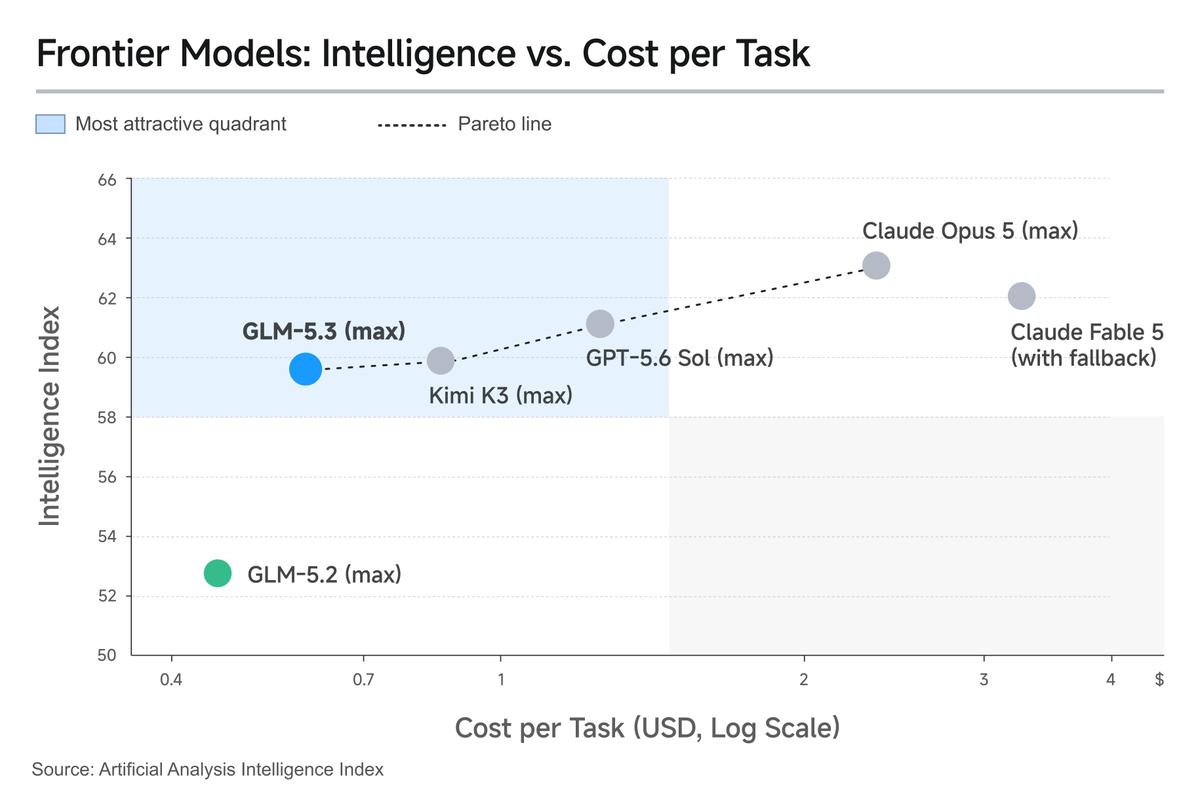 postGLM-5.3 API launches for coding and cybersecurity agentic tasks
Checking sign-in…
Loading comments…