[Paper Club] Upcycling Large Language Models into Mixture of Experts
Source
youtube.com
Author
Latent Space
Date
Context
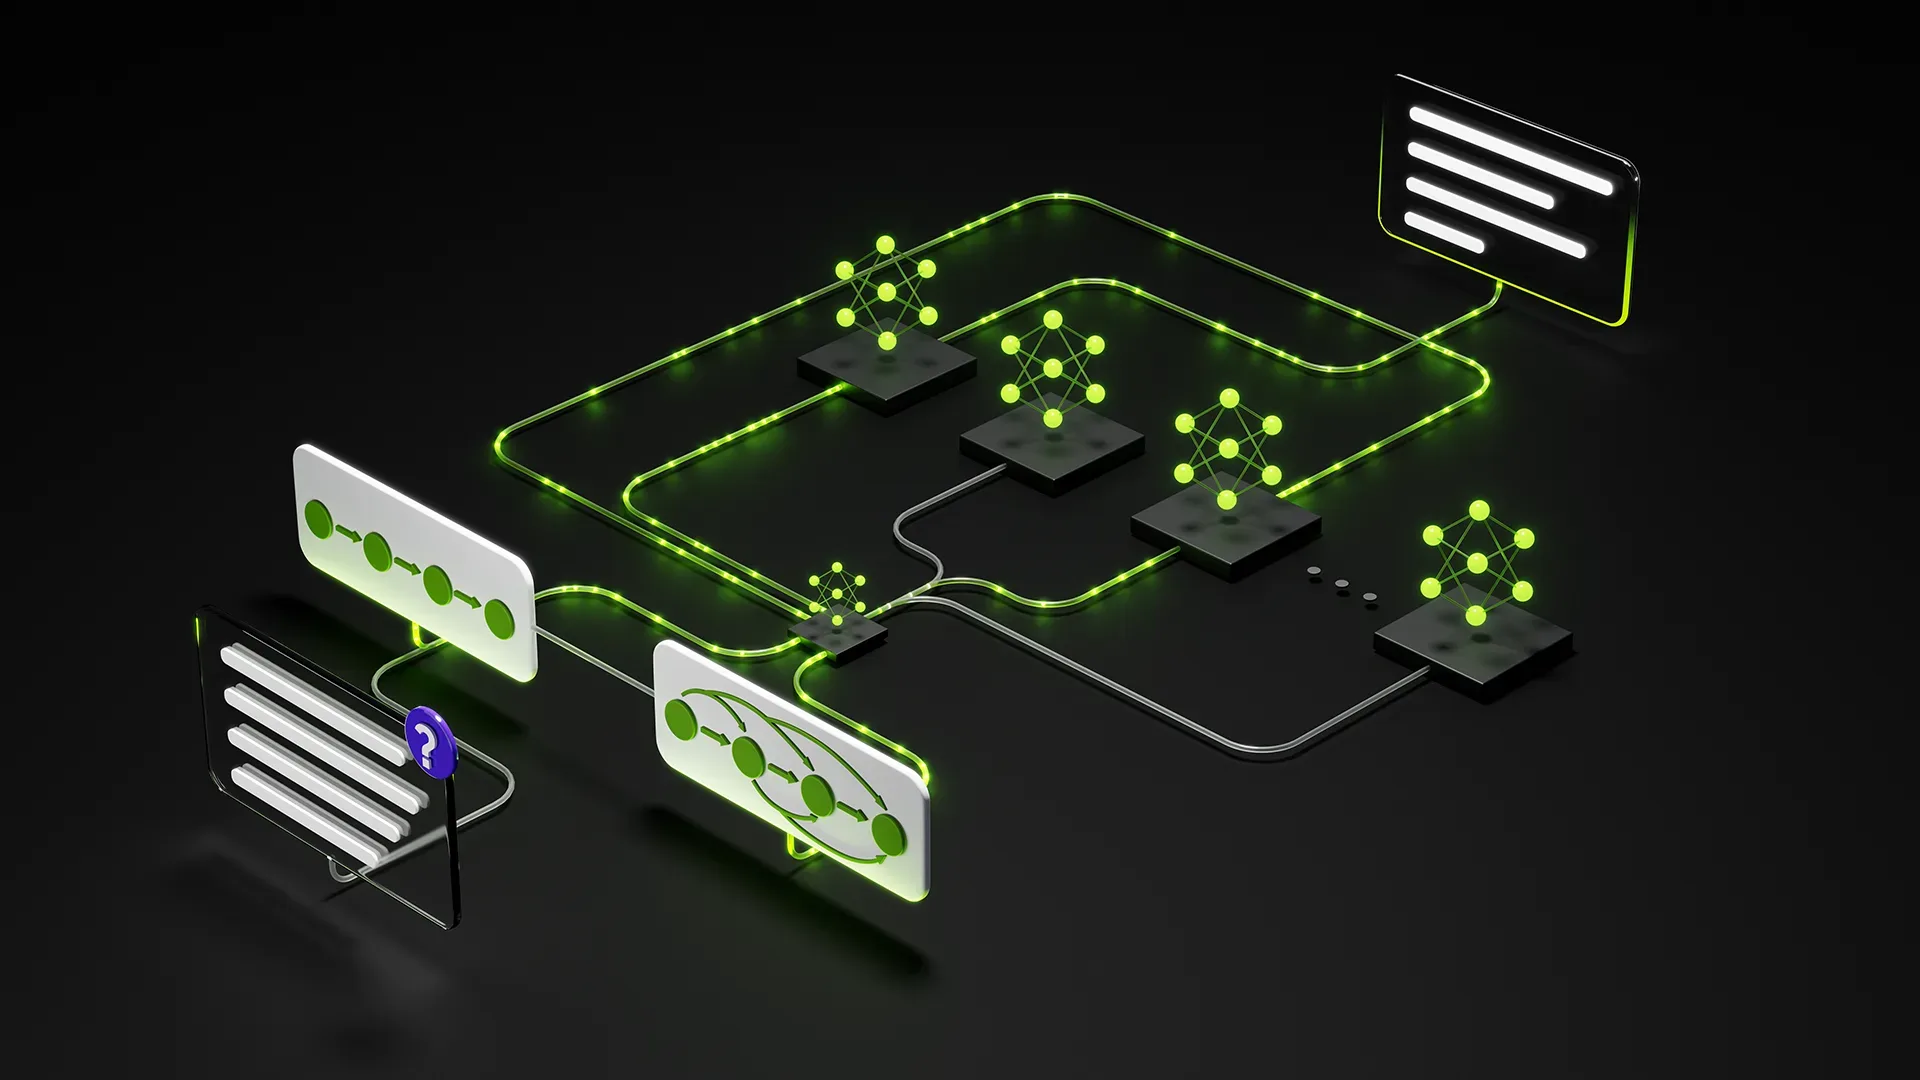
A trained LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → can become the starting point for a larger mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → model. In this research presentation, an NVIDIA researcher explains upcycling: copying parts of an existing network into expert branches, then training a router to select which branches process each piece of text.
Because only some branches activate for each input, the model can add capacity without activating every added parameter. The researchers report that their upcycling experiments outperformed continued training of the original dense models. Initialization is central to their method: the conversion must preserve useful behavior closely enough for further training to build on it.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
 videoWorld Models & General Intuition: Khosla's largest bet since LLMs & OpenAI
 videoExtreme Harness Engineering: 1M LOC, 1B toks/day, 0% human code or review — Ryan Lopopolo, OpenAI
 videoInside Abridge: The AI Listening to 100 Million Doctor Visits — Abridge's Janie Lee & Chai Asawa
 videoExo: Harnesses should see their own code and logs — Alex Krentsel, UC Berekeley / Google Research