Long context windows do not fix LLM reranking
- Source
- x.com
- Date

⚖️Purpose-built rerankers such as rerank-2.5 >>> LLMs - Up to 60x cheaper & 48x faster than SOTA LLMs - Beat LLM rerankers by up to 15% in accuracy (NDCG@10) - Strong first-stage retrieval + specialized reranker = best reranking quality

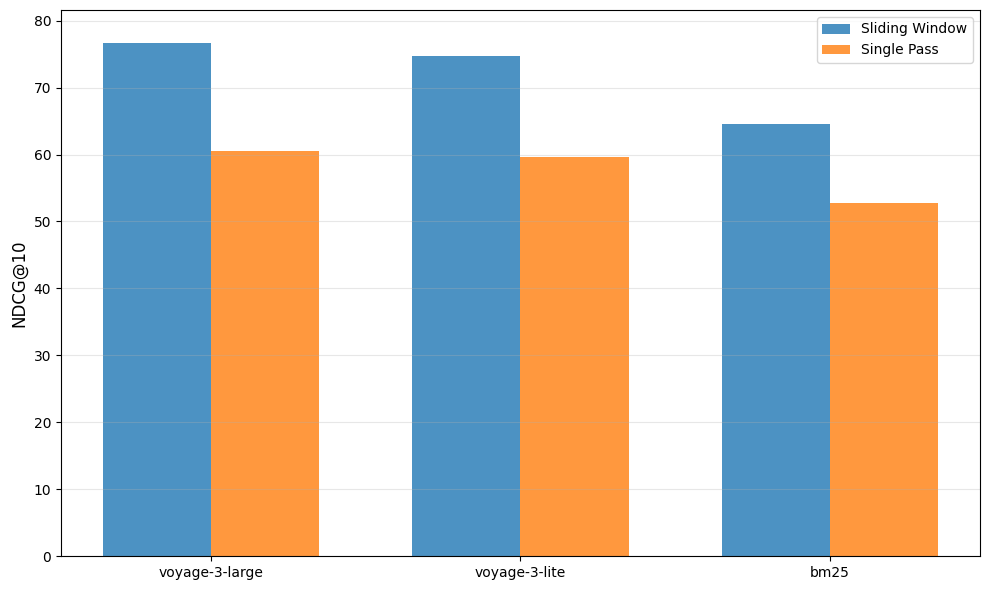
❌ Long context windows don't help LLM rerankers. Single-pass reranking significantly underperforms sliding window reranking, undermining the value of longer context windows for reranking.
💰rerank-2.5 costs $0.05 per 1M tokens vs. $1.25-$3 for LLMs such as Gemini 2.5 Pro, GPT-5, and Claude Sonnet 4.5.

⚡rerank-2.5 offers the best reranking performance, while being 9x, 36x, and 48x faster than Claude Sonnet 4.5, GPT-5, and Gemini 2.5 Pro, respectively.

Context
Being able to read every candidate document at once did not produce the best search ranking in Voyage AI's October 2025 experiment. The company compared Gemini 2.0 Flash ranking 100 documents in one pass with ranking them through successive windows of 20 documents.
The windowed approach scored better across all three initial retrieval methods on NDCG@10, which measures how well relevant documents appear near the top of the first ten results. The supported conclusion is specific: for this model and test setup, using its large input capacity in one pass produced worse rankings than processing smaller groups.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- reranking — A second pass that re-scores retrieved candidates by reading each one against the query, fixing the ordering that fast vector search got approximately right.
Checking sign-in…
Loading comments…