SlopCodeBench 10/2026 – Opus 5.5, Astra wins overall, xhigh considered harmful
- Source
- github.com
- Author
- dhorthy
- Date
Context
Dex Horthy's October run of SlopCodeBench finds that frontier coding agents have improved only slightly at keeping a codebase working as its requirements change. The best strict pass rate, from OpenAI's GPT-6 Astra at XHigh effort, was 16.3%, against the 14.8% that gpt-5.5 scored when the was last published in May (full write-up). His own summary is that models are getting better at maintaining code over time, but not as fast as claims suggest.
SlopCodeBench gives an a problem in stages. It writes a program, then receives new requirements it did not know in advance and has to change its own existing code, and each later checkpoint tests both the new behavior and the old. A checkpoint counts as a strict pass only if every test category passes, including regression tests for earlier behavior. The looser core rate only asks that the current checkpoint's core tests pass. That gap is the main finding: the ten campaigns scored 65.8% to 74.0% on core but 12.2% to 16.3% on strict, so the agents got the main behavior right far more often than they kept all tested behavior working. This run covered the full benchmark, 36 problems and 196 checkpoints per setting, which is why Horthy says his earlier subset results, including a 30% Fable 5 score on six problems, cannot be compared with it.
The title's claim that XHigh is harmful is hedged in the post itself. XHigh effort cost an estimated 2.11 to 4.22 times as much as medium effort in the three model pairs tested, yet strict passes rose only for Astra, from 29 to 32. Anthropic's Opus 5.5 fell from 28 to 25, and GPT-6 SOL from 30 to 26. Horthy writes that this does not prove more reasoning hurts coding, only that higher effort was not a reliable way to buy strict passes in these runs, since each setting ran once and run-to-run variation is unmeasured. Margins at the top are similarly thin: Astra XHigh led the next campaign, GPT-6 SOL at medium effort, by two checkpoints, while GPT-6.1 SOL Medium matched Astra Medium's 29 strict passes at the lowest recorded cost, $178.51 against Astra XHigh's $758.62.
The code-quality measurements, which count how much of the leftover code triggers at least one of the benchmark's slop checks, are described as blurry, and they cover only the 28 of the 36 problems the scanner could fully measure. Opus 5.5 at XHigh had the lowest flagged share, 77.75%, against 94.25% for Opus 5.5 at medium, even though the XHigh run had fewer strict passes. Horthy suggests newer models may produce maintainability problems the existing linters were not built to catch, and says a more qualitative analysis from contributor Gabe Orlanski and the SlopCodeBench team will follow. An earlier essay on measuring code sloppiness discusses this kind of measurement.
 articleLoopsBench: From Harness Engineering to Loop Engineering in Benchmarking Coding AgentHan Li, Zhemin Fang, Rili Feng, Yingqi Zhao, Jiaheng Liu, Pengfei Gao, He Ye, Dayi Lin, Qingwei Lin, Saravan Rajmohan, Dongmei Zhang
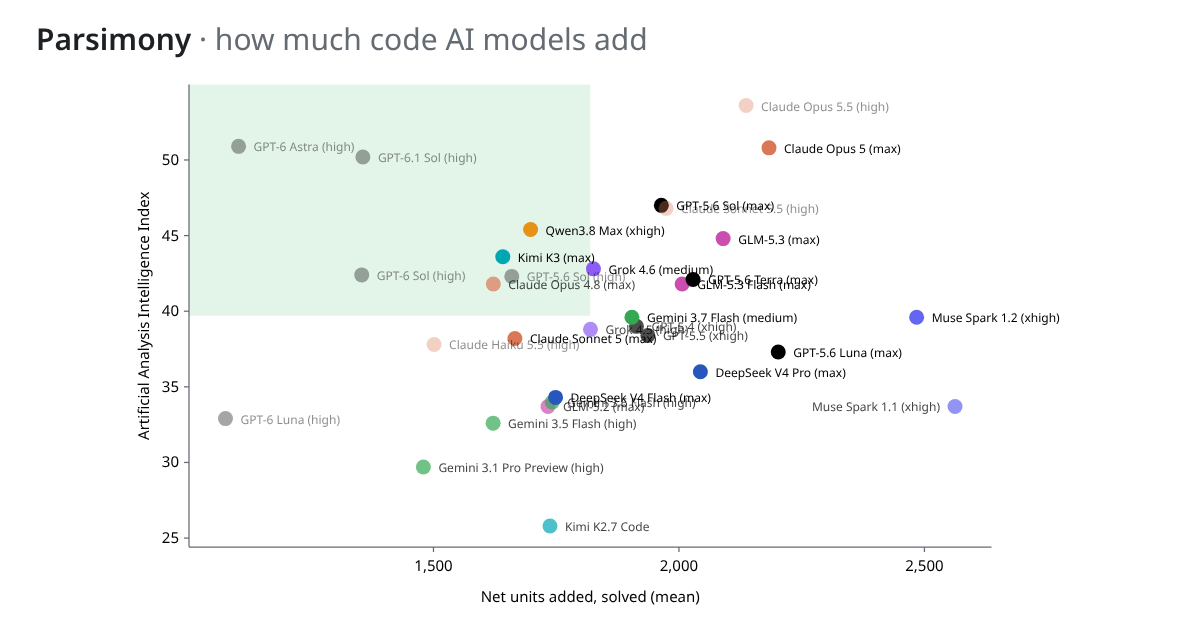 articleParsimony – an open-source benchmark for how much code AI models addlasu
 articleBenchmark: AI doesn't find bugs unless you tell it what's wronglieret
Checking sign-in…
Loading comments…