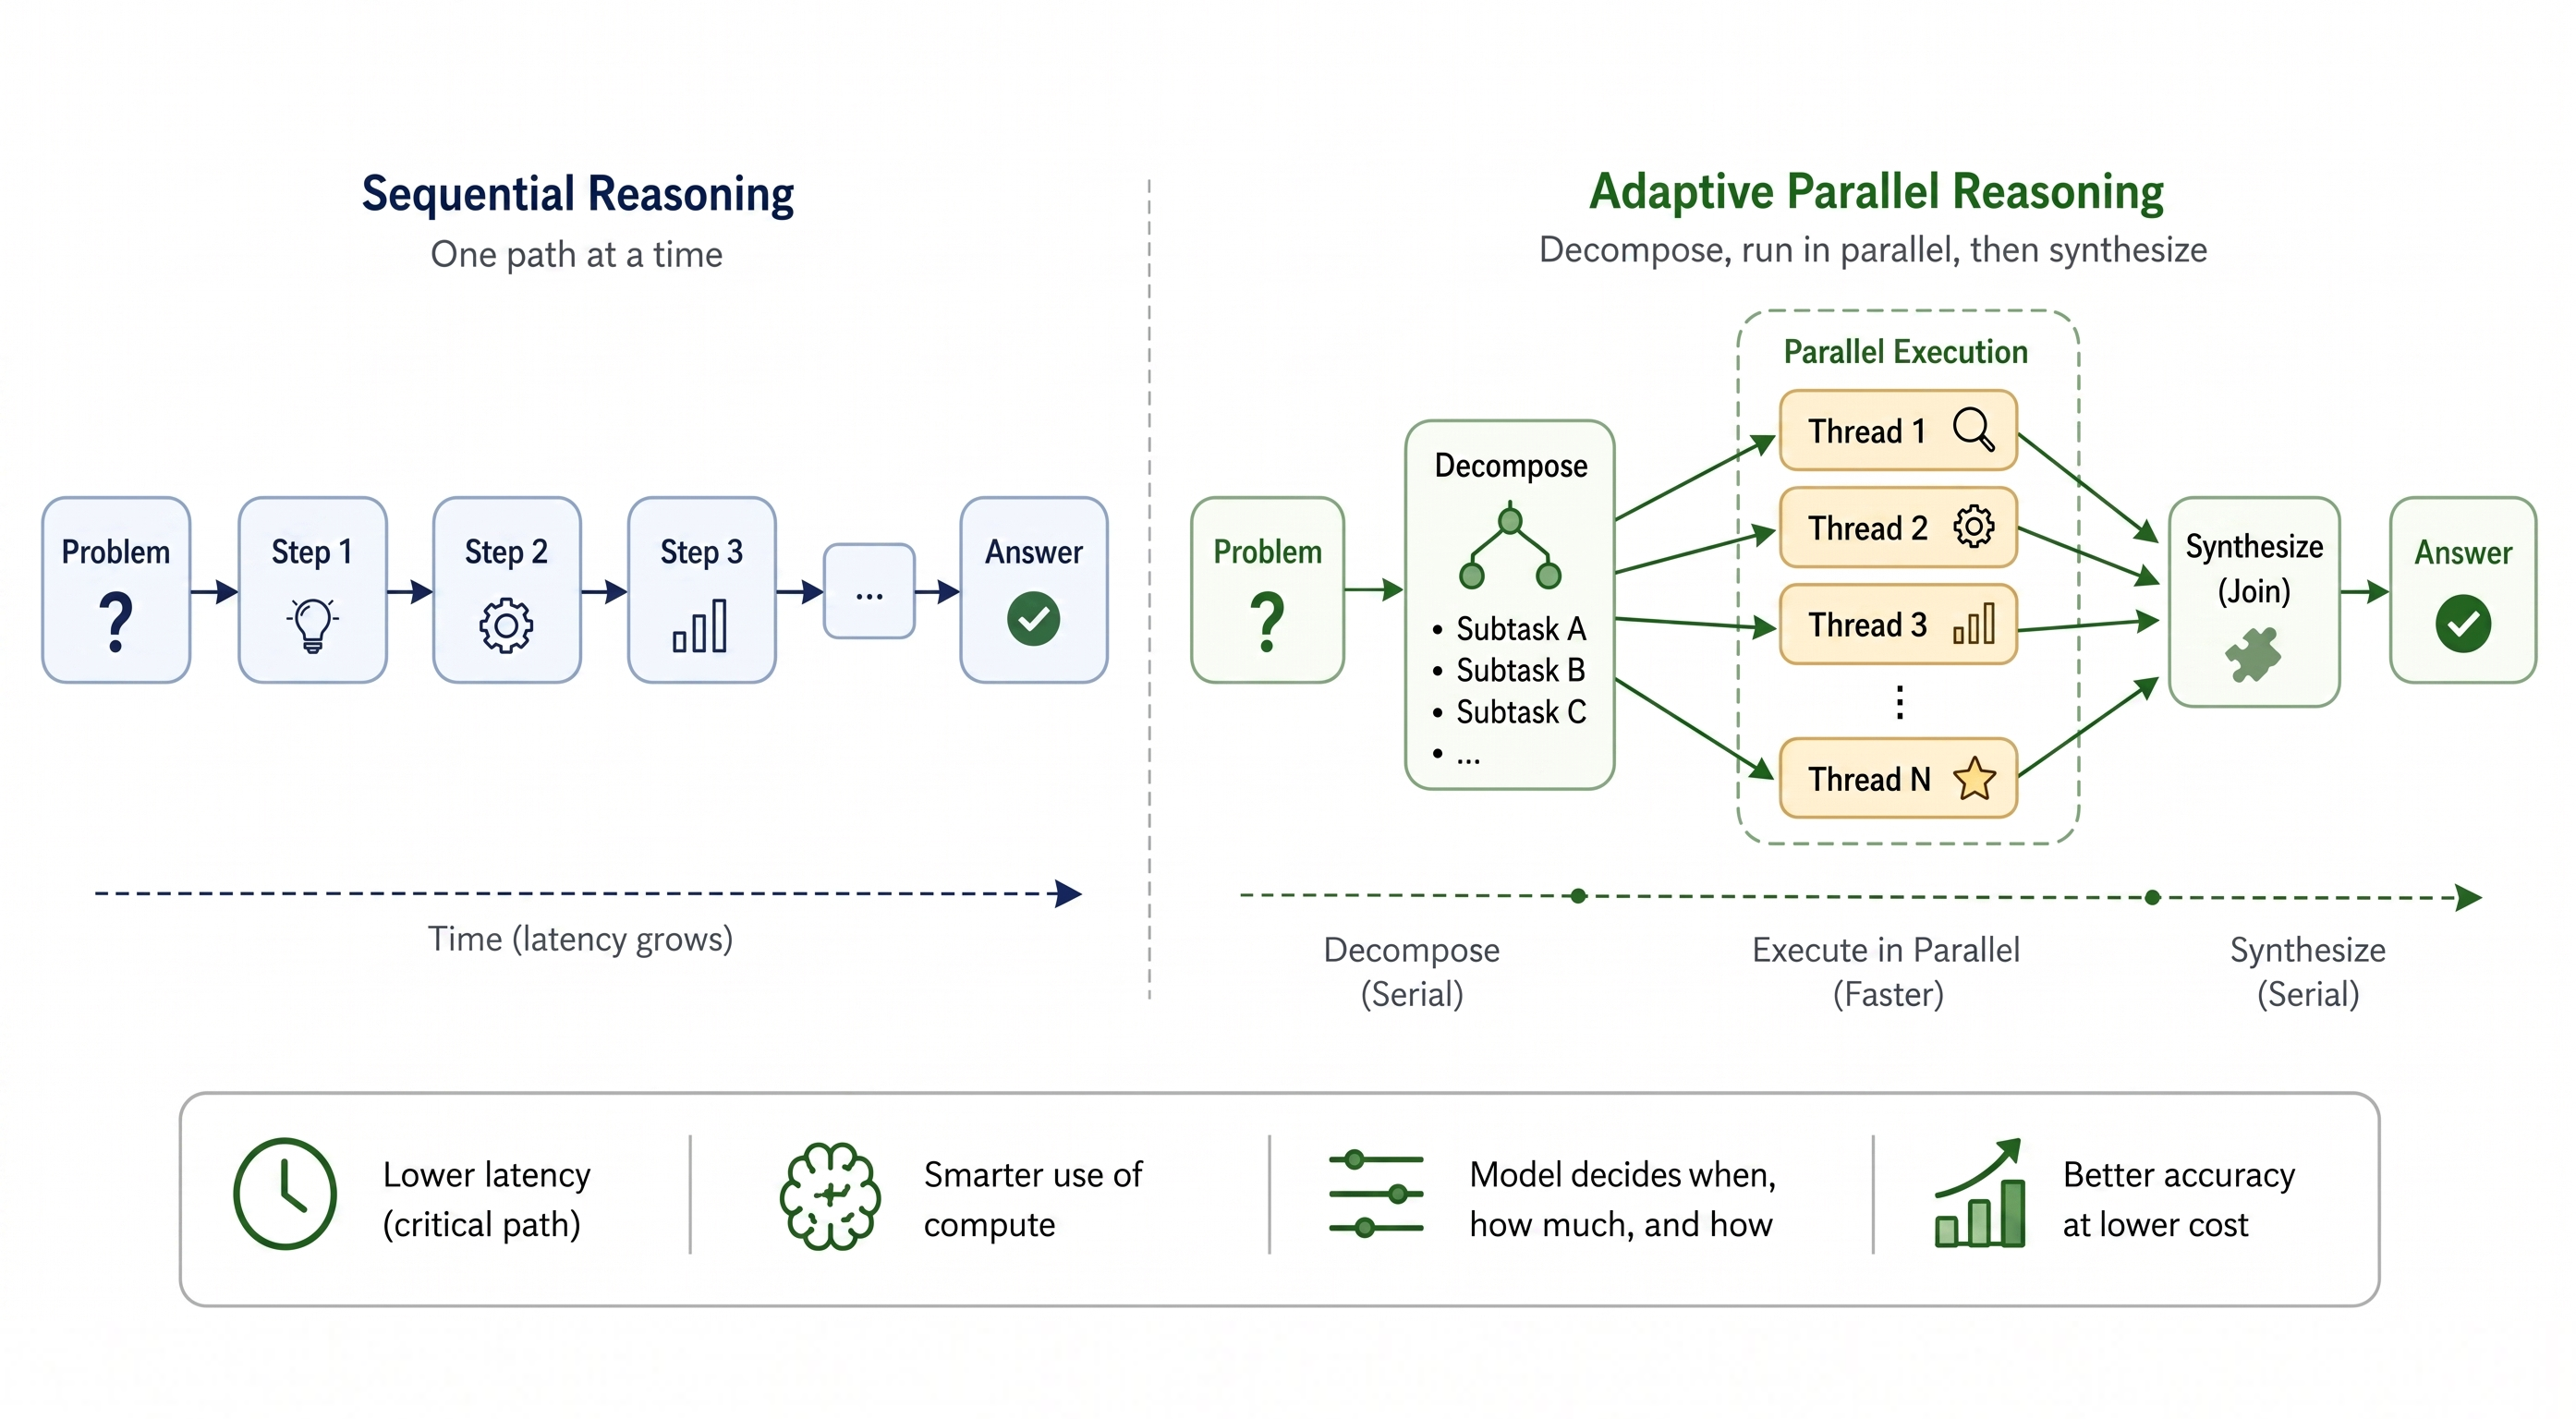
We love scaling inference compute, but it’s costly! Independently sampling parallel attempts might be the culprit: it wastes compute rediscovering the same solutions. What if we scaled inference compute with correlated samples?
Check out QuasiMoTTo by @michaelyli_ and @probablynotaz9!
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Why it matters
Offers a concrete way to cut the compute cost of test-time scaling (parallel sampling), a technique widely used to boost accuracy in reasoning and coding agents.