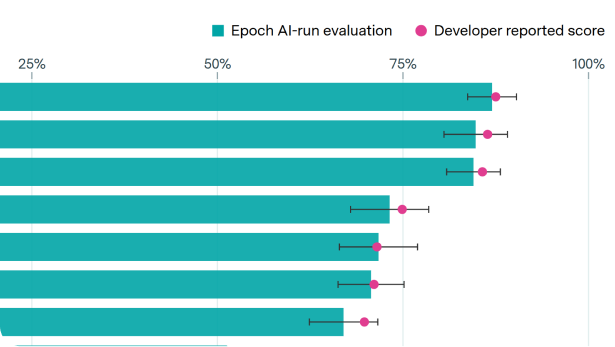
Supports trusting recent lab-reported GPQA Diamond numbers, since they fell within Epoch's confidence intervals for GPT-5, Opus 4.1, Grok 4 and others.
Key takeaways · AI-distilled
The largest gap in Epoch's table is Llama 4 Maverick, self-reported at 69.8% versus 67.0% in Epoch's runs, a z-statistic of 1.00 and p-value of 0.32, still not statistically significant.
DeepSeek R1 showed nearly no gap, reporting 71.5% against Epoch's 71.7%, while GPT-5 reported 85.7% against 84.5% and Grok 4 reported 87.5% against 87.0%.
Epoch runs each question multiple times and aggregates results to handle sampling randomness, and estimates true model performance to within roughly 4 to 6 percentage points at 90% confidence.
Mistral had no self-reported GPQA Diamond score, so Epoch compared against an Artificial Analysis run that Mistral's benchmarks page endorses; that figure (48.6%) was below Epoch's own 51.3%.
Epoch compared Opus 4.1 in its no-extended-thinking configuration, where Anthropic reported 74.9% on GPQA Diamond against 73.2% in Epoch's own runs.