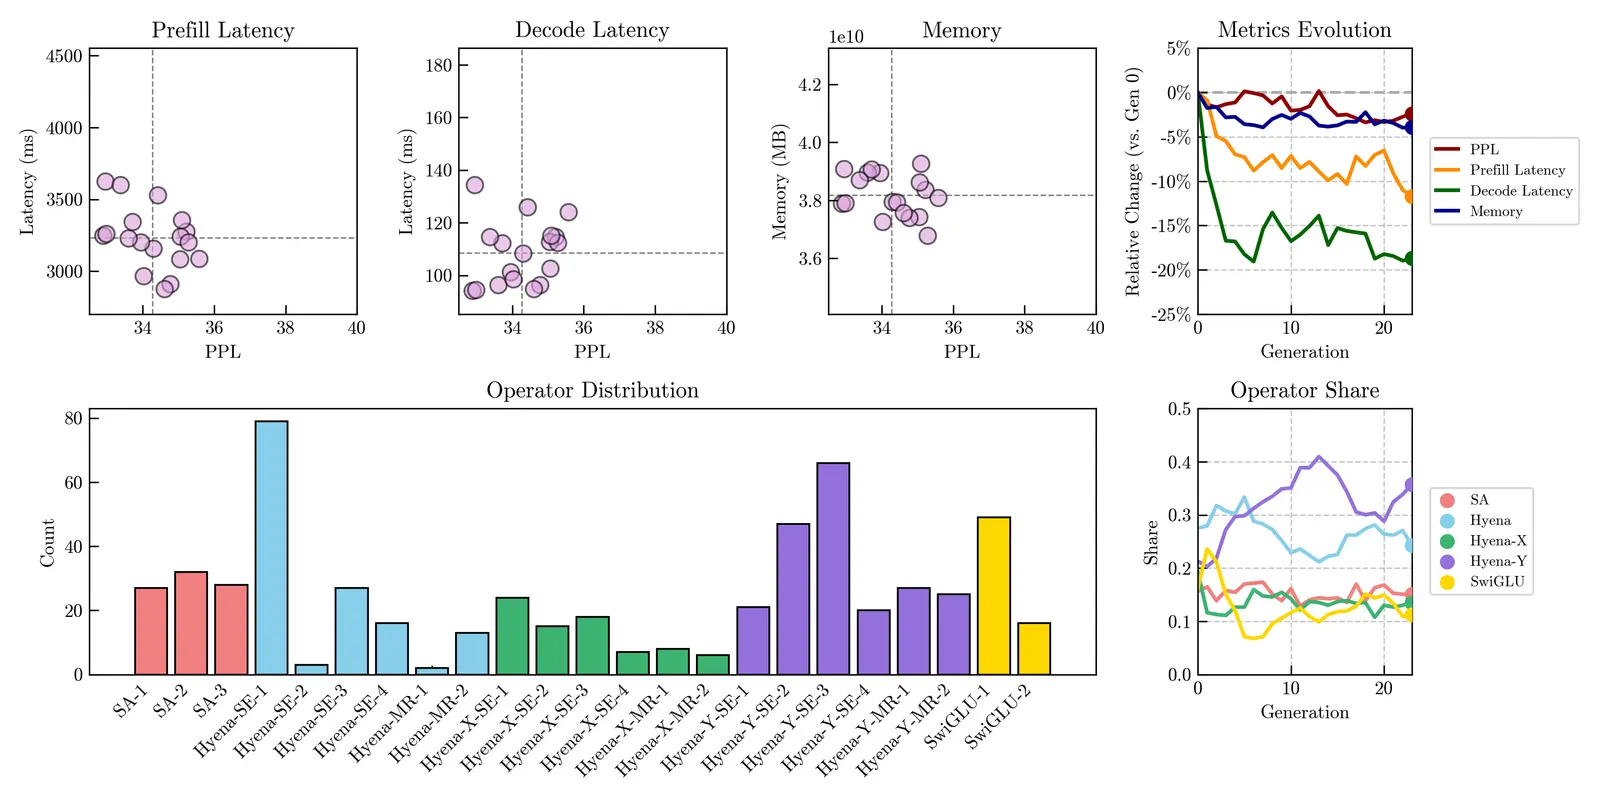
Liquid AI designed Hyena Edge around the hardware it would run on. Its architecture search used measurements from a Samsung S24 Ultra phone to weigh response speed and memory use alongside language-model quality. The resulting model replaced two-thirds of a comparison transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition →’s attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → operations with gated convolutions, an alternative way to process the text sequence. In reported tests, both models had matched parameter counts and trained on the same amount of text. Hyena Edge used less memory across tested sequence lengths and generated text faster for sequences longer than 256 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →. The result supports designing models around a target device; it does not establish the same advantage on every phone.
Terms in this piece · Glossary
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
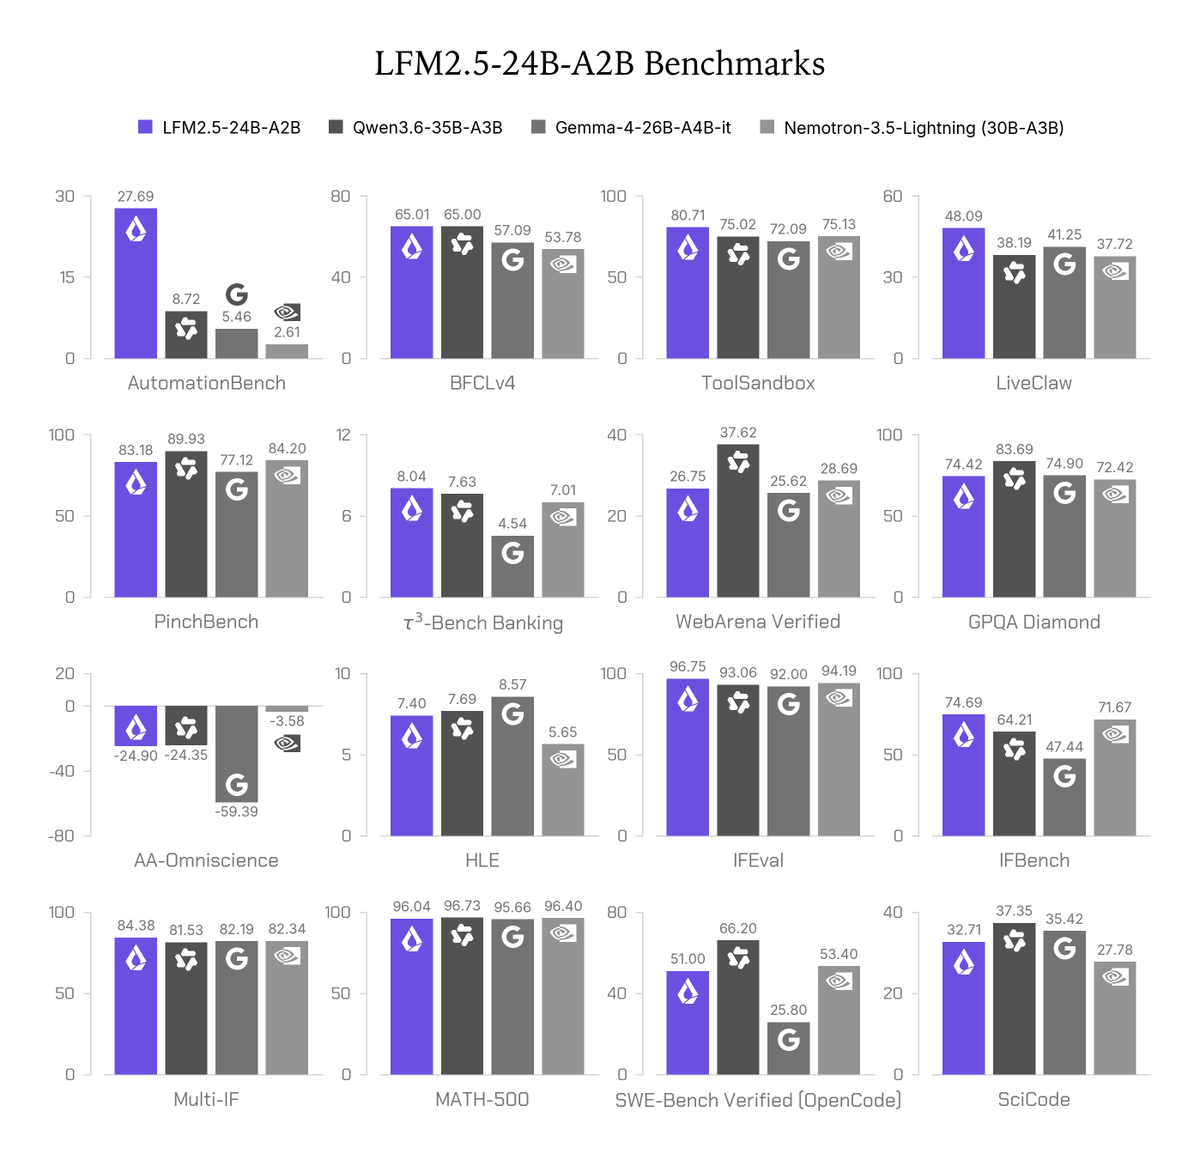 postLiquid AI ships LFM2.5-24B-A2B open weights for local agents
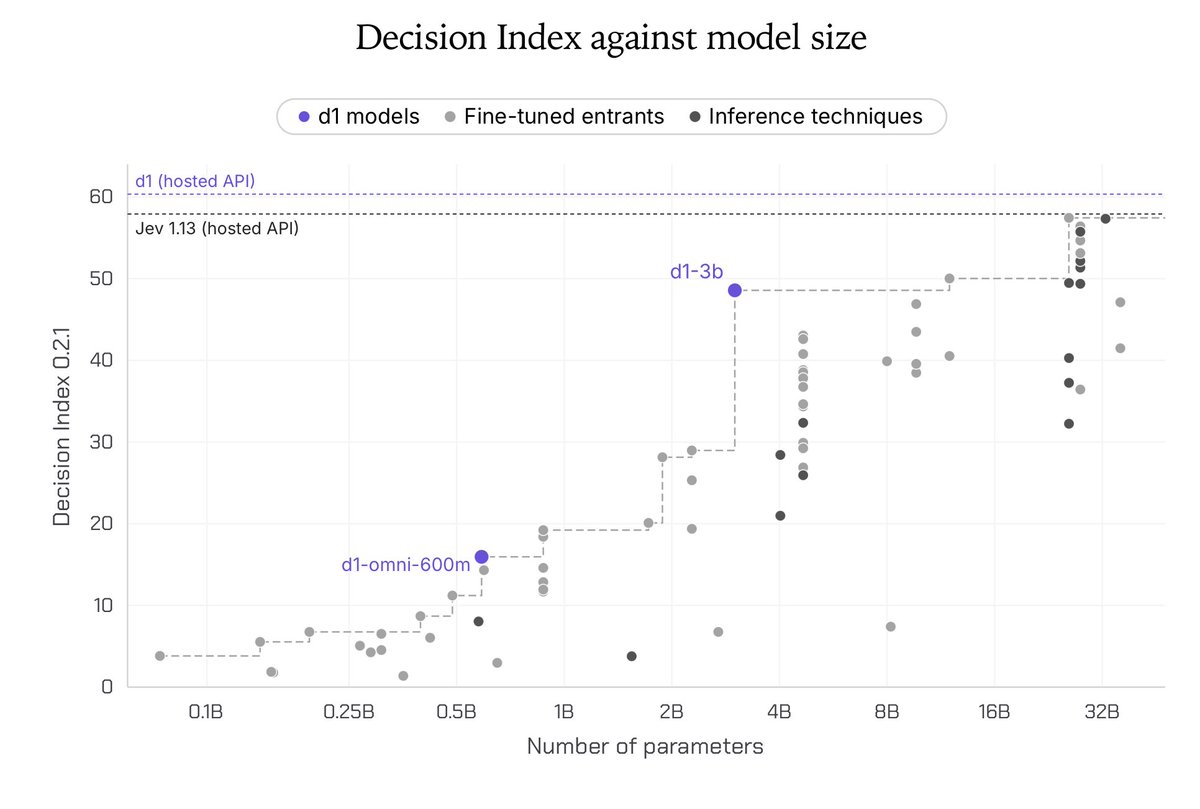 postToday we release Open d1: two open-weight multimodal models in our d1 decision…
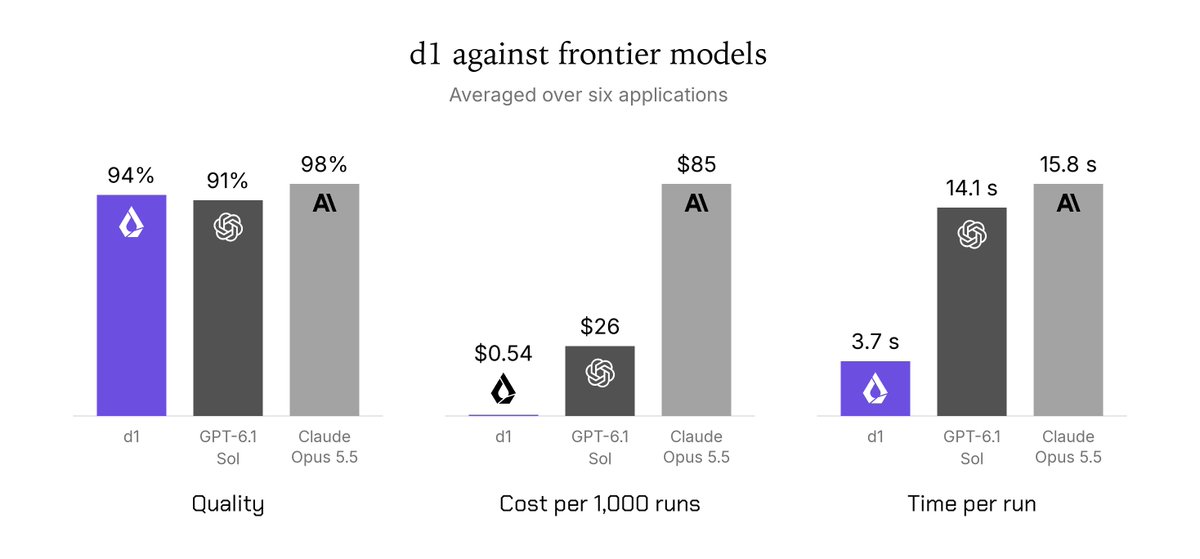 postLiquid AI's d1 decision model adds vision at a fraction of frontier cost
 articled1 is now available on @vercel AI gateway!We worked with the amazing vercel…