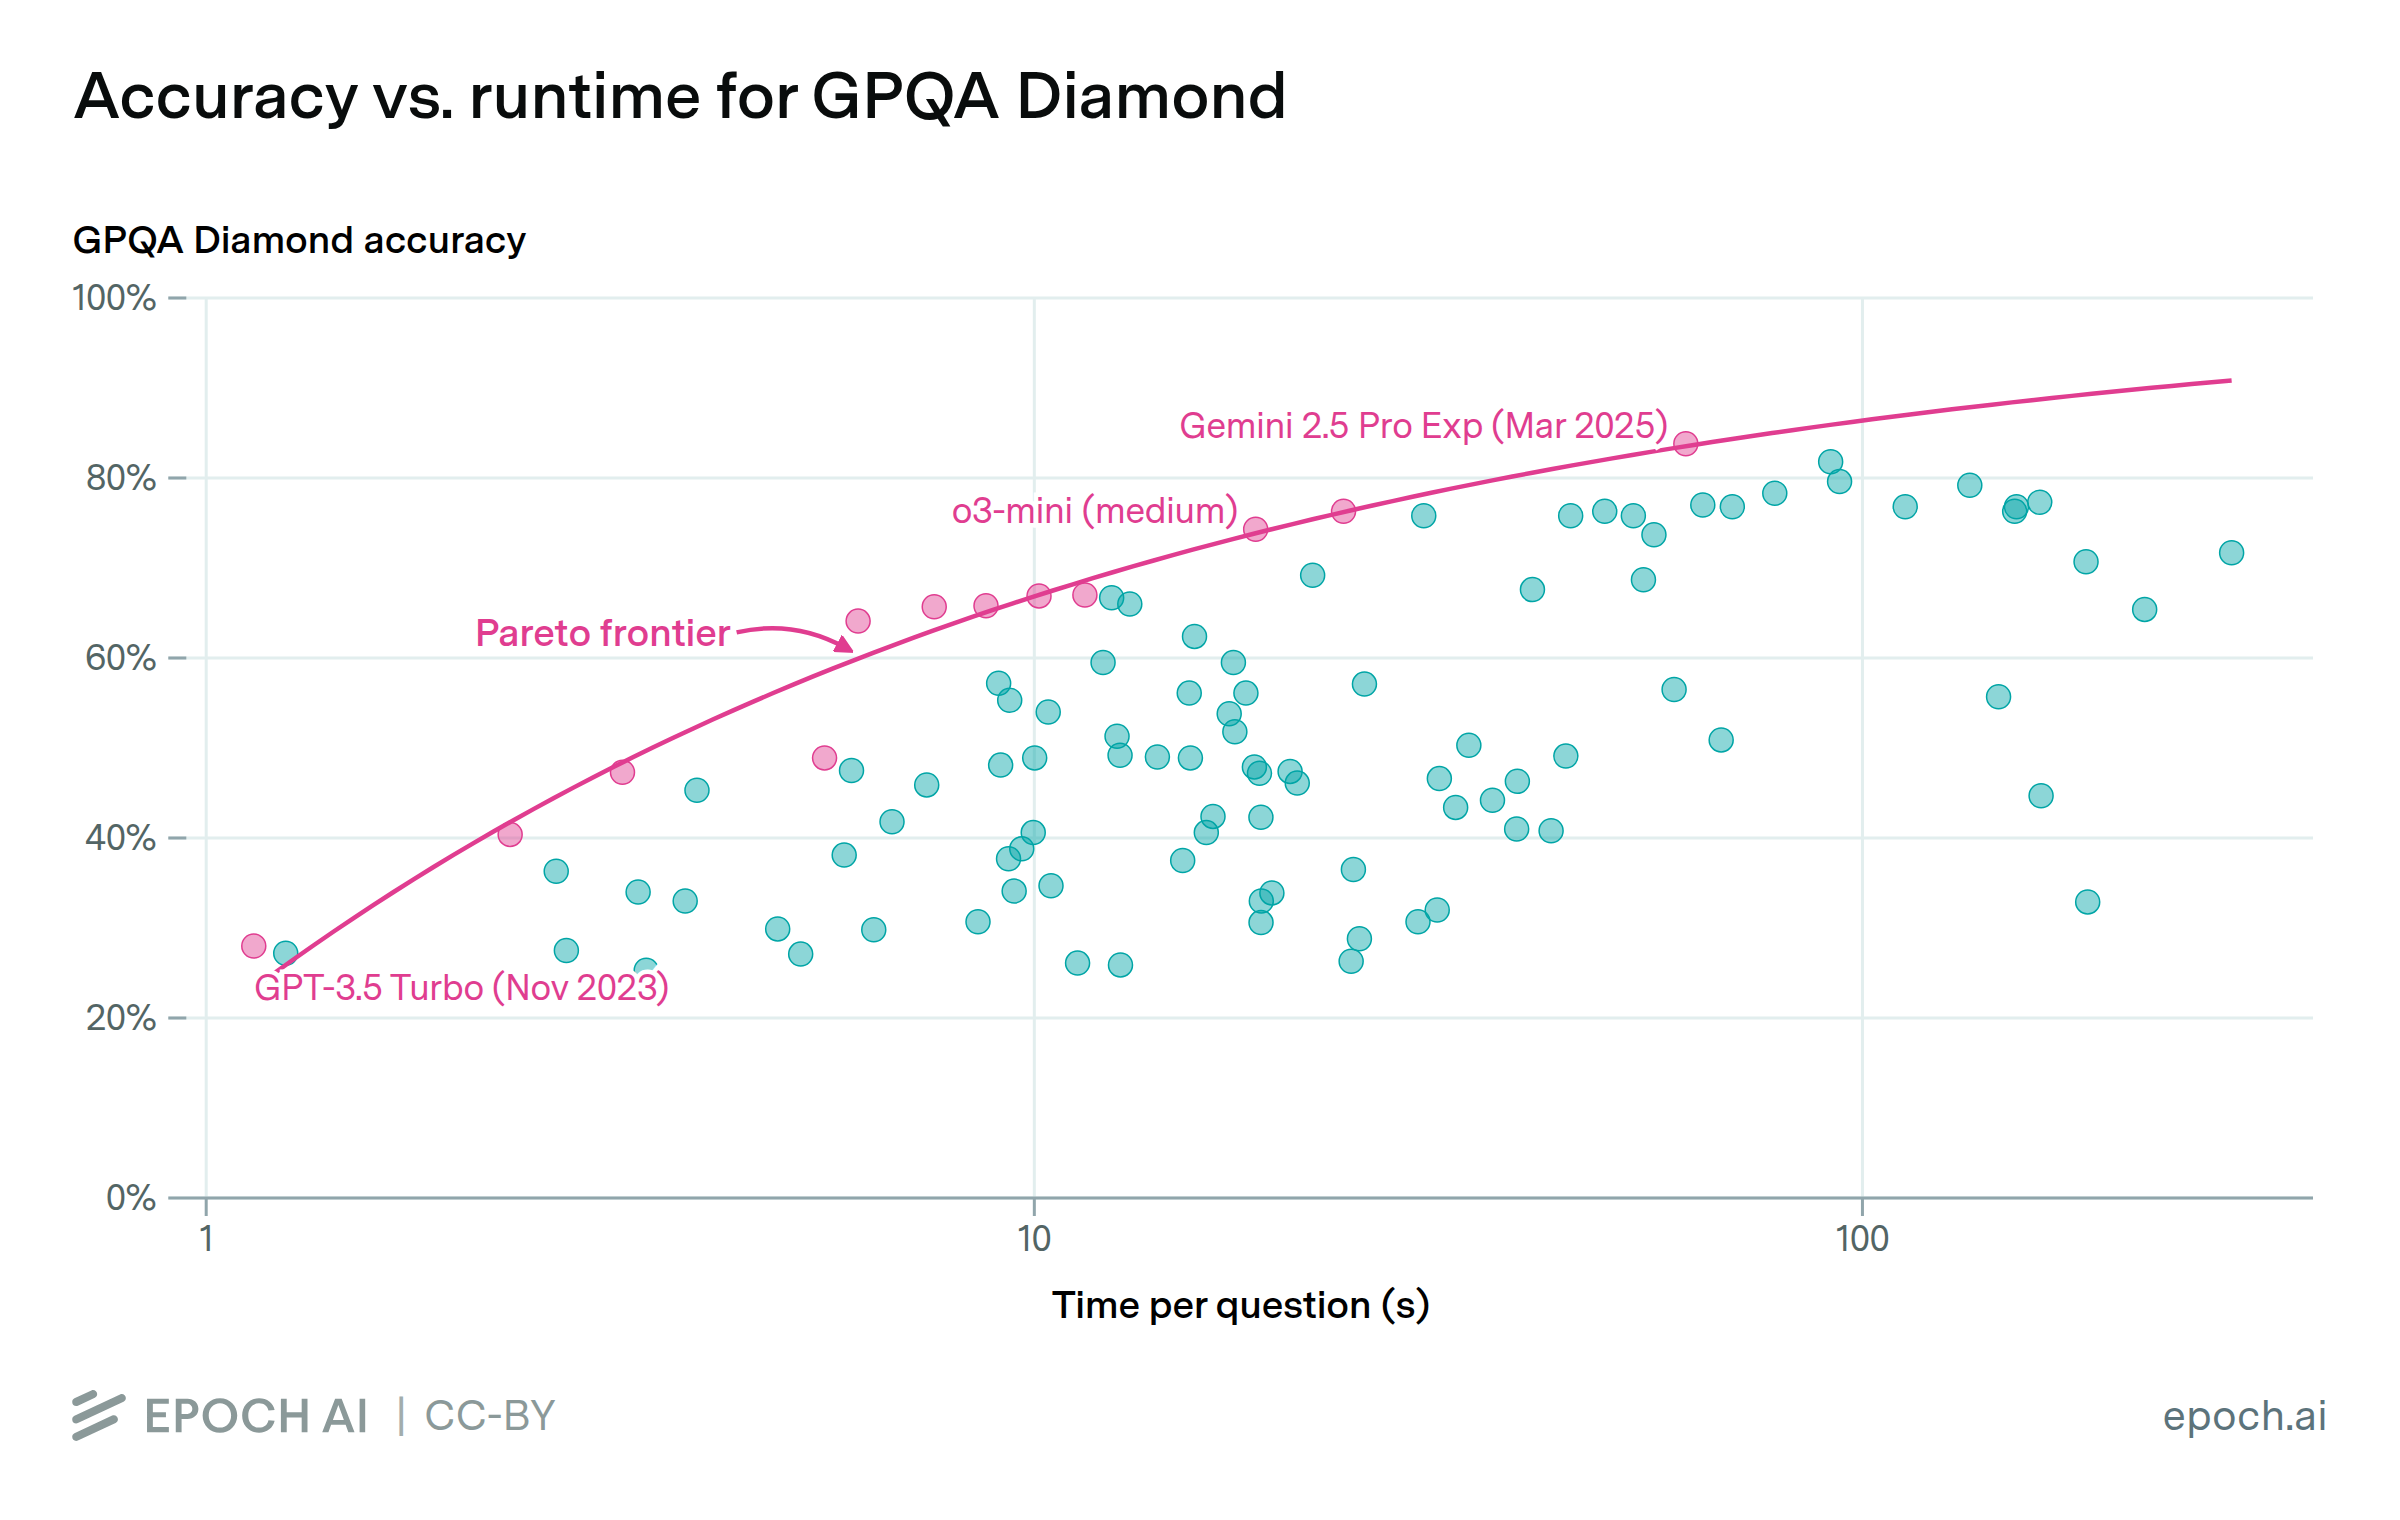
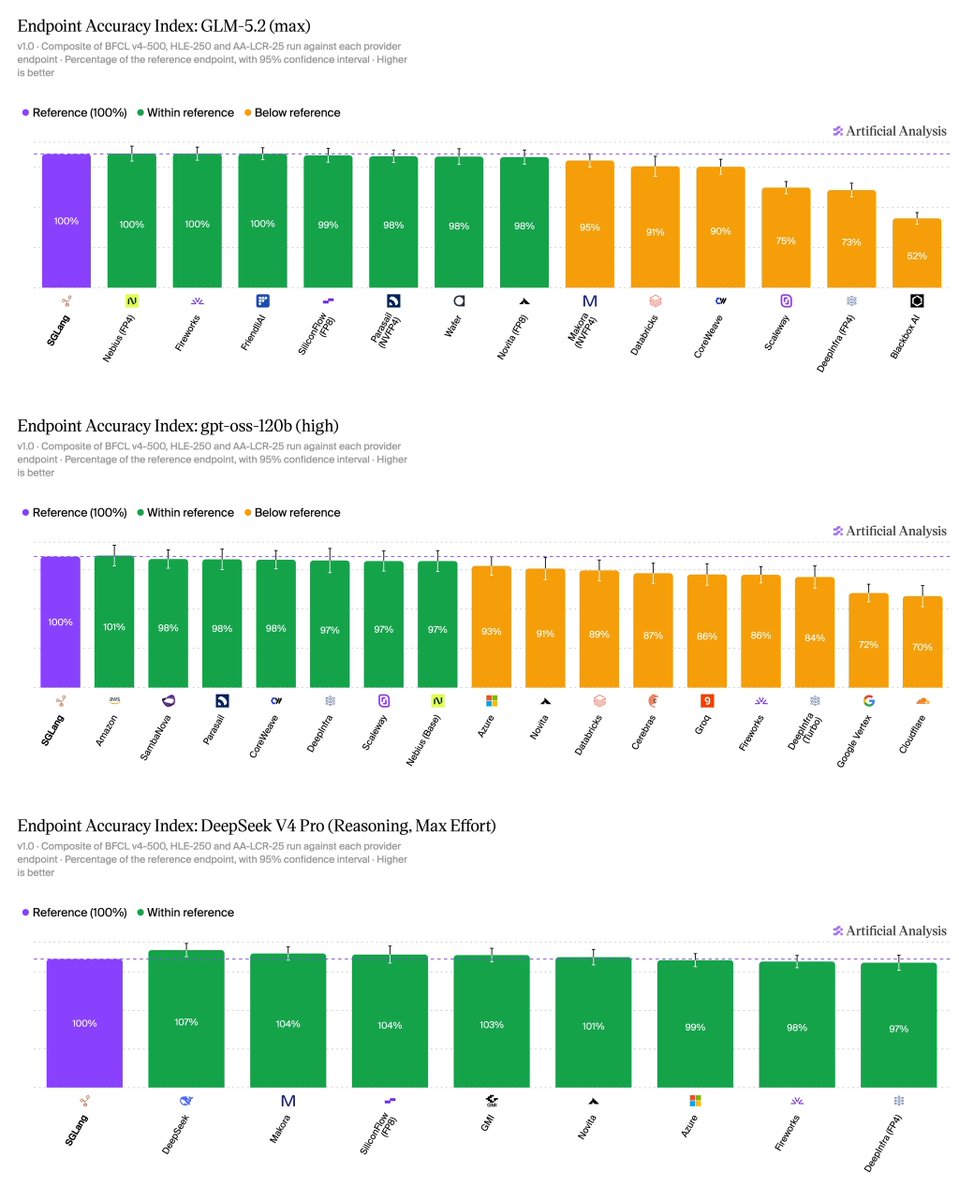
Halving a model's error rate typically costs 2x to 6x in runtime, which gives engineers a rule of thumb when trading latency against accuracy in LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → API selection.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.